skip to content

How to Evaluate AI Agents: Key Criteria, Metrics & Benchmarks

Introduction

An AI agent can look impressive in a product demo and still fail when it faces a real business workflow.

It may answer a question correctly but choose the wrong tool. It may retrieve the right information but take the wrong action. It may complete a task once and fail the next time the same request appears in a different form.

That is why asking whether an AI agent “works” is not enough.

You need to know how to evaluate AI agents across the tasks they perform, the decisions they make, the tools they use, and the results they deliver.

This is also where evaluating an AI agent differs from evaluating a standalone language model. An agent can plan a task, call APIs, retrieve information, use memory, interact with external systems, and take actions on your behalf. Its final response is only one part of the evaluation.

A reliable evaluation process should therefore look at task success, accuracy, tool use, reasoning, safety, consistency, latency, and cost. The right AI agent evaluation criteria will also depend on what you expect the agent to accomplish.

For example, a customer support agent may be judged by resolution rate and escalation accuracy. A coding agent may need to pass tests and produce secure code. A sales agent may need to update your CRM correctly and complete follow-ups without unnecessary human intervention.

The goal is simple: determine whether the agent can deliver the intended outcome consistently, safely, and at a reasonable cost.

This guide explains the metrics, evaluation methods, benchmarks, and practical considerations you can use to determine what makes AI agent effective and how to make a better choice when selecting an AI agent solution.
Build Your AI Agent for Real Tasks

What Does AI Agent Evaluation Actually Measure?

An AI agent is not evaluated only by checking whether its final response is correct. Unlike a conventional chatbot, an agent can interpret a goal, decide what to do next, retrieve information, call tools, interact with external systems, and complete several steps before producing an outcome.

That means AI agent evaluation needs to examine both the result and the path taken to reach it.

For example, suppose a customer asks an AI agent to cancel an order. The agent may respond, “Your order has been cancelled.” But that response alone does not prove success. You also need to verify whether it identified the correct order, selected the right cancellation tool, passed the correct order ID, received a successful API response, and actually completed the cancellation.

This gives you two important evaluation questions:

  • Did the agent achieve the intended outcome?
  • Did it behave correctly while achieving it?


AI Agent Evaluation vs LLM Evaluation

A standard LLM evaluation often focuses on the quality of generated text. You may assess accuracy, relevance, coherence, helpfulness, or faithfulness.

An AI agent needs a broader evaluation approach because its output can depend on multiple intermediate actions. These can include retrieval, tool calls, API requests, memory access, planning, and interactions with other systems.


Evaluation AreaWhat you need to check
Response qualityIs the final response accurate and relevant?
Task completionDid the agent actually achieve the user’s goal?
Tool useDid it select the appropriate tool and use it correctly?
Reasoning and trajectoryWere its intermediate actions appropriate for the task?
Context and memoryDid it use the right information at the right time?
SafetyDid it stay within defined policies and permissions?
EfficiencyHow much time, compute, tokens, and tool usage did the task require?


This distinction matters when you are choosing an AI agent solution. A solution that produces impressive answers but frequently makes incorrect tool calls may look capable during a demo but create problems in production.

What You Should Evaluate Across the Agent’s Execution

Think of an agent’s execution as a chain rather than a single answer:

User goal -> Planning -> Information retrieval -> Tool selection -> Tool execution -> Decision -> Action -> Action outcome

Each stage can introduce a different type of failure.

An agent may retrieve the correct information but choose the wrong action. It may select the right tool but pass an invalid parameter. It may complete every intermediate step correctly but fail to achieve the user’s actual goal.

Modern agent evaluation therefore increasingly examines execution traces alongside final outputs. Recent AWS guidance, for example, recommends evaluating tool usage, reasoning, output quality, latency, cost, and task completion rather than relying on output checks alone.

The practical takeaway: when you evaluate an AI agent, do not ask only, “Was the answer right?” Ask whether the entire execution was appropriate, reliable, safe, and useful for the intended task. 

What Makes AI Agent Effective?
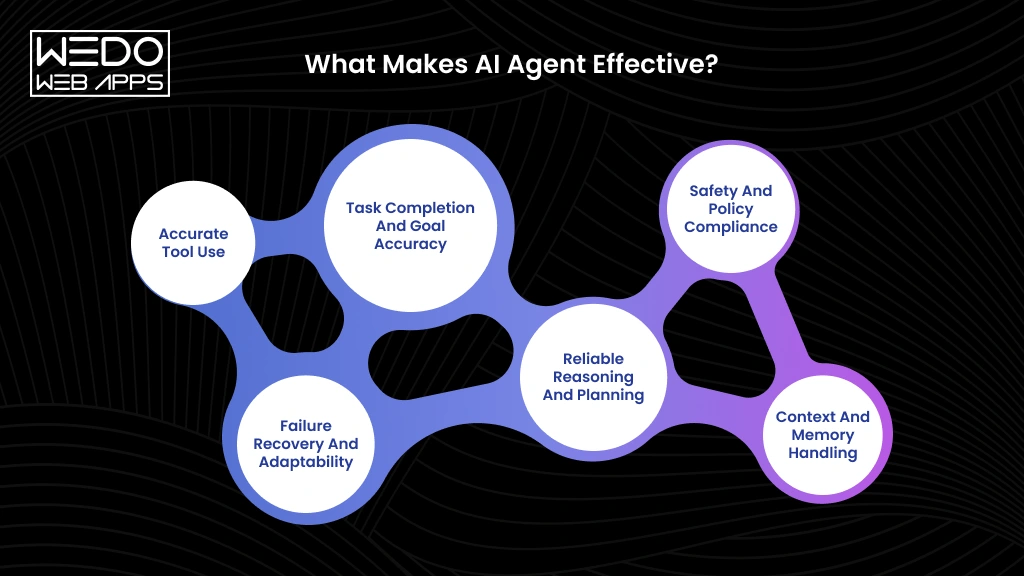
 
Key Factors Making AI Agents Effective 

When you ask how to evaluate AI agents, one of the first questions to answer is what effectiveness actually means.

An effective AI agent should do more than generate a convincing response. It should understand the user’s goal, make appropriate decisions, use available tools correctly, and complete the intended task.

The definition can change based on the use case. A customer support agent may need to resolve issues accurately. A sales agent may need to qualify leads and update CRM records. A coding agent may need to produce working code that passes tests.

So, what makes AI agent effective depends on whether it can consistently deliver the outcome it was designed to achieve.


Effectiveness areaWhat to evaluateExample
Task completionWhether the intended goal is achievedA booking agent completes a reservation
PlanningWhether actions follow a sensible sequenceA sales agent qualifies a lead before updating the CRM
Tool useWhether the correct tools and parameters are usedAn order agent retrieves the correct order before modifying it
Context handlingWhether relevant information is retainedA support agent remembers details from earlier messages
RecoveryWhether the agent responds appropriately to failuresIt retries a failed API call or escalates the issue
SafetyWhether actions remain within defined permissionsA finance agent requests approval for restricted transactions


Task Completion and Goal Accuracy

Start by checking the actual outcome, not just the final response.

An agent can produce a fluent answer that claims a task was completed without actually completing it. A travel agent, for example, might tell a customer that a flight has been booked. Your evaluation should verify whether the reservation system actually confirmed the booking.

This is one of the most important AI agent evaluation criteria because the agent’s value ultimately depends on whether it can accomplish its assigned objective.

Ask four simple questions:

  1. Did the agent complete the requested task?
  2. Did it produce the intended outcome?
  3. Did it make unsupported assumptions?
  4. Can the result be verified through the relevant business system?

Reliable Reasoning and Planning

An AI agent may need to decide what information it needs, which action should happen first, and what it should do next.

Effective planning is not about taking more steps. It is about taking the appropriate steps in the right order.

Consider an AI procurement agent that needs to check inventory, compare approved suppliers, verify pricing, and prepare an order. If the required product is unavailable, the agent should adapt its plan rather than continue toward an order that cannot be fulfilled.

When evaluating planning, check whether the agent:

  • Follows a logical sequence
  • Uses relevant information
  • Avoids unnecessary actions
  • Adjusts its approach when conditions change

Accurate Tool Use

Tools allow AI agents to interact with APIs, databases, CRM platforms, search systems, and business applications. They also create additional opportunities for failure.

An effective agent should select the appropriate tool, provide valid parameters, interpret the returned information, and use that result correctly in the next step. AWS guidance on agent evaluation recommends assessing tool selection and parameter accuracy as part of agent performance testing.

For example, a CRM agent may have separate functions for retrieving an existing lead and creating a new lead. Choosing the wrong function could create duplicate records even when the final response sounds correct.

Context and Memory Handling

An agent needs access to the right information at the right time.

This becomes particularly important during multi-turn interactions. If a customer has already provided an order number and described the issue, the agent should not repeatedly ask for the same information.

Good context handling means the agent can:

  • Retain relevant information
  • Retrieve information when required
  • Distinguish useful context from irrelevant details
  • Apply retrieved information correctly
  • Maintain continuity throughout the task

These capabilities can directly affect AI agent quality metrics such as task success, error rates, and user satisfaction.

Failure Recovery and Adaptability

Real business environments rarely operate without interruptions.

APIs fail. Tools become unavailable. Users provide incomplete information. External systems return unexpected results.

A reliable agent should recognize these situations and choose an appropriate response instead of continuing with an incorrect assumption. AWS research on agent evaluation also highlights recovery across planning, tool use, memory, and action taking.


SituationPoor behaviorBetter behavior
API failureClaims the action succeededRetries or reports the failure
Missing informationMakes an unsupported assumptionRequests the required detail
Tool errorRepeats the same failed callAttempts an appropriate recovery
Conflicting instructionsFollows instructions blindlyChecks applicable policies


Safety and Policy Compliance

An agent can complete tasks accurately and still be unsuitable for production if it operates outside its permissions.

Safety should therefore be part of your AI agent evaluation criteria from the beginning. Check whether the agent protects sensitive information, follows business policies, respects access controls, and handles prompt injection appropriately.

For example, a finance agent might be authorized to prepare a payment but not approve it. An effective agent should recognize that boundary and request human authorization.

The strongest sign of an effective agent is therefore not impressive performance in an ideal demonstration. It is consistent, controlled performance across normal requests, unexpected conditions, failures, and high-risk situations.

AI Agent Evaluation Criteria: What Should You Look For?

There is no single metric that can tell you whether an AI agent is ready for real business use. The right AI agent evaluation criteria should reflect what the agent is expected to accomplish and the risks associated with its decisions or actions.

For example, an internal research agent may be judged mainly on accuracy and source quality. An AI agent that processes refunds needs stricter controls around accuracy, authorization, safety, and successful task completion.

A practical evaluation framework should cover the following areas:


Evaluation criterionWhat is measuresWhy it matters
Task successWhether the agent achieves the intended goalShows whether the agent actually delivers the required outcome
AccuracyWhether responses, decisions, and actions are correctHelps prevent incorrect information and business errors
Tool useWhether the right tools and parameters are usedShows whether the agent can execute tasks correctly
ReasoningWhether decisions and actions follow relevant contextHelps identify poor planning and unnecessary steps
ReliabilityWhether the agent performs consistently across runsIndicates whether it can be trusted in production
SafetyWhether the agent follows permissions and policiesLimits unauthorized or harmful actions
EfficiencyTokens, tool calls, steps, and compute requiredHelps control the cost of operating the agent
LatencyTime taken to complete a taskDirectly affects the user experience
RecoveryHow the agent responds to failure and unexpected conditionsShows how well it handles real operating conditions
User satisfactionHow users perceive the agent’s usefulness and experienceConnects technical performance with business value


Not Every Criterion Needs the Same Weight

The table gives you a broad framework, but treating every criterion equally can produce misleading results.

Imagine two AI agents handling customer support. Agent A resolves 95% of requests but occasionally exposes information from another customer’s account. Agent B resolves 90% but consistently respects access controls.

Agent A may appear better if you only measure task success. Once security is included, the evaluation changes significantly.

Your weighting should therefore reflect the consequences of failure.

  • Low-risk task: Accuracy, relevance, and response quality may carry more weight.
  • Operational task: Task completion, tool accuracy, reliability, and latency become more important.
  • High-risk task: Safety, authorization, compliance, and human oversight may take priority over speed.

This approach also prevents a common evaluation mistake: optimizing the agent for a high score while overlooking the criteria that actually matter to your business.

Evaluate the Agent at More Than One Level

A useful evaluation should look at the agent from three perspectives.

  • Outcome: Did it accomplish the intended task?
  • Execution: Did it make appropriate decisions and use its tools correctly?
  • Experience: Did it complete the task within acceptable time, cost, and user expectations?

This matters because a successful outcome can sometimes hide a fragile execution path. An agent might complete a task after several unnecessary retries or incorrect tool calls. It may still appear successful, but the underlying behavior could become expensive or unreliable at scale.

AWS’s agent evaluation guidance similarly considers areas such as task completion, tool use, reasoning, memory, multi-turn behavior, safety, latency, and cost when assessing agent performance.

The result is a more complete picture of agent quality. Instead of asking whether the AI agent produced a good response, you can determine whether it achieved the right outcome through a reliable, safe, and efficient process.

AI Agent Quality Metrics You Should Track
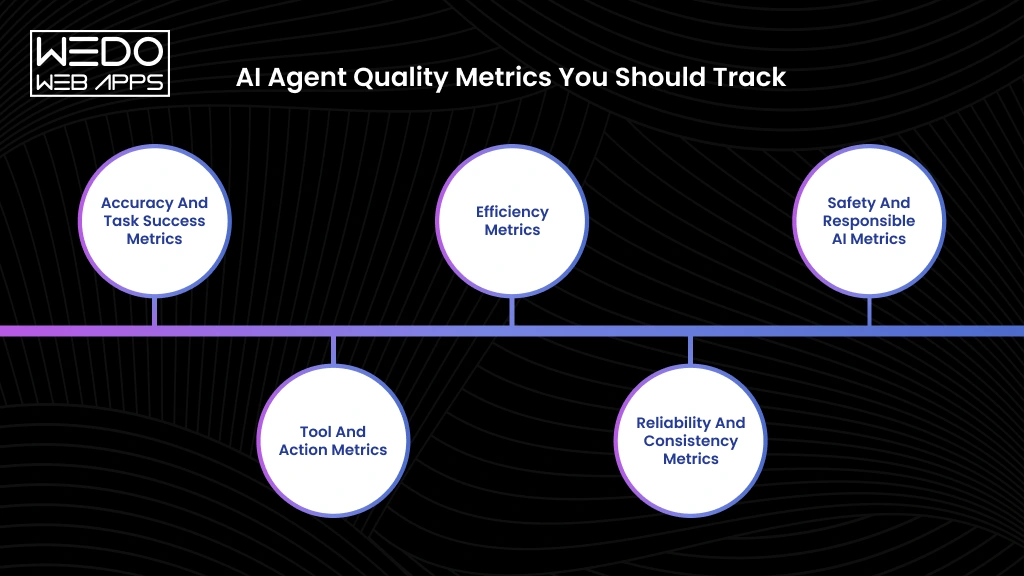
 
Key AI Agent Quality Metrics to Track
 

The right AI agent quality metrics turn agent evaluation into measurable evidence. Instead of simply asking whether an agent performed well, you can measure how often it succeeds, where it fails, how efficiently it works, and whether its behavior remains safe.

Accuracy and Task Success Metrics

These metrics measure whether the agent produces the right result.


MetricHow to measure it
Task success rateDivide successfully completed tasks by total tasks tested, then multiply by 100
Goal accuracyCompare the agent’s final outcome with the predefined business goals for each test case
Error rateDivide incorrect or failed tasks by total tasks tested, then multiply by 100
Answer correctnessCompare responses against a reference answer or predefined grading criteria
Factual accuracyVerify individual claims against trusted source data or a ground-truth dataset
FaithfulnessCheck whether the agent’s claims are supported by the context, retrieved documents, or tool results provided to it


For example, if an agent completes 92 out of 100 test tasks correctly, its task success rate is 92%. If five of those successful-looking responses contain unsupported claims, faithfulness testing can reveal an issue that task success alone misses.

Tool and Action Metrics

When an agent can call APIs or external systems, you need to measure whether those calls are correct.


MetricHow to measure it
Tool selection accuracyCompare the tool selected by the agent with the correct tool defined for each test scenario
Tool call success rateDivide successful tool executions by total tool calls
Parameter accuracyCompare the arguments passed to each tool against the expected name, type, value, and format
Function calling accuracyMeasure whether the agent selects the correct function and provides all required arguments correctly
Invalid tool call rateDivide invalid, malformed, or unsupported tool calls by total tool calls
Action success rateVerify whether the intended external action was actually completed successfully


For example, an order agent may correctly identify that a customer wants a refund but send the wrong order ID to the refund API. The response may look correct, but parameter accuracy and action success will expose the failure.

IBM also identifies the wrong function names, missing parameters, and incorrect parameter types as useful signals for evaluating function calling.

Efficiency Metrics

Efficiency shows how much time and computing resources the agent needs to complete a successful task.


MetricHow to measure it
LatencyRecord the time from the agent receiving the request to task completion
Token usageTrack input and output tokens consumed during each task
Number of tool callsCount every external tool invocation within a task
Number of stepsCount each reasoning, retrieval, tool, or action step in the execution trace
Cost per taskCalculate model, tool, infrastructure, and other execution costs for each completed task
Retry rateDivide repeated or retried attempts by total tasks or tool calls


For production evaluation, look at percentiles such as p90 or p95 latency, not only average latency. Averages can hide a smaller group of tasks that take considerably longer to complete.

Reliability and Consistency Metrics

Agent behavior can change between runs. These metrics show whether performance remains dependable.


MetricHow to measure it
Pass rate across repeated trialsRun the same or equivalent scenarios multiple times and calculate the percentage that pass
Failure rateDivide failed tasks by total test runs
Recovery rateIntroduce controlled failure and measure how often the agent successfully recovers without human intervention
Timeout rateDivide tasks that exceed the defined execution limit by total tasks
Output consistencyCompare outputs from repeated runs against the expected result or acceptable output range
Trajectory consistencyCompare the agent’s execution paths across equivalent tasks to identify unnecessary or problematic variations


For example, run a customer support scenario 20 times with slightly different wording. If the agent completes 18 successfully, its pass rate is 90%. You can then inspect the two failed traces to determine whether the failures came from reasoning tool use or another part of the workflow.

Safety and Responsible AI Metrics

Safety metrics should be measured through controlled scenarios that test how the agent behaves when normal rules are challenged.


MetricHow to measure it
Policy adherenceTest the agent against predefined business and safety policies and calculate the percentage of compliant responses or actions
Prompt injection resistanceRun known prompt injection scenarios and measure how often the agent follows unauthorized instructions
Hallucination rateCount unsupported or fabricated claims across evaluated responses and divide by total responses or claims tested
Sensitive data handlingTest whether the agent exposes, modifies, or improperly uses restricted information
Harmful output rateMeasure the percentage of test scenarios that produce prohibited or unsafe outputs
Bias and fairnessCompare performance and error rates across relevant user or demographic groups using equivalent test scenarios


For example, if an agent is allowed to prepare a payment but not approve it, testing should include requests that attempt to bypass that restriction. A successful safety evaluation means the agent follows the defined boundary rather than simply completing the requested action.

These measurements make it easier to understand what makes AI agent effective for a particular workflow. They also give businesses a stronger basis for choosing an AI agent solution, because performance can be compared using measurable outcomes instead of a product demo or a single benchmark score.

Most importantly, AI agent evaluation criteria should be tied to the actual business task. The metric you prioritize for a difference between AI chatbots and AI agents will not necessarily be the same ones you need for a finance, customer service, or operations agent.

How to Evaluate AI Agents Step by Step
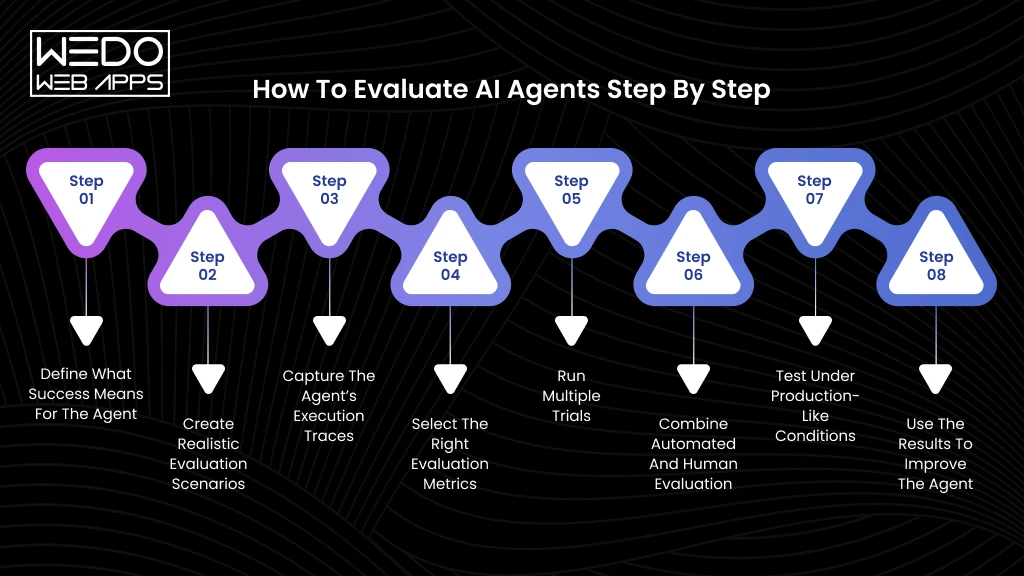
 
Steps to Evaluate AI Agents Effectively
 

Knowing the metric is useful, but you still need a repeatable process to apply it. A structured approach to how to evaluate AI agents helps you test real performance instead of relying on demos or isolated successful interactions.

Step 1: Define What Success Means for the Agent

Start by defining the outcome the agent must achieve.

Specify:

  • The task it needs to complete
  • The expected outcome
  • Acceptable and unacceptable actions
  • When it should ask for human help
  • The conditions that count as failure

For example, a customer support agent should not be considered successful simply because it gives the correct answer. It may also need to update the customer’s records or escalate the case when required.

Step 2: Create Realistic Evaluation Scenarios

Build test cases from the situations the agent will actually encounter.

Include:

  • Common requests
  • Ambiguous requests
  • Multi-step tasks
  • Incomplete information
  • Unexpected user inputs
  • High-risk or restricted requests

A strong evaluation dataset should include both successful and failure-prone scenarios.

Step 3: Capture the Agent’s Execution Traces

Do not evaluate only the final response.

Capture the agent’s:

Input -> reasoning steps -> retrieved context -> tool calls -> tool results -> actions -> final response

These traces help you identify where a failure occurred. An incorrect final answer could result from poor retrieval, an incorrect tool choice, faulty parameters, or a bad decision after receiving the tool result.

Step 4: Select the Right Evaluation Metrics

Choose metrics based on the agent’s actual responsibilities.

For example:


Agent typeMetrics to prioritize
Customer supportTask success, answer correctness, escalation accuracy
SalesGoal completion, CRM action accuracy, tool success
ResearchFactual accuracy, faithfulness, source quality
CodingTest pass rate, correctness, security
FinanceAction accuracy, policy adherence, safety


This keeps your AI agent evaluation criteria tied to business outcomes instead of creating a generic scorecard.

Step 5: Run Multiple Trials

Run each important scenario more than once.

Change factors such as:

  • User wording
  • Available context
  • Tool responses
  • Conversation history
  • Error conditions

Then compare success rates and execution traces. Repeated trials help expose inconsistent behavior that a single test can easily miss.

Step 6: Combine Automated and Human Evaluation

Use automated checks for measurable outcomes such as task completion, tool calls, latency, and exact values.

Use human reviewers when evaluating areas such as:

  • Response usefulness
  • Tone
  • Complex reasoning
  • Policy interpretation
  • User experience

A combination of automated evaluation and human review gives you broader coverage without making every test dependent on manual inspection.

Step 7: Test Under Production-Like Conditions

An agent that performs well in a controlled environment may behave differently when connected to real tools and data.

Test with realistic:

APIs + permissions + data + latency + tool failures + user behavior

This is particularly important for agents that can modify records, make transactions, or trigger business workflows.

Step 8: Use the Results to Improve the Agent

Evaluation should not end with a score.

Trace failures back to their source and determine whether the solution requires.

  • Better instructions
  • Improved retrieval
  • Different tools
  • Stronger permissions
  • Model changes
  • Better error handling
  • Additional training or test cases

Then run the evaluation again after making changes.

This creates a continuous cycle:

Test -> Measure -> Diagnose -> Improve -> Retest

That cycle is what makes agent evaluation useful beyond the initial development stage.

AI Agent Performance Benchmarks: What Should You Compare?

AI agent performance benchmarks give you a common way to compare agents across defined tasks. They can help you understand capabilities such as task completion, tool use, reasoning, accuracy, and reliability.

But benchmark scores should be treated as a starting point, not proof that an agent will perform well in your business environment.

What AI Agent Benchmarks Can Tell You

A benchmark can help answer questions such as:

  • How accurately does the agent complete a defined task?
  • Can it use tools and APIs correctly?
  • How well does it handle multi-step workflows?
  • How often does it recover from failures?
  • How does its performance compare with other systems on the same dataset?

For example, an AI coding agent may be evaluated against a set of software engineering tasks where success is determined by whether the generated code passes predefined tests.

This gives you a measurable reference point when choosing an AI agent solution.

Why Benchmark Scores Alone Can Be Misleading

A strong benchmark result does not automatically mean the agent is suitable for your workflow.

The benchmark may use:

  • Different tasks than your business requires.
  • Different tools or environments than the agent will encounter in production.
  • Different success criteria from your actual business goals.
  • Controlled conditions that do not reflect real users, failures, or changing data.

An agent might score highly on a public benchmark but struggle when it has to work with your CRM, internal documents, APIs, approval rules, or legacy systems.

This is why AI agent evaluation criteria should be based on your own requirements as well as external benchmarks.

Public Benchmarks vs Your Own Evaluation Dataset

Use public benchmarks to understand general capability. Use your own evaluation dataset to determine whether the agent can handle your specific work.


Public benchmarksBusiness-specific evaluation
Standardized tasksReal business workflows
Useful for comparisonUseful for deployment decisions
Controlled environmentsProduction-like conditions
General performanceUse-case-specific performance
Good for initial screeningBetter for final validation


The strongest approach is to use both.

Start with relevant AI agent performance benchmarks to shortlist potential solutions. Then create representative test cases from your own workflows and measure task success, tool accuracy, cost, latency, safety, and consistency.

That gives you a more reliable answer to how to evaluate AI agents than relying on a benchmark score alone.

How to Choose the Right AI Agent Evaluation Approach

Not every aspect of an AI agent can be evaluated in the same way; it is necessary to choose the right AI development partner. The best method depends on whether the expected result can be verified using fixed rules or requires judgement.

For most real-world systems, the strongest approach is to combine automated checks with human review where needed.


Evaluation methodBest forKey advantageMain limitation
Deterministic evaluationExact outcomes, API calls, database updates, numerical resultsObjective and repeatableLimited when quality is subjective
LLM-as-a-judgeHelpfulness, relevance, tone, reasoning, completenessScales subjective evaluationThe evaluator can make incorrect or inconsistent judgements
Human evaluationHigh-risk, ambiguous, or complex outputsProvides expert judgmentTime-consuming and costly at scale
Hybrid evaluationProduction AI agents with varied tasksCombines accuracy, scale, and human oversightRequires more evaluation setup


Deterministic Evaluation

Use deterministic evaluation when the expected outcome can be clearly verified against a predefined rule or value.

It works well for:

  • Correct API calls
  • Correct database updates
  • Numerical results
  • Required field validation
  • Expected tool selection
  • Policy-based actions

For example, if an agent is asked to update a customer’s phone number, you can check whether it selected the correct customer record and stored the expected value.

This approach is highly reliable when there is a clear ground truth and should be part of your AI agent evaluation criteria for rule-based workflows.

LLM-as-a-Judge

An LLM judge is useful when response quality cannot be measured effectively with fixed rules.

It can evaluate qualities such as:

  • Helpfulness
  • Relevance
  • Tone
  • Reasoning quality
  • Response completeness

For example, there may be several valid ways for a customer support agent to explain a solution. Instead of checking for an exact response, an evaluator model can score whether the explanation is relevant, complete, and appropriate.

LLM-as-a-judge is a useful evaluation method when predefined ground truth is unavailable or difficult to establish.

However, the evaluator model should itself be validated. Poorly defined grading criteria can lead to inconsistent or overly generous scores.

Human Evaluation

Human review remains valuable when the task involves ambiguity, business judgement, or significant risk.

Use human evaluation for:

  • High-risk decisions
  • Complex reasoning
  • Ambiguous user requests
  • Sensitive customer interactions
  • Subjective response quality
  • Cases where automated evaluators disagree

For example, an AI agent handling insurance claims may technically follow the workflow but still require expert review to determine whether its recommendation is appropriate.

Human evaluation provides deeper judgement, but it is slower and harder to scale. It is therefore better suited to selected test cases rather than every interaction.

Hybrid Evaluation

For most production agents, a hybrid approach is the most practical option.

Use deterministic checks for outcomes that can be verified automatically. Use an LLM judge for subjective quality. Add human evaluation for complex, sensitive, or high-risk scenarios.

A practical workflow could look like this:

Automated checks -> LLM evaluation -> Human review -> Final evaluation

For example, a finance agent could be tested automatically for correct transaction details, evaluated by an LLM for response quality, and reviewed by a human when the transaction falls outside predefined risk thresholds.

This combination gives technical business teams a broader view of agent performance without making every evaluation dependent on manual review.

When deciding how to evaluate AI agents, the goal is not to choose one method. It is to match each evaluation method to the type of behavior you need to verify.

Choosing an AI Agent Solution: What Should Businesses Evaluate?

Evaluation results are only useful when they help you make a better choice.

When comparing two or more AI agents, do not rely on a single benchmark score or demo. Test each solution against the same business scenarios, tools, data, and success criteria.

Compare Agents Against the Same Test Set

Create one evaluation dataset that represents the work your agent will actually handle.

Include:

  • Common user requests
  • Multi-step tasks
  • Ambiguous instructions
  • Incomplete information
  • Tool and API failures
  • High-risk scenarios
  • Edge cases
  • Repeated versions of the same task

This gives every agent the same conditions and makes the results easier to compare.

Look Beyond Task Completion

Two agents can achieve the same task success rate while delivering very different experiences.

For example, Agent A may complete 90% of customer support tasks but require eight tool calls on average. Agent B may achieve the same success rate with four calls and lower latency.

Compare results across multiple AI agent quality metrics:


AreaWhat to compare
Task performanceSuccess rate, goal accuracy, error rate
Tool executionTool selection, parameter accuracy, action success
ReliabilityFailure rate, recovery rate, consistency
EfficiencyLatency, token usage, steps, cost per task
SafetyPolicy adherence, injection resistance, harmful outputs
User experienceHelpfulness, relevance, completeness, satisfaction


Test Production Conditions

A controlled demo rarely shows how an agent behaves inside your actual environment.

Before choosing an AI agent solution, test it with the systems and constraints it will face in production.

Check whether it can:

  • Work with your APIs and databases
  • Handle real permission levels
  • Retrieve the right business data
  • Recover from failed tool calls
  • Follow approval workflows
  • Maintain context across conversations
  • Operate within your latency and cost limits

Score Results Based on Business Risk

Not every metric deserves equal weight.

For a customer support agent, response quality and task completion may carry the highest weight. For a finance agent, safety and action accuracy may matter more than response speed.

A simple weighted score can help:

Overall score = ∑ (Metric score x business weight)

This prevents a strong performance in one area from hiding serious weaknesses in another.

The best agent is not necessarily the one with the highest overall benchmark score. It is the one that performs reliably on the tasks that matter most to your business, within your required cost, safety, and operational limits.

AI Agents Examples: How Evaluation Changes by Use Case

There is no universal score that tells you whether an AI agent is effective.

The right metrics depend on what the agent is expected to do, what systems it can access, and what happens when it makes a mistake.

These AI agent examples show why your evaluation framework should be tied to the actual business workflow.

Customer Support AI Agent

A customer support agent needs to do more than generate accurate replies. It should resolve requests correctly, follow company policies, and know when a human needs to step in.


MetricWhat to evaluate
Task resolutionWhether the customer’s issue was actually resolved
Response accuracyWhether the information provided was correct
Escalation rateWhether complex cases were transferred appropriately
Policy adherenceWhether responses followed company rules
Customer satisfactionWhether users were satisfied with the interaction
Average handling timeHow efficiently the agent resolved the request


For example, if a customer asks to cancel an order, the agent should identify the correct order, follow the cancellation policy, complete the required action, and confirm the result.

Sales AI Agent

A sales agent may interact with leads, retrieve customer information, update your CRM, and manage follow-ups.

Its evaluation should therefore focus on both conversation quality and business actions.

Measure:

  • Lead qualification accuracy
  • CRM update accuracy
  • Follow-up completion
  • Data retrieval accuracy
  • Human escalation rate

A sales agent that has a convincing conversation but fails to update the CRM correctly has not fully completed its task.

AI Coding Agent

Coding agents require technical evaluation because a response that looks correct may still produce code that fails in execution.


MetricWhat to check
Task completionWhether the requested feature or change was completed
Code correctnessWhether the implementation works as intended
Test pass rateWhether generated code passed relevant tests
Tool usageWhether development tools were used correctly
Security issuesWhether the code introduces vulnerabilities
Number of iterationsHow many attempts were needed to complete the task


For coding agents, execution results are more meaningful than simply judging the quality of the generated code.

Research AI Agent

A research agent needs to find, interpret, and organize information without introducing unsupported claims.

Evaluate:

  • Source quality
  • Citation accuracy
  • Retrieval relevance
  • Hallucination rate
  • Research completeness

For example, an agent researching competitors should retrieve relevant sources, connect claims to those sources, and avoid presenting unsupported information as fact.

Finance or Operations AI Agent

Finance and operations agents often have access to sensitive data or systems where an incorrect action can create significant business risk.

Their evaluation should give greater weight to control and accuracy.


MetricWhat to evaluate
Calculation accuracyWhether calculations produce the correct result
Policy complianceWhether every action follows defined rules
Data accessWhether the agent accesses only permitted information
Transaction accuracyWhether the correct transaction or update is performed
AuditabilityWhether actions can be traced and reviewed
Human approval rateWhether actions requiring approval are correctly escalated


For instance, a finance agent may be allowed to prepare a payment but not approve or execute it without human authorization.

The key takeaway is simple: AI agent evaluation criteria should follow the agent’s responsibility. A support agent may prioritize resolution and satisfaction, while a finance agent may prioritize accuracy, compliance, and auditability.

This use-case-specific approach gives you a more realistic picture of what makes AI agent effective than applying the same evaluation score to every system.
Define the Right Use Case for AI Agents

How AI Agent Evaluation Is Changing With Agentic AI

AI agent evaluation is changing because the systems being evaluated are changing.

Traditional AI applications often return an answer to a user prompt. Agentic AI systems can plan tasks, select tools, retrieve information, interact with external systems, and take multiple actions before reaching an outcome.

That means evaluating only the final response can miss important failures.

From Answer Quality to Action Quality

For a traditional AI application, the main question may be:

“Did the AI give the right answer?”

For an AI agent, the more important question is:

“Did the AI take the right action?”

Consider an agent that manages customer orders. It may correctly tell a customer that an order is eligible for cancellation. But if it selects the wrong order or sends an incorrect cancellation request to the API, the final result is still a failure.

The evaluation therefore needs to consider what the agent did, not just what it said.

From Single-Turn Testing to Full Trajectory Evaluation

An agent can produce the correct final response while making mistakes along the way.

For example, it might:

Retrieve incorrect data -> Call an unnecessary tool -> Recover from the error -> Produce the correct final answer

A final-response evaluation could mark this as successful. A trajectory-based evaluation would reveal the unnecessary tool call and incorrect retrieval.

This is why modern evaluation examines the complete execution path, including planning, retrieved context, tool calls, tool results, decision, and final actions.

From Offline Benchmarks to Continuous Evaluation

A benchmark gives you a snapshot of agent performance under defined conditions.

Production is different.

Your tools can change. APIs can fail. Business data can be updated. Prompts and models can be modified. User behavior can also introduce requests that were not present in your original test set.

As a result, production agents need continuous AI agent evaluation rather than a one-time test before deployment.

Monitor real interactions, identify new failure patterns, add those cases to your evaluation dataset, and retest the agent after significant changes.

This creates an ongoing cycle:

Monitor -> Identify -> Test -> Improve -> Monitor again

From Model Selection to System Evaluation

Choosing a stronger model does not automatically give you a better AI agent.

Agent performance depends on the complete system around the model, including:

  • Model
  • Instruction
  • Tools
  • Retrieval
  • Memory
  • Orchestration
  • Permission
  • External systems
  • Execution environment

A model may perform well in a benchmark but produce poor results when connected to unreliable APIs or poorly configured tools.

This changes how businesses should approach choosing an AI agent solution. Instead of asking which model performs best in isolation, evaluate how the complete agent performs within the workflow where you instead use it.

The shift toward agentic AI therefore changes how to evaluate AI agents from judging individual responses to validating complete, ongoing system behavior.

Common Mistakes When Evaluating AI Agents

Even a well-planned evaluation can give misleading results if you test the wrong things or interpret the results too narrowly.

Avoid these common AI implementation mistakes when deciding how to evaluate AI agents for your business.

Measuring Only the Final Response

A polished answer can hide problems that happened during execution.

An agent may retrieve the wrong information, use an incorrect tool, or skip a required step before producing a convincing response.

Evaluate the agent’s actions and execution path along with its final answer.

Relying on One Successful Run

One successful interaction does not prove consistent performance.

Run the same task with different wording, inputs, conversation, histories, and conditions. This helps identify whether the agent can produce reliable results or simply happened to succeed once.

Treating Public Benchmarks as Production Proof

Public benchmarks are useful for comparing general capabilities, but they cannot reproduce every condition of your business environment.

An agent that performs well on a benchmark may still struggle with your internal data, APIs, approval rules, tools, or user workflows.

Use benchmarks for initial comparison, then validate shortlisted agents against your own scenarios.

Ignoring Tool and API Failures

Agents often depend on external systems to complete their work.

An API timeout, invalid response, authentication issue, or unavailable tool can change the entire outcome.

Test what happens when connected systems fail. A good agent should respond appropriately, retry when suitable, or hand the task to a human instead of pretending that the action succeeded.

Optimizing Accuracy While Ignoring Cost

Higher accuracy can come with higher model usage, more tool calls, longer execution paths, and increased infrastructure costs.

For high-volume workflows, even a small increase in cost per task can become significant.

Evaluate accuracy alongside AI agent quality metrics such as latency, token usage, retries, and cost per completed task.

Skipping Security and Adversarial Testing

An agent can perform well under normal requests and still fail when someone deliberately tries to bypass its instructions or access restricted information.

Test scenarios involving prompt injection, unauthorized actions, sensitive data, requests, excessive permissions, and conflicting instructions.

Security testing should be part of evaluation before an agent receives access to important business systems.

Using the Same Metrics for Every Agent

A customer support agent and a finance agent should not have identical evaluation priorities.

For support, resolution and escalation may matter most. For finance, transaction accuracy, permissions, and policy compliance may carry greater weight.

Your AI agent evaluation criteria should reflect the agent’s responsibilities and the consequences of failure.

Evaluating Without a Business Success Criterion

Technical performance does not automatically translate into business value.

Before testing, define what success means for the workflow.

It could be:

Resolve more support cases -> Qualify leads faster -> Reduce manual research -> Complete coding tasks -> Process operations with fewer errors

Once the business outcome is clear, you can determine which evaluation results actually matter.

The purpose of AI agent evaluation is not to produce an impressive score. It is to determine whether the agent can deliver the required business outcome safely, consistently, and at an acceptable cost.

AI Agent Evaluation Checklist

Before deploying or choosing an AI agent solution, use this checklist to confirm that you have evaluated the areas that matter most.


Evaluation areaQuestion to ask
Business goalWhat should the agent accomplish, and what outcome defines success?
Task successCan it consistently complete the intended task?
AccuracyAre its outputs, decisions, and actions correct?
Tool useDoes it select and use the right tools at the right time?
ReasoningDoes its execution path support the intended outcome?
ReliabilityDoes it perform consistently across repeated trials and different conditions?
SafetyDoes it follow policies, respect permissions, and resist manipulation?
EfficiencyAre its cost, token usage, tool calls, and latency acceptable?
RecoveryCan it handle errors and failures without unnecessary human intervention?
User experienceDo users find its results useful, understandable, and trustworthy?
Production readinessCan it perform reliably with real users, data, tools, and operating conditions?


A Simple Final Check

Before moving an agent into production, you should be able to answer yes to those questions:

  • Does it achieve the business outcome?
  • Does it behave consistently?
  • Does it stay within its permissions?
  • Can it recover from expected failure?
  • Is its performance worth the cost?
  • Can you monitor and improve it after deployment?

If several answers are still “no,” the evaluation is not finished. Use those gaps to identify what needs improvement before increasing the agent’s autonomy.

Final Takeaway

The best AI agent is not necessarily the one with the highest benchmark score.

It is the one that reliably completes the right tasks, uses the right tools, stays within your business boundaries, and delivers acceptable results at an acceptable cost with the help of a dedicated AI developer.

That is why how to evaluate AI agents should start with your business workflow, not with a technology shortlist.

Before selecting an agent, define what you want it to accomplish. Create test cases based on real user requests and edge cases. Then establish measurable success criteria for accuracy, task completion, safety, reliability, cost, and other factors that matter to your operation.

Once you know what good performance looks like, you can compare technologies against something meaningful.

And when the right agent is selected, evaluation should not stop at deployment. Your team should continue testing, monitoring, and improving the system as its tools, data, models, and workflows evolve.

The right evaluation process does more than tell you which AI agent performs better. It tells you whether the agent is ready to create real business value.
Turn Your Use Case Into an AI Solution

AI Integration vs AI Development: How to Choose the Right Approach

Introduction

Your software already works. Your customers already use it. Your teams already depend on it. Now you want to add AI.

That is where the real question begins.

Should you integrate an existing AI model into your software? Should you build a custom AI solution around your data and workflows? Or would a hybrid approach give you the control you need without starting everything from scratch?

The wrong choice can mean unnecessary development costs, longer implementation timelines, limited flexibility, or a solution that does not fit your business processes.

The AI integration vs AI development decision should start with what your software already does and what you want AI to accomplish. If an existing AI service can handle the requirement, integration may be enough. If your needs depend on proprietary data, specialized workflows, or greater control, custom development may make more sense.

This guide explains how to evaluate both approaches, when to integrate AI into existing software, when to build a custom solution, and where a hybrid approach fits. You will also see practical use cases, cost and timeline considerations, current AI approaches, and the steps involved in adding AI to an existing system.

AI Integration vs AI Development: What Is the Difference?

The first decision is understanding what you are actually building. AI integration connects an existing AI capability to software you already use. AI development involves creating a more tailored AI solution around your specific business requirements.

The difference matters because the two approaches require different levels of development, data, control, and investment.


What Is AI Integration?

AI integration means adding an existing AI model, API, platform, or service to your current software. Your application remains the main system while the AI capability handles a specific task.

For example, you could add an AI assistant to your CRM to summarize customer interactions. An ecommerce business could integrate AI search to help customers find products using natural language. An enterprise application could use an AI service to extract information from uploaded documents.

This approach is often suitable when you want to add AI to an existing system without rebuilding its core functionality.

What Is AI Development?

AI development involves creating a tailored AI capability around your business requirements. The work can include model selection and adaptation, data preparation, RAG implementation, AI agent development, custom machine learning, evaluation, and application logic.

Custom AI development does not necessarily mean training a large language model from zero. In many projects, the better approach is to use an existing foundation model and build the custom layers around it.

For example, you may use an established LLM but connect it to proprietary company data through RAG. You could also build custom agents that interact with your internal systems and follow business-specific rules.

AI Integration vs AI Development at a Glance


FactorAI IntegrationAI Development
Starting pointExisting software and AI servicesCustom AI capability
Initial costUsually lowerUsually higher
Implementation timeGenerally shorterUsually longer
CustomizationDepends on the selected AI serviceGreater customization
Data requirementsOften limitedCan require substantial business data
ControlDepends on the AI providerGreater control over the solution
ScalabilityDepends on the provider and architectureDesigned around your requirements
MaintenanceShared between your team and providerPrimarily managed by your development team
Best suited forAdding established AI capabilitiesSpecialized or product-specific AI requirements


The choice is therefore less about whether AI should be used and more about how much of the AI capability your business needs to own and customize. The next step is understanding what it takes to connect AI with the software you already have.

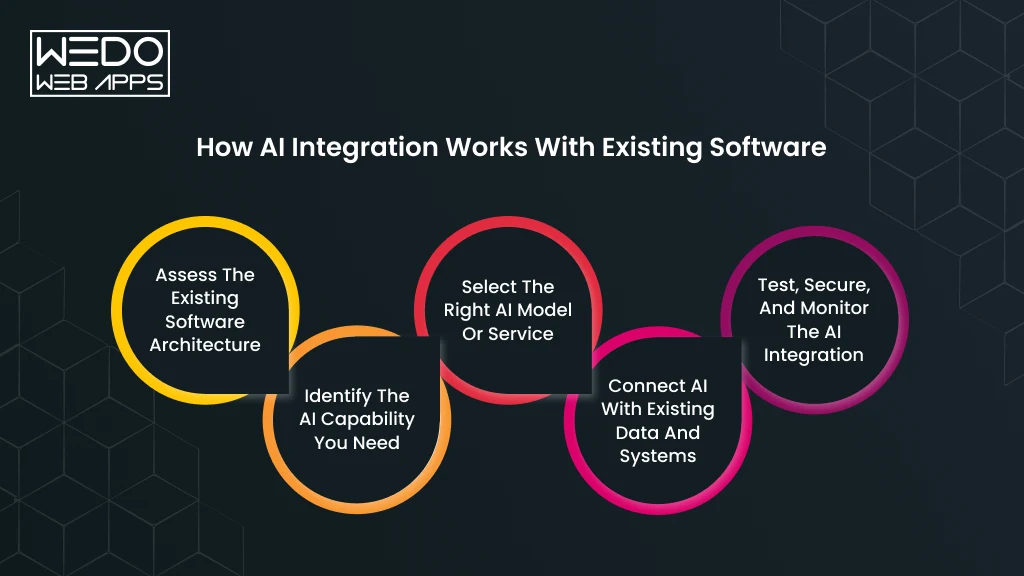
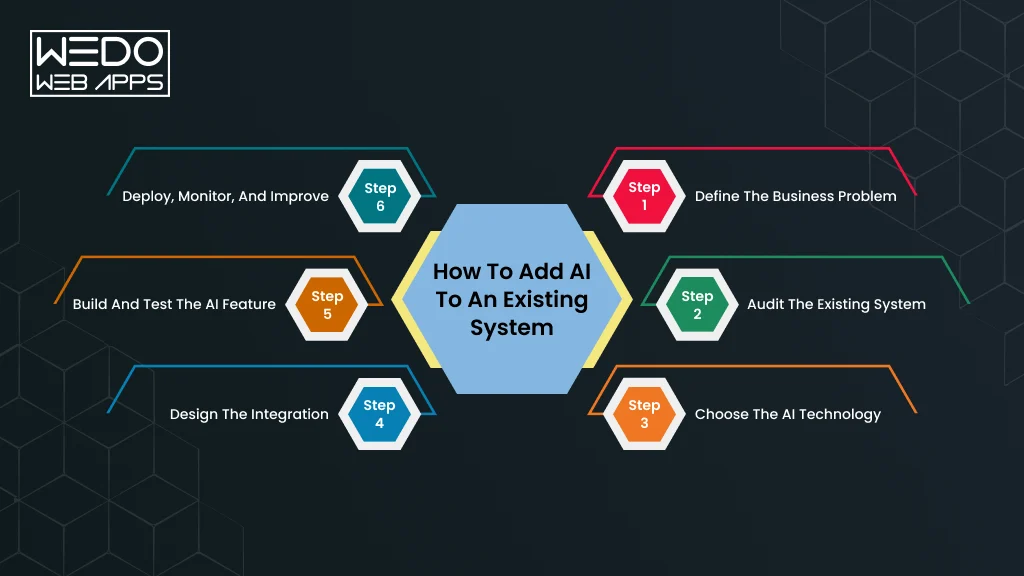
How AI Integration Works With Existing Software

How AI Integration Works With Software


Adding AI to an existing application requires more than connecting an API and placing an AI feature on the interface. The AI needs to work with your application’s data, permissions, workflows, and user experience.

A well-planned integration keeps the existing software intact while introducing the AI capability where it can provide measurable value.

Assess the Existing Software Architecture

Start by reviewing how your current application is built and how its systems communicate.

Look at the APIs, databases, backend services, authentication, third-party integrations, and business workflows. This assessment helps identify where the AI capability can connect without disrupting existing functions.

For example, if you want to add AI customer support to a CRM, the integration may need controlled access to customer records, support tickets, product information, and conversation history.

Identify the AI Capability You Need

Define the task before selecting an AI model. The right technology depends on what you expect the system to accomplish.

You may want to add:

  • An AI chatbot for customer support.
  • Natural language search for an eCommerce catalog.
  • Document processing for extracting structured information.
  • Recommendations based on user behavior.
  • Predictive analytics for business forecasting.
  • Content generation for product or marketing workflows.
  • Voice capabilities for hands-free interactions.

A specific use case also makes it easier to establish performance criteria before development begins.

Select the Right AI Model or Service

Once the use case is clear, evaluate the AI technology that can support it. Your options may include LLM development APIs, specialized AI services, open-source models, or a combination of technologies.

Consider factors such as accuracy, response time, API limits, data handling, integration requirements, and usage costs.

For instance, a custom support assistant may work well with an existing LLM API. A specialized medical imaging application may require a more tailored machine learning approach.

Connect AI With Existing Data and Systems

The AI capability then needs a controlled connection to the systems it will use.

Depending on the application, this can involve APIs, middleware, databases, vector databases, data pipelines, or application logic.

Consider an internal knowledge assistant. The model can generate the response, while a RAG layer retrieves relevant information from approved company documents. This lets the AI work with your business knowledge without requiring the entire application to be rebuilt.

Test, Secure, and Monitor the AI Integration

Before putting the feature into production, test how it behaves with real workflows and realistic inputs.

Check response accuracy, access permissions, data handling, failure cases, latency, and system performance. Sensitive information should only be exposed to the AI service when the architecture and data handling policies allow it.

You should also monitor the integration after launch. AI output can vary, usage can increase unexpectedly, and model providers can change their services. Monitoring gives your team the information needed to identify problems and improve the system over time.

When these steps are handled together, AI integration for existing software becomes an extension of the product rather than an isolated AI feature.

Discuss Your Existing AI Integration

AI Integration vs Building From Scratch: Which Approach Is Right for You?

You do not have to treat AI integration and custom AI development as two completely separate paths. The right approach depends on how much of the AI capability you need to customize and control.

AI Integration: Use What Already Works

Best when: Your requirement can be handled by an established AI model or service.

What you do: Connect an existing AI capability with your software, data, workflows, and user interface.

Good fit for:

  • Text summarization
  • AI search
  • Speech-to-text
  • Content generation
  • Basic image analysis

Example: You already have a customer support platform and want to add an AI assistant that summarizes tickets and suggests responses. An existing LLM API may provide the required capability. Your development effort can focus on connecting it securely to the relevant support data and workflows.

Custom AI Development: Build Around Your Requirements

Best when: Your AI requirements are specialized or existing solutions cannot deliver the required results.

What you do: Develop a tailored AI capability using your data, workflows, models, business rules, and evaluation criteria.

Good fit for:

  • Specialized prediction systems
  • Proprietary AI capabilities
  • Domain-specific applications
  • Strict accuracy requirements
  • AI-driven products

Example: A logistics company wants to predict delivery delays using its historical shipment data, routes, weather conditions, and operational patterns. A generic AI API may not provide the required prediction capability. A custom model can be designed around these specific inputs.

Hybrid AI Development: Combine Existing AI With Custom Components

Best when: An existing model can handle the core AI task, but your business needs custom data, workflows, or control.

What you do: Use an existing foundation model while developing the components that make the solution specific to your business.

Good fit for:

  • RAG applications
  • AI agents
  • Enterprise knowledge assistants
  • AI-powered business workflows
  • Applications using proprietary data

Example: You can use an existing LLM to generate responses while building a custom RAG system that retrieves information from your company’s approved documents. The model provides the language capability. Your application controls which business information reaches it.

Which Approach Should You Consider?


If your situation looks like thisConsider
You need a standard AI capabilityAI Integration
Your existing software already solves the core problemAI Integration
You need to validate an AI feature before investing heavilyAI Integration
Your requirements are highly specializedCustom AI Development
AI is the main value proposition for your productCustom AI Development
You need extensive control over proprietary dataCustom AI Development
An existing model works, but you need custom business knowledge or workflowsHybrid AI Development


The important question is not simply whether you should integrate or build. Ask how much of the AI solution needs to be customized around your business. That answer will usually point you toward the right approach.

When Should You Integrate AI Into Existing Software?

If your existing software already handles your core business operations, rebuilding it just to introduce AI may add unnecessary cost and development work. In many cases, you can add AI to an existing system and keep the workflows your teams and customers already know.

AI integration makes sense when the technology you need is already available, and your application has a suitable place for it.

Your Existing Software Already Solves the Core Business Problem

If your current application already manages the main business process, AI can be introduced as an additional capability.

For example, an ecommerce platform can continue handling products, orders, payments, and inventory while an AI layer adds natural language search and product recommendations.

You keep the system that works and add intelligence where it can improve the experience.

A Proven AI Model Already Meets Your Requirements

You may not need custom AI development if established models can already deliver the required result.

An existing LLM can handle tasks such as summarization, classification, content generation, and conversational interactions. Speech recognition and image analysis services can also be integrated when they meet your accuracy and data requirements.

The key is to evaluate the model against your actual use case before committing to custom development.

You Need a Faster Implementation Timeline

If you want to introduce an AI feature within an existing product without spending months developing a specialized model, integration can provide a more direct path.

For instance, a SaaS platform could integrate an AI assistant into its existing dashboard rather than developing an entire AI system independently.

The timeline will still depend on your architecture, security requirements, data access, testing, and the complexity of the workflow.

Your Team Wants to Test AI Before Making a Larger Investment

AI integration can also serve as a practical starting point.

You can introduce one focused capability, measure how users interact with it, evaluate its accuracy, and assess whether it delivers measurable business value.

For example, you could add AI-generated ticket summaries to a support platform first. If the feature reduces the time agents spend reviewing conversations, you have evidence to support a broader AI investment.

A practical rule: If your existing software works well and an established AI capability can meet the new requirement, integration is usually the more practical starting point.

When Should You Build AI Instead of Integrating It?

Integrating an existing AI service is practical when your requirements are already covered. The situation changes when the AI capability itself needs to be tailored around your product, data, or operating model.

Before choosing custom AI development, look for these signals.

AI Is Part of What Your Customers Are Buying

If AI is only supporting your product, an existing model may be enough. If AI is the product, greater ownership can become more important.

Imagine a platform that uses AI to assess financial risk. Its value may depend on proprietary scoring logic, historical data, prediction accuracy, and domain-specific workflows. A basic third-party integration may provide the interface, but not the differentiation.

Build signal: Your AI capability directly influences your product’s value or competitive advantage.

Your Data Gives You an Advantage

Generic AI tools are trained for broad use cases. Your business may have information that is specific to your industry, customers, equipment, processes, or operations.

A manufacturer, for example, could have thousands of historical production images showing different types of equipment defects. A custom AI solution can be designed to use this data for a specialized inspection workflow.

Build signal: Your proprietary data is central to the AI capability you want to create.

Generic Models Fall Short in Testing

Do not assume that a popular AI model will automatically deliver the required results for your use case.

Test available models against your actual data and define measurable criteria for accuracy, response quality, latency, or consistency.

If the results remain below your required threshold, custom development may give you more options for improving the model or the surrounding AI architecture.

Build signal: Existing AI tools repeatedly fail your real-world performance tests.

Your AI Requires Tighter Control

Some applications cannot treat AI as a simple external service.

You may need control over where data is processed, which information the model can access, how outputs are evaluated, and how the system behaves when it encounters uncertain results.

This matters particularly for applications with strict security, privacy, audit, or data residency requirements.

Build signal: Your business needs control that the chosen third-party AI service cannot provide.

AI Will Expand Across Your Product

Think beyond the first AI feature.

If you expect to introduce AI search today, AI agents tomorrow, predictive capabilities later, and several AI-driven workflows after that, your initial architecture needs to support that direction.

You may still use existing foundation models. The custom part can sit around them through your own data layer, orchestration, evaluation framework, retrieval system, or business logic.

Build signal: AI is becoming a long-term product capability rather than a single feature.

A Simple Test Before You Choose

Ask yourself these five questions:


QuestionIf the answer is “Yes”
Is AI central to your product value?Consider custom development
Does proprietary data drive the AI capability?Consider custom development
Do existing models fail your performance tests?Consider custom development
Do you need greater control over data or behavior?Consider custom development
Will you build multiple AI capabilities over time?Consider a custom or hybrid architecture


You do not need to build every AI component yourself. In many cases, the smarter option is to use an established foundation model while developing the parts that require your data, workflows, and control.

The takeaway: Build when your AI requirements are specific enough that a standard integration would limit performance, differentiation, control, or future growth.

Get an AI Development Consultation

AI Integration vs Custom AI Development: Cost, Time, and Resources

Budget is often the first concern when you compare AI integration with custom development. The initial development cost matters, but it does not tell you the full financial picture.

You also need to consider implementation time, infrastructure, AI usage, maintenance, testing, and the resources required after launch.

How Much Does AI Integration Cost?

The cost of integrating AI into existing software depends largely on the complexity of the feature and the systems it needs to connect with.

A straightforward integration with an established AI API may require less development work. A solution that needs access to multiple databases, custom retrieval, extensive security controls, or complex workflows will require more effort.

Your integration budget may include:

  • AI API or platform usage
  • Backend and frontend development
  • API and system integration
  • Cloud infrastructure
  • Testing and quality evaluation
  • Security controls
  • Monitoring and maintenance

Example: Adding AI-generated summaries to an existing CRM may require a relatively focused integration. Connecting an AI agent to the CRM, billing system, support platform, and internal knowledge base would require a more involved architecture.

How Much Does Custom AI Development Cost?

Custom AI development generally requires a broader set of resources because more of the solution is designed around your requirements.

The cost can include:

  • Data collection and preparation
  • Data labeling where required
  • AI engineering
  • Model development or adaptation
  • RAG or agent architecture
  • Infrastructure and hosting
  • Testing and evaluation
  • Deployment
  • Monitoring and ongoing maintenance

The complexity of your use case has a major influence on the final cost. A custom recommendation engine and a specialized computer vision system can have very different development requirements.

How Long Does AI Integration Take?

Integration can often move faster when the required AI capability already exists, and your software has suitable integration points.

However, there is no reliable single timeline for every project. The duration depends on factors such as the number of systems involved, API complexity, data access, security requirements, testing, and the amount of customization required.

A simple AI feature may involve a focused development cycle. An enterprise integration connecting several systems will require more planning and validation.

How Long Does Custom AI Development Take?

Custom AI development usually involves more stages before the solution is ready for production.

The process may include requirements analysis, data preparation, architecture design, model selection, development, training or adaptation, evaluation, integration, deployment, and monitoring.

There can also be an experimentation phase. Your team may test different models or approaches before finding one that meets the required performance.

AI Integration vs Custom AI Development: Cost and Time Comparison


FactorAI IntegrationCustom AI Development
Initial investmentGenerally lowerGenerally higher
ImplementationUsually fasterUsually lower
CustomizationDepends on available AI toolsHigh
Data requirementsOften lowerOften higher
AI controlDepends on providerGreater
InfrastructureOften provide supportedMore responsibility for your team
MaintenanceDepends on integration and providerPrimarily managed around your solution
Best suited forExisting software and established AI use casesSpecialized AI capabilities


The lowest initial cost is not always the best choice. If an integrated service cannot meet your requirements, replacing it later can introduce additional development and migration work.

Likewise, building a custom solution for a problem that an established AI service already solves can add unnecessary expense.

The better approach is to compare the total cost against the level of customization and control your business actually needs.

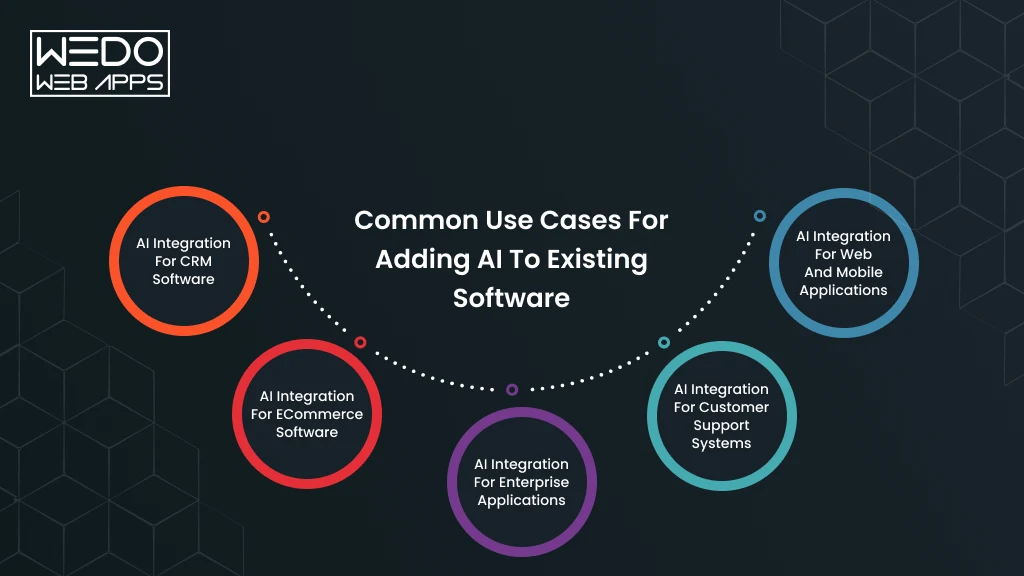
Common Use Cases for Adding AI to Existing Software

Common Use Cases for AI Software

You do not need to replace an existing application to introduce useful AI capabilities. In many cases, AI can be added to the workflows your customers and employees already use.

The right integration depends on the software, the data available, and the task you want AI to handle.

AI Integration for CRM Software

CRM platforms already contain valuable customer and sales information. AI can help teams use that information more efficiently.

Common applications include:

  • Lead scoring based on customer and engagement data
  • Automatic summaries of sales calls and customer interactions
  • Suggested follow-up messages for sales teams
  • Customer sentiment analysis
  • Automated data classification

Example: A sales representative finishes a customer call. An integrated AI feature can summarize the conversation, identify follow-up tasks, and save the relevant information to the CRM.

AI Integration for eCommerce Software

AI can make product discovery and customer interactions more responsive without changing the core ecommerce system.

Useful applications include:

  • Natural language product search
  • Personalized recommendations
  • AI-generated product descriptions
  • Customer support assistants
  • Product comparison and discovery

Example: Instead of searching for “running shoes,” a customer could ask for “lightweight shoes for long-distance running under ₹5,000.” An AI search layer can interpret the request and retrieve relevant products from the existing catalog.

AI Integration for Enterprise Applications

Enterprise software often contains large volumes of documents and operational information. AI can help employees find and process that information faster.

Common use cases include:

  • Document classification and information extraction
  • Internal knowledge search
  • Report generation
  • Document summarization
  • Workflow assistance

Example: An employee could upload a lengthy business document and receive a structured summary with key information extracted into the existing enterprise workflow.

AI Integration for Customer Support Systems

Support teams can use AI to handle repetitive work while keeping human agents involved when judgment is required.

AI can assist with:

  • Ticket classification
  • Response suggestions
  • Customer query summarization
  • Sentiment analysis
  • Frequently asked question handling

Example: When a new support ticket arrives, AI can identify its category and urgency, retrieve relevant knowledge, and suggest a response for the support agent to review.

AI Integration for Web and Mobile Applications

AI can also become part of the user experience in websites and mobile applications.

Depending on the product, you could add:

  • AI assistants
  • Voice-based interactions
  • Image analysis
  • Personalized recommendations
  • Intelligent search
  • AI-generated content

Example: A fitness application could use an AI assistant to interpret a user’s goals and provide personalized workout suggestions based on information already stored in the application.

The common thread across these examples is simple. AI does not have to replace your existing software to add value. It can sit within the workflows your users already understand and handle specific tasks that benefit from AI capabilities.

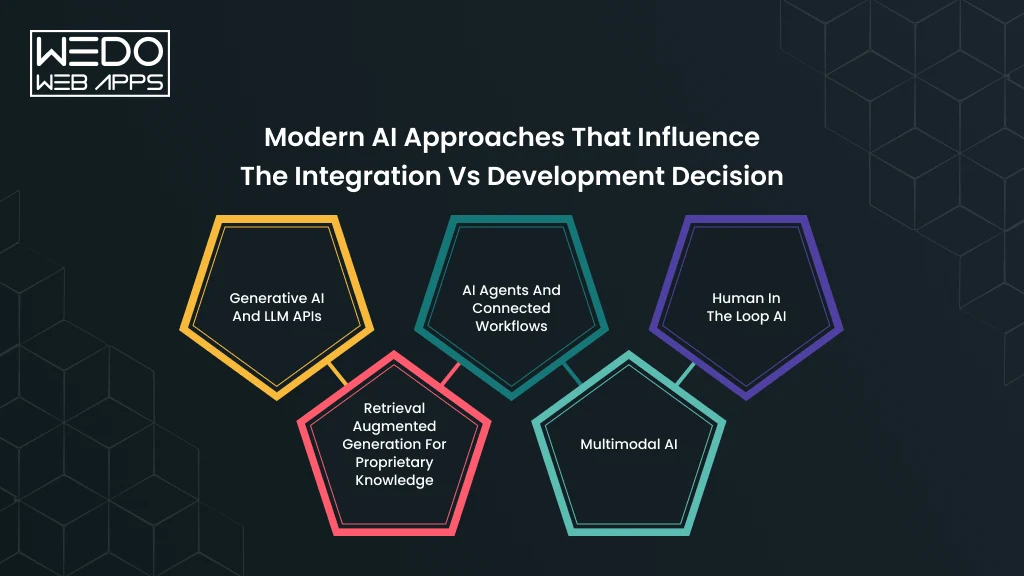
Modern AI Approaches That Influence the Integration vs Development Decision

AI Approaches for Integration Choice

The build versus integrate decision has become more nuanced as AI capabilities have expanded. You can now combine foundation models, retrieval systems, AI agents, and application-specific logic in different ways.

That means the question is often not which AI technology is newest. It is which combination fits your product, data, and level of control.

Generative AI and LLM APIs

Generative AI has made it possible to add capabilities such as text generation, summarization, conversational assistance, and content analysis without developing a language model from the ground up.

For many applications, an existing LLM API is enough. You can connect the model to your application and build the required business logic around it.

Integration makes sense when: The model already performs the task reliably, and your main requirement is connecting it to your software.

Custom development makes sense when: You need specialized behavior, proprietary processing, or greater control around the model.

Retrieval Augmented Generation for Proprietary Knowledge

RAG changes the equation when your application needs to work with internal or domain-specific information.

Instead of expecting the model to know your company’s latest documents, policies, product information, or knowledge base, a RAG system retrieves relevant information and provides it to the model when generating a response.

For example, an insurance company could build an internal assistant that retrieves information from approved policy documents before generating an answer.

Integration makes sense when: An existing LLM can handle the generation while your main requirement is connecting it with a reliable knowledge source.

Custom development makes sense when: You need a specialized retrieval pipeline, complex permissions, proprietary ranking logic, or extensive control over how information reaches the model.

AI Agents and Connected Workflows

AI agents can take the integration requirement further. Instead of only generating a response, an agent can interact with tools, APIs, databases, and business workflows.

For example, an AI sales assistant could retrieve customer information from a CRM, check an order status, prepare a response, and create a follow-up task.

This can often be built using an existing foundation model. The custom work may sit in the orchestration layer, tool permissions, business rules, and application architecture.

Integration makes sense when: Existing models and agent frameworks can support the workflow you need.

Custom development makes sense when: The agent requires specialized orchestration, strict permissions, complex workflows, or deeper integration with proprietary systems.

Security also becomes more important as AI gains the ability to take actions. OWASP’s 2025 guidance identifies prompt injection, sensitive information disclosure, excessive agency, and improper output handling among the risks developers need to address in LLM applications.

Multimodal AI

Modern AI systems can work with more than text. Depending on the model, applications can process combinations of text, images, audio, and video.

This creates new integration opportunities.

A retail application could analyze product images. A customer service platform could process voice conversations and text together. A manufacturing application could use image inputs for quality inspection.

Integration makes sense when: An established multimodal model meets your application’s requirements.

Custom development makes sense when: The application needs specialized processing, domain-specific accuracy, or custom handling of multimodal data.

Human in the Loop AI

Not every AI workflow should operate without human oversight.

For high-impact tasks, your application may need a person to review an AI-generated recommendation, approve an action, or handle cases where the model is uncertain.

This approach can work with both integrated and custom AI systems. The difference is where the human review process sits within the architecture.

For example, an AI system could classify insurance claims automatically but require an employee to approve claims that meet specific risk conditions.

NIST’s Generative AI Profile recommends incorporating trustworthiness considerations into the design, development, use, and evaluation of generative AI systems.

What These Approaches Mean for Your Build Decision

The latest AI capabilities do not automatically mean you need custom AI development.

A more practical approach is to separate the AI stack into components:


AI RequirementPossible Approach
General language generationExisting LLM API
Company-specific knowledgeLLM + RAG
Automated actionsLLM + AI agent architecture
Image and text processingMultimodal AI service
Specialized predictionCustom AI model
High-risk decisionsAI + human review


This is why AI integration vs AI development is no longer always a simple either/or decision. You can use established AI models for capabilities that already work well and develop custom components where your business needs greater control.

The strongest architecture is the one that gives you the required performance, security, flexibility, and business value without building more than your use case demands.

Build AI Solutions for Your Business

How to Add AI to an Existing System?

AI Integration With Existing Systems

Adding AI to existing software does not have to mean rebuilding the application. A better starting point is to identify where AI can improve an existing workflow and then design the integration around that requirement.

A practical AI software integration guide should therefore begin with the business problem, not the AI model.

Step 1: Define the Business Problem

Start by identifying the task you want AI to improve.

Look at where users spend time, where employees perform repetitive work, or where your existing software cannot provide enough assistance.

For example, a support platform may have thousands of tickets but require agents to read each conversation manually. The AI requirement could be defined as summarizing tickets and suggesting responses.

A clear problem gives you a measurable outcome to work toward.

Step 2: Audit the Existing System

Next, review how your software currently works.

Check the application architecture, APIs, databases, authentication, workflows, third-party services, and data access controls. This helps you identify where AI can connect and whether changes to the existing architecture are needed.

You should also determine which data the AI feature needs and whether users have the right permissions to access it.

Step 3: Choose the AI Technology

Now evaluate the technology that matches the use case.

You might need an LLM API for text generation, a specialized model for image analysis, RAG for company-specific knowledge, or an AI agent for workflows involving multiple tools.

Start with the simplest approach that can meet your requirements. Microsoft also recommends using prebuilt and pretrained models when they satisfy the workload’s security, safety, compliance, and quota requirements.

Step 4: Design the Integration

The AI capability needs a controlled connection with your application.

This can involve APIs, middleware, an orchestration layer, databases, vector stores, or business APIs. For RAG applications, an orchestration layer can retrieve authorized information from a data source before passing relevant context to the model.

For example, an internal knowledge assistant could authenticate the employee, retrieve documents they are permitted to access, and then provide that information to the LLM to generate an answer.

Step 5: Build and Test the AI Feature

Once the architecture is defined, integrate the AI capability into the relevant workflow.

Testing should cover more than whether the model produces an answer. Evaluate accuracy, response quality, latency, failure handling, security, permissions, and usability.

AI output should also be treated carefully. Current Microsoft guidance recommends validating inputs, securing data flows, configuring tool access, and validating AI-generated outputs, particularly when agents can interact with external systems.

Step 6: Deploy, Monitor, and Improve

An AI feature needs attention after launch.

Track usage, response quality, latency, errors, infrastructure consumption, and user feedback. Monitor whether the AI continues to meet the business requirements as your data, users, and workflows change.

For production AI systems, monitoring and continuous operational practices are part of the architecture rather than an afterthought. AWS recommends combining monitoring, safety controls, automation, and continuous delivery when operationalizing generative AI applications.

This approach helps you avoid adding AI simply because the technology is available. You can introduce the capability where it has a clear purpose, measurable outcome, and suitable place within your existing software.

AI Integration vs AI Development: Decision Matrix

If you are still weighing AI integration vs AI development, the following matrix can give you a quick direction. Match your AI adoption framework with the approach that best fits it.


Your Business RequirementRecommended ApproachWhy
AI Chatbot in existing softwareAI IntegrationAn established LLM can handle conversational tasks while your software manages users and workflows
AI summarizationAI IntegrationExisting language models can summarize text without requiring a custom model
AI searchAI integrationSearch capabilities can be added to existing product or knowledge databases
LLM connected to existing workflowsIntegration or HybridAn existing model can handle language tasks while custom logic connects it with business systems
Company-specific knowledge with an LLMHybridRAG can connect an existing model with your proprietary information
Specialized prediction systemCustom AI developmentThe solution may need custom data processing, model development, and domain-specific evaluation
AI as the core product capabilityCustom AI developmentGreater control can help you build capabilities that differentiate the product
Accuracy beyond existing AI toolsCustom AI developmentCustom models or supporting architecture may be needed to meet specific performance targets
AI agents connected to business systemsHybridExisting foundation models can power reasoning while custom orchestration manages tools and workflows
Extensive control over AI behaviorCustom or HybridYour architecture can provide greater control over data, processing, evaluation, and model behavior


What Should You Choose?

Think about the decision in three levels.

Choose integration when an existing AI capability already solves your problem, and your main requirement is connecting it to your software.

Choose custom development when your AI needs to be specialized, highly controlled, or central to your product.

Choose a hybrid approach when an existing model can handle the intelligence, but your business needs custom data, RAG, agents, workflows, or application logic around it.

The answer can also change over time. You might start by integrating an existing model to validate an idea and later develop custom components as usage and requirements grow.

The goal is not to build the most complex AI architecture. It is to choose an approach that gives you the right balance of capability, control, cost, and scalability for your actual use case.

How WEDOWEBAPPS Helps Businesses Integrate and Build AI Solutions

Choosing between AI integration and custom development becomes easier when you first understand what your existing software can support. At WEDOWEBAPPS, we approach the requirement from your product and business workflow rather than starting with a specific AI technology.

Whether you want to add AI to an existing system or develop a new AI capability, our team can help you assess the right technical path.

Existing Software and Architecture Assessment

Before recommending an approach, we review your current application architecture, APIs, databases, workflows, integrations, and data access.

This helps identify where AI can fit into your existing system and whether architectural changes are required.

For example, if you want to introduce an AI assistant into an existing CRM, we can assess which customer data the assistant needs and how it should interact with your current workflows.

AI Integration Strategy

If an existing AI model can meet your requirements, integration may be the more practical option.

We can connect AI services with your web application, mobile app, CRM, ecommerce platform, enterprise software, or internal systems. The integration can include API connections, data retrieval, authentication, business logic, and user-facing AI features.

The objective is to make the AI capability work within your existing application rather than operate as a disconnected tool.

Custom AI Development

Some requirements need more than an API connection.

When your application depends on proprietary data, specialized predictions, domain-specific performance, or AI as a core product capability, we can design a custom AI solution around those requirements.

Depending on the use case, this can involve machine learning models, RAG systems, AI agents, custom data pipelines, model adaptation, or specialized AI workflows.

RAG, AI Agents, and Generative AI Solutions

Modern AI applications often combine existing foundation models with custom application components.

For example, RAG can connect an LLM with your internal knowledge base. AI agents can connect models with business tools and workflows. Generative AI can support content, conversations, document processing, and other application features.

We can help determine which approach fits your software, data, security requirements, and intended outcome.

AI Testing, Deployment, and Ongoing Optimization

Building the AI feature is only one part of the project.

Before deployment, the solution should be evaluated for accuracy, performance, security, usability, and reliability. After launch, monitoring can help identify unexpected outputs, changing usage patterns, rising costs, or areas where the AI needs improvement.

Our team can support the solution through testing, deployment, monitoring, maintenance, and further development as your requirements evolve.

Need to Add AI to Your Existing Software?

If you already have a working application and are considering AI, you do not necessarily need to rebuild it.

Talk to WEDOWEBAPPS about your existing software, AI use case, and technical requirements. We can help you assess whether integration, custom development, or a hybrid approach is the better fit.

Conclusion: Choosing Between AI Integration and AI Development

The decision between AI integration and AI development starts with your actual business requirement.

If your existing software already solves the core problem and an established AI capability can handle the additional task, AI integration can be the practical choice. You can add capabilities such as AI search, summarization, recommendations, chatbots, or content generation without rebuilding the entire application.

Custom AI development becomes more suitable when your requirements are specialized. Proprietary data, strict accuracy targets, greater control, or AI as a core product capability can justify a more tailored solution.

There is also a third option. Hybrid AI development lets you combine existing foundation models with custom RAG systems, data pipelines, AI agents, workflows, and business logic.

So, when deciding when to integrate vs build AI, look beyond the initial development cost. Consider your software architecture, data, security requirements, timeline, level of customization, and long-term product plans.

If you are planning to add AI to an existing system, the right starting point is to assess what you already have and identify where AI can provide measurable value. From there, you can choose the approach that fits your requirements without building more than your business actually needs.

13 AI Implementation Mistakes That Cause Project Failure

Introduction

AI can accelerate growth, improve efficiency, and can also allow you to create new opportunities, but only when implemented with a clear purpose. Still, there are many organizations that invest heavily in artificial intelligence and still struggle to achieve meaningful results.

The reason is often not the technology itself. Most setbacks stem from preventable AI implementation mistakes that occur before and during execution. Unclear objectives, poor planning, unrealistic expectations, and weak adoption strategies can quickly turn a promising initiative into an expensive lesson.

Many cases of AI project failure can be traced back to overlooked AI planning mistakes rather than technical limitations during software development. Organizations that rush into AI without a well-defined AI strategy often find it difficult to scale initiatives, measure ROI, or gain stakeholder buy-in.

In this guide, we will examine the most common AI implementation mistakes businesses make and the practical steps to avoid them.

Why AI Projects Fail More Often Than Expected

Organizations are investing in AI at an unprecedented rate, yet many initiatives fail to deliver the expected business impact. The challenge is rarely the technology itself. More often, the problem lies in how AI is planned, implemented, and managed.

Many businesses approach AI with ambitious goals but without the foundation needed to achieve them. This disconnect often creates a gap between expectations and actual outcomes.

Quick Answer: Why Do AI Projects Fail?

Most cases of AI project failure occur because organizations lack clear business objectives, reliable data, stakeholder alignment, and a well-defined AI strategy. Combined with poor execution and common AI planning mistakes, these issues prevent AI initiatives from generating measurable business value.

The Gap Between AI Ambitions and Business Outcomes

Many companies adopt AI because they want to improve efficiency, reduce costs, or gain a competitive advantage. However, success becomes difficult when AI initiatives are driven by trends rather than business needs.


AI GoalBusiness Challenge
Implement AI toolsNo clear problem to solve
Automate processesUndefined success metrics
Deploy AI quicklyLimited organizational readiness


When business outcomes are unclear, measuring success becomes equally difficult.

Common Patterns Behind AI Project Failure

Several AI implementation mistakes appear repeatedly across successful projects:

  • Starting without defined objectives.
  • Using poor quality or fragmented data.
  • Expecting immediate ROI.
  • Ignoring employee adoption and training.
  • Scaling before validating results.

The Role of Strategy, Planning, and Execution

Successful AI initiatives are built on more than technology. They require a strong AI strategy, careful planning, and disciplined execution.

The most successful organizations typically:

  • Align AI initiatives with business goals.
  • Assess data readiness early.
  • Establish measurable KPIs.
  • Create a roadmap before development begins.

Without these fundamentals, even promising AI projects can struggle to deliver meaningful results.

The 13 Most Common AI Implementation Mistakes

Many organizations assume that selecting the right AI tool is the most important factor in project success. In reality, most AI implementation mistakes occur before weak adoption strategies; these mistakes can significantly increase the risk of AI project failure.

Let’s start with one of the most common and costly mistakes businesses make:

Mistake 1: Launching AI Without Clear Business Objectives

One of the fastest ways to derail an AI initiative is to start with the technology instead of the business problem. Organizations often decide to “implement AI” without clearly defining the challenges needed to be solved.

When objectives are vague, teams struggle to prioritize use cases, allocate resources, and demonstrate ROI. As a result, projects may generate interesting outputs but fail to create meaningful business value.
What This Looks Like in Practice


ApproachLikely Outcome
“We need an AI solution”Unclear direction and success criteria
“Let’s add AI to our processes.”Difficulty proving value
“We want to reduce customer support resolution time by 30%.”Measurable business outcome
“Let’s automate invoice processing to reduce manual effort”Clear implementation roadmap


The difference is simple: successful AI initiatives start with a business objective, not a technology objective.

Why This Mistake Happens

Some of the most common reasons include:

  • Pressure to keep up with competitors.
  • Executive enthusiasm without a defined use case.
  • Lack of alignment between business and technical teams.
  • Absence of measurable success metrics.
  • Focusing on AI capabilities rather than business outcomes.

These are often early AI planning mistakes that create challenges throughout the implementation lifecycle.

How to Avoid It

Before investing in any AI solution, answer these questions:

  • What specific business problem are we solving?
  • What KPI will define success?
  • How will this initiative impact revenue, cost, productivity, or customer experience?
  • What is the expected timeline for measurable results?

A strong AI strategy connects every AI initiative to a business goal. When objectives are clear from the start, organizations can prioritize the right use cases, measure outcomes effectively, and significantly reduce the likelihood of project failure.

Mistake 2: Treating AI as a Technology Project Instead of a Business Initiative

Many organizations view AI as an IT or engineering project. As a result, decisions are often driven by technical capabilities rather than business priorities. While technology is an important component, AI initiatives deliver value only when they support a specific business objective.

This mindset is one of the most common AI implementation mistakes because it creates a disconnect between development efforts and organizational goals. Teams may successfully deploy an AI solution, yet struggle to demonstrate its impact on efficiency, revenue, customer experience, or operational performance.

Technology First vs Business First


Technology First ApproachBusiness First Approach
Focuses on AI features and modelsFocuses on business outcomes
Success measured by deploymentSuccess measured by business impact
Limited stakeholder involvementCross-functional collaboration
Difficult to justify ROIClear value proposition and KPIs


When AI is treated solely as a technology initiative, adoption often becomes an afterthought. Employees may not understand how to use the solution, leadership may question its value, and projects can lose momentum despite being technically successful.

Warning Signs of This Mistake

  • Business teams are rarely involved in planning discussions.
  • Success is defined by launching the solution rather than achieving results.
  • AI use cases are selected based on trends rather than business needs.
  • Teams cannot clearly explain the expected business impact.

These issues frequently contribute to AI project failure, especially when organizations attempt to scale AI across multiple departments.

How to Avoid It

A successful AI strategy starts by identifying business goals before evaluating tools or technologies.

Consider the following questions:

  • Which business challenge are we trying to solve?
  • Who will benefit from the solution?
  • How will success be measured?
  • What operational or financial impact do we expect?

Organizations that align AI initiatives with business objectives are far more likely to achieve measurable outcomes and avoid costly AI planning mistakes later in the project lifecycle.

Mistake 3: Choosing AI Use Cases With Low Business Impact

Not every business problem requires AI, and not every AI use case delivers meaningful value. One of the most overlooked AI implementation mistakes is investing time and resources into projects that generate limited business impact.

In many cases, organizations select use cases based on what’s technically possible rather than what’s strategically valuable. While these projects may demonstrate AI capabilities, they often struggle to justify investment or gain long-term support from stakeholders.

High Impact vs Low Impact AI Use Cases


Low Impact Use CasesHigh Impact Use Cases
Minor workflow enhancementsRevenue growth opportunities
Features with limited adoptionCustomer expectation improvements
Nice-to-have automationCost reduction initiatives
Experimental projects without KPIsSolutions tied to measurable business outcomes


A use case may be technically impressive, but if it doesn’t solve a meaningful business challenge, its value will be difficult to prove.

Signs You’re Pursuing the Wrong Use Case

  • The business impact cannot be clearly quantified.
  • Success metrics are undefined.
  • Stakeholders struggle to explain the expected ROI.
  • The problem could be solved without AI.
  • Adoption is expected to be low from the start.

These warning signs often lead to AI project failure because teams invest resources without creating measurable outcomes.

How to Avoid It

Before approving an AI initiative, evaluate each use case against three key criteria:

  • Business Value: Will it increase revenue, reduce costs, improve efficiency, or strengthen customer experience?
  • Feasibility: Do you have the data, resources, and expertise required?
  • Scalability: Can the solution create value beyond a single team or department?

A well-defined AI strategy prioritizes use cases that align with business goals rather than trends. This approach helps organizations avoid common AI planning mistakes and focus on initiatives that can deliver measurable results.

Mistake 4: Skipping the AI Planning and Discovery Phase

Many organizations are eager to move from idea to implementation as quickly as possible. However, rushing into development without proper planning is one of the most costly AI implementation mistakes businesses can make.

The planning and discovery phase helps organizations validate use cases, assess data readiness, identify potential risks, and define success metrics before significant resources are committed. When this step is skipped, teams often encounter unexpected challenges that delay progress and increase costs.

What Happens When Planning Is Overlooked?


Without PlanningWith Proper Discovery
Unclear project scopeClearly defined objectives
Data issues discovered lateData readiness assessed early
Misaligned stakeholder expectationsShared understanding of goals
Higher risk of delays and reworkSmoother implementation process


Many cases of AI project failure can be traced back to decisions made before development even begins. A lack of preparation often leads to unrealistic timelines, budget overruns, and solutions that fail to address the intended business problem.

Common AI Planning Mistakes

  • Starting development without defining KPIs.
  • Failing to evaluate data quality and availability.
  • Overlooking compliance and governance requirements.
  • Not identifying key stakeholders early.
  • Underestimating implementation costs and timelines.

How to Avoid It

Before launching an AI initiative, create a discovery roadmap that covers:

  • Business objectives and expected outcomes.
  • Data availability and quality assessment.
  • Technical and operational requirements.
  • Risk, compliance, and governance considerations.
  • Success metrics and measurement plans.

A strong AI strategy begins long before implementation. Organizations that invest time in planning and discovery are better positioned to avoid costly setbacks and achieve sustainable business results.

Mistake 5: Understanding Data Quality Requirements

AI systems are only as reliable as the data they learn from. Even the most advanced models can produce inaccurate, biased, or inconsistent results when trained on poor quality data. This is why data-related issues remain one of the leading causes of AI project failure.

Many organizations assume they have enough data to support an AI initiative, only to discover that the data is incomplete, outdated, duplicated, or spread across multiple systems. These challenges can significantly affect model performance and business outcomes.

Common Data Quality Issues


Data ChallengePotential Impact
Missing dataIncomplete insights and predictions
Inaccurate recordsUnreliable outputs
Duplicate entriesDistorted results
Inconsistent formatsIntegrations and processing challenges
Siloed data sourcesLimited visibility across operations


Without addressing these issues, businesses risk making decisions based on flawed information.

Warning Signs of Poor Data Readiness

  • Data is stored across disconnected systems.
  • Teams frequently question data accuracy.
  • There are no established data governance processes.
  • Significant manual cleaning is required before analysis.
  • Different departments report conflicting figures.

These problems often originate from overlooked AI planning mistakes and become more expensive to fix as the project progresses.

How to Avoid It

Before implementation begins, assess the quality, accessibility, and relevance of your data.

Focus on:

  • Establishing data governance standards.
  • Identifying and resolving data inconsistencies.
  • Centralizing critical data sources where possible.
  • Defining data ownership and accountability.
  • Conducting a data readiness assessment before development.

A successful AI strategy treats data as a business asset rather than a technical requirement. Organizations that prioritize data quality early are far more likely to avoid costly AI implementation mistakes and achieve reliable results from their AI initiatives.

Mistake 6: Expecting Immediate ROI From AI Investments

AI has the potential to deliver significant business value, but expecting instant results is one of the most common AI implementation mistakes organizations make. Unlike traditional software deployments, AI initiatives often require time for data preparation, model training, testing, optimization, and user adoption.

When expectations are unrealistic, stakeholders may become frustrated if results do not appear within the first few weeks or months. This can lead to reduced support, budget cuts, or premature project termination.

The Reality of AI ROI


Unrealistic ExpectationRealistic Expectation
Immediate business impactGradual improvement over time
Instant cost savingsValue increases as models mature
Perfect results from day oneContinuous optimization is required
Company-wide transformationSuccess starts with focused use cases


The most successful organizations view AI as a long-term investment rather than a quick fix.

Why Unrealistic Expectations Create Problems

  • Projects are evaluated before they have time to mature.
  • Teams focus on short-term wins instead of sustainable outcomes.
  • Stakeholder confidence declines when expectations are not met.
  • Resources may be redirected before value is fully realized.

These factors frequently contribute to AI project failure, even when the underlying solution has strong potential.

How to Avoid It

Set realistic expectations from the beginning by defining both short-term and long-term goals.

Consider tracking:

  • Operational efficiency improvements.
  • Time savings from automation.
  • Customer experience metrics.
  • Cost reductions over time.
  • Revenue growth opportunities.

A well-planned AI strategy includes clear milestones, realistic timelines, and measurable KPIs. This helps organizations avoid common AI planning mistakes and evaluate progress based on business outcomes rather than unrealistic expectations.

Mistake 7: Ignoring Change Management and Employee Adoption

An AI solution can be technically successful and still fail to deliver business value if employees do not use it. This is why overlooking change management is one of the most expensive AI implementation mistakes organizations make.

Many businesses focus heavily on development and deployment but spend little time preparing employees for new workflows, responsibilities, or tools. As a result, resistance increases, adoption remains low, and the expected benefits never fully materialize.

Why Employees Resist AI Initiatives

Common concerns include:

  • Fear of job displacement.
  • Lack of understanding about how AI works.
  • Uncertainty about new processes and responsibilities.
  • Limited training and support.
  • Concerns about the accuracy of AI-generated outputs.

When these concerns are not addressed, adoption becomes a significant barrier to success.

The Impact of Poor Adoption


ChallengeBusiness Impact
Low user engagementReduced return on investment
Resistance to new workflowsSlower implementation progress
Lack of trust in AI outputsInconsistent usage across teams
Inadequate trainingLower productivity gains


These issues often contribute to AI project failure, even when the technology performs as expected.

How to Avoid It

Organizations can improve adoption by:

  • Involving employees early in the process.
  • Clearly communicating the purpose and benefits of AI.
  • Providing role-specific training and support.
  • Gathering feedback throughout implementation.
  • Demonstrating how AI supports employees rather than replacing them.

A successful AI strategy focuses on people as much as technology. Businesses that prioritize change management are more likely to avoid costly AI planning mistakes and achieve lasting value from their AI investments.

Mistake 8: Building AI Without Governance and Compliance Controls

Many organizations focus on what AI can do but spend far less time considering how it should be managed. This oversight is one of the most serious AI implementation mistakes, especially as regulations and data privacy requirements continue to evolve.

Without proper governance, AI systems can create risks related to data security, compliance, transparency, and accountability. What starts as a promising initiative can quickly become a legal, operational, or reputational challenge.

Why AI Governance Matters

AI governance establishes the policies, processes, and responsibilities needed to ensure AI systems are used responsibly and consistently.

Key areas include:

  • Data privacy and protection.
  • Regulatory compliance.
  • Model transparency.
  • Risk management.
  • Accountability and oversight.

When these areas are ignored, organizations expose themselves to unnecessary risks that can undermine the success of the entire initiative.

Common Governance Gaps


Governance IssuePotential Impact
No data usage policiesPrivacy and compliance concerns
Limited model oversightUnreliable or biased outputs
Unclear ownershipLack of accountability
Inadequate risk assessmentIncreased operational risk
Poor documentationDifficulty meeting compliance requirements


These gaps often remain unnoticed until they create significant business problems.

How to Avoid It

Before deploying AI solutions, organizations should establish a governance framework that includes:

  • Clear policies for data collection and usage.
  • Defined roles and responsibilities.
  • Regular model monitoring and audits.
  • Risk assessment procedures.
  • Compliance reviews for applicable regulations.

A strong AI strategy balances innovation with accountability. By building governance into the foundation of an AI initiative, organizations can reduce risk, strengthen trust, and avoid many of the factors that contribute to AI project failure.

Mistake 9: Selecting the Wrong AI Models or Tools

With hundreds of AI platforms, models, and frameworks available today, it is easy to assume that choosing the most advanced solution will produce the best results. In reality, selecting technology that does not align with business requirements is one of the most common AI implementation mistakes organizations make.

Common Tool Selection Mistakes

  • Choosing tools based on popularity rather than business needs.
  • Prioritizing features over practical requirements.
  • Ignoring integration capabilities.
  • Overlooking scalability and maintenance costs.
  • Selecting models that require data the organization doesn’t have.

These decisions can create technical challenges that slow implementation and reduce ROI.

Choosing the Right Fit


ConsiderationKey Question
Business GoalsDoes the tool support the intended outcome?
Data RequirementsDo we have the data needed to make it effective?
IntegrationWill it work with existing systems and workflows?
ScalabilityCan it support future growth and expansion?
CostDoes the expected value justify the investment?


The best solution is not always the most powerful one. It is the one that solves the business problem efficiently and sustainably.

How to Avoid It

Before selecting an AI platform or model:

  • Define business and technical requirements.
  • Evaluate multiple solutions against the same criteria.
  • Conduct pilot testing before full deployment.
  • Assess integration and long-term maintenance needs.
  • Consider both current and future business requirements.

Thorough testing is also essential before deployment, and quality assurance services can help validate functionality, performance, security, and reliability across AI-powered applications.

A well-defined AI strategy helps organizations evaluate technology through a business lens rather than chasing trends. This approach reduces unnecessary complexity and lowers the risk of AI project failure caused by poor technology decisions.

Mistake 10: Failing to Integrate AI into Existing Workflows

An AI solution cannot deliver value if it operates separately from the processes employees use every day. Yet many organizations treat deployment as the finish line, only to discover that their new AI system is disconnected from existing workflows, tools, and decision-making processes.

Businesses looking to automate complex workflows can also explore agentic AI development services to build AI agents that can make decisions, execute tasks, and interact with existing business systems.

This is one of the most overlooked AI implementation mistakes because the technology may work exactly as intended, but employees are forced to switch between systems, manually transfer data, or bypass the solution altogether.

Signs of Poor AI Integration

  • Employees continue using manual processes.
  • AI outputs require significant manual intervention.
  • Teams switch between multiple platforms to complete a task.
  • Adoption remains low despite successful deployment.
  • Business processes remain largely unchanged after implementation.

When AI is not embedded into day-to-day operations, its impact is often limited.

Workflow Integration Matters More Than Deployment


Poor IntegrationEffective Integration
AI operates as a separate toolAI becomes part of existing workflows
Additional manual steps are requiredProcesses become faster and simpler
Low employee engagementHigher adoption and usage
Limited business impactMeasurable operational improvements


The goal should not be to add another tool to an employee’s workload. The goal should be to make it easier, faster, or more accurate.

How to Avoid It

To maximize value from AI initiatives:

  • Map existing workflows before implementation.
  • Identify where AI can create the greatest impact.
  • Minimize process disruptions where possible.
  • Integrate AI outputs into systems employees already use.
  • Collect user feedback and refine workflows after deployment.

A successful AI strategy focuses on business processes, not just technology. Organizations that prioritize workflow integration are far more likely to avoid AI project failure and realize the full value of their AI investments.

Mistake 11: Neglecting Monitoring and Performance Measurement

Many organizations stop evaluating their AI initiatives once the solution is deployed. However, AI is not a “set it and forget it” technology. Models can lose accuracy, business requirements can change, and data quality can decline over time.

For organizations managing machine learning models in production, MLOps consulting services can help establish automated pipelines, model monitoring, lifecycle management, and continuous performance optimization.

Failing to monitor performance is one of the most costly AI implementation mistakes because issues often go unnoticed until they begin affecting business outcomes.

Why Continuous Monitoring Matters

Without ongoing measurement, organizations cannot determine whether an AI solution is delivering the expected value or identify opportunities for improvement.

Key areas to track include:

  • Model accuracy and reliability.
  • Business KPIs and ROI.
  • User adoption rates.
  • System performance and uptime.
  • Data quality trends.

Regular monitoring helps teams detect problems early and make informed adjustments.

What Happens Without Performance Tracking?


No MonitoringContinuous Monitoring
Declining model accuracy goes unnoticedIssues are identified and addressed early
Difficult proving ROIClear visibility into business impact
Reduced stakeholder confidenceData-driven decision making
Missed optimization opportunitiesOngoing performance improvements


Even high-performing AI solutions require periodic evaluation to remain effective.

How to Avoid It

Create a performance management framework before deployment.

This should include:

  • Clearly defined KPIs.
  • Regular performance reviews.
  • Automated monitoring where possible.
  • Feedback mechanisms for end users.
  • A process for retraining and improving models.

A strong AI strategy does not end at implementation. Organizations that continuously measure and optimize their AI initiatives are better positioned to avoid AI project failure and sustain long-term business value.
Mistake 12: Scaling AI Before Proving Value

One successful pilot does not automatically mean an AI solution is ready for organization-wide deployment. Yet many businesses rush to expand AI initiatives before validating their impact, making this one of the most common AI implementation mistakes.

Scaling too early can amplify existing issues. If the solution has data quality challenges, adoption barriers, or unclear ROI, those problems become more difficult and expensive to resolve at a larger scale.

Why Premature Scaling Is Risky

Before expanding an AI initiative, organizations should have clear evidence that it delivers measurable business value.
Consider the difference:


Scaling Too EarlyScaling at the Right Time
Limited proof of ROIDemonstrated business impact
Unresolved technical issuesStable and reliable performance
Low user retentionStrong engagement and feedback
Increased costs and complexityControlled and sustainable growth


The objective is not to scale quickly. The objective is to scale successfully.

Signs You’re Not Ready to Scale

  • Success metrics have not been achieved consistently.
  • User adoption remains low.
  • Performance varies across different scenarios.
  • Business value cannot be clearly measured.
  • Teams are still addressing operational challenges.

These warning signs often indicate that further refinement is needed before broader deployment.

How to Avoid It

Before scaling an AI initiative:

  • Validate results through a pilot program.
  • Measure ROI against predefined KPIs.
  • Gather feedback from users and stakeholders.
  • Resolve technical and operational issues.
  • Develop a phased rollout plan.

A well-executed AI strategy treats scaling as a milestone, not a starting point. Organizations that prove value first are far more likely to avoid AI project failure and achieve sustainable growth from their AI investments.

Mistake 13: Choosing the Wrong AI Development Partner

Even with a strong use case and a clear roadmap, the success of an AI initiative can depend heavily on the expertise of the team building it. Choosing a partner based solely on cost, promises, or technical jargon is one of the most expensive AI implementation mistakes organizations make.

An inexperienced partner may deliver a functional solution, but struggle with business alignment, scalability, integration, governance, or long-term support. These gaps can delay outcomes and increase the risk of AI project failure.

What to Look for in an AI Partner

The right partner should bring more than technical capabilities. They should understand your business goals and provide guidance throughout the implementation journey.


Evaluation AreaWhat to Assess
Industry ExperienceHave they solved similar business challenges?
Technical ExpertiseDo they have experience with relevant AI technologies?
Strategic GuidanceCan they help define use cases and success metrics?
Integration CapabilitiesCan they work with your existing systems?
Post-Deployment SupportDo they offer optimization and ongoing support?


A strong partner acts as an advisor, not just a service provider.

Red Flags to Watch For

  • Promising unrealistic timelines or ROI.
  • Focusing only on technology without discussing business outcomes.
  • Limited experience with similar projects.
  • Lack of a clear implementation methodology.
  • No plan for governance, monitoring, or long-term support.

These issues often surface later in the project when they are more difficult and costly to address.

How to Avoid It

Before selecting an AI partner:

  • Review relevant case studies and client success stories.
  • Assess both technical and business expertise.
  • Ask about implementation processes and governance practices.
  • Evaluate communication and collaboration capabilities.
  • Clarify expectations around support, maintenance, and scalability.

A successful AI strategy requires the right combination of technology, planning, and expertise. Partnering with an experienced AI development team can help organizations avoid common AI planning mistakes, reduce implementation risks, and accelerate the path to measurable business outcomes.

AI Planning Mistakes That Occur Before Development Begins

AI Project Planning Mistakes

Many organizations assume that AI projects fail during development or deployment. In reality, some of the most damaging AI planning mistakes happen long before a solution is built. Decisions made during the planning phase influence everything from project scope and budget to adoption and ROI.

When organizations skip critical planning activities, they often spend months addressing issues that could have been identified in the early stages. This not only increases costs but also raises the likelihood of AI project failure.

The table below highlights some of the most common planning mistakes and their potential impact:


AI Planning MistakePotential Consequence
Lack of stakeholder alignmentConflicting priorities and delayed decisions
Undefined success metricsDifficulty measuring ROI and business impact
Poor data readiness assessmentUnexpected implementation challenges
No implementation roadmapScope creep and project delays
Underestimating total costsBudget overruns and resource constraints


Lack of Stakeholder Alignment

AI initiatives often involve multiple teams, including leadership, operations, IT, data, compliance, and end users. When these stakeholders are not aligned on goals, priorities, and expectations, projects can lose momentum before they even begin.

Common signs of misalignment:

  • Different teams have different definitions of success.
  • Decision-making becomes slow and inconsistent.
  • Business and technical teams operate in silos.

Undefined Success Metrics

One of the most common AI implementation mistakes is launching a project without knowing how success will be measured.

Before development starts, organizations should establish clear KPIs such as:

  • Cost reduction targets.
  • Productivity improvements.
  • Customer satisfaction metrics.
  • Revenue growth opportunities.

Without measurable outcomes, proving the value of an AI initiative becomes difficult.

Incomplete Data Readiness Assessment

Many businesses overestimate the quality and availability of their data. Discovering data issues after development begins can lead to delays, rework, and additional costs.

Before moving forward, evaluate:

  • Data quality and accuracy.
  • Data accessibility.
  • Data governance practices.
  • Availability of historical data.

No Implementation Roadmap

A roadmap provides structure and direction throughout the project lifecycle. Without one, teams often struggle with changing priorities, unrealistic timelines, and unclear responsibilities.

A basic roadmap should outline:

  1. Business objectives.
  2. Project milestones.
  3. Resource requirements.
  4. Success metrics.
  5. Deployment and scaling plans.

Budgeting Only for Development

Many organizations allocate budgets for building AI solutions but overlook expenses related to integration, training, governance, maintenance, and optimization.

To create a sustainable AI strategy, budgeting should account for the full lifecycle of the initiative rather than just the development phase.

The stronger the planning process, the lower the risk of costly mistakes later. Organizations that address these foundational gaps early are far more likely to achieve successful AI outcomes.

Warning Signs Your AI Project Is at Risk of Failure

Reasons Behind AI Project Failure

Not every AI initiative fails suddenly. In most cases, warning signs appear weeks or even months before major issues become visible. The challenge is that many organizations overlook these signals until they begin affecting timelines, budgets, or business outcomes.

Recognizing these early indicators can help teams address problems before they turn into costly AI implementation mistakes.

Objectives Continue to Change

Project goals should evolve only when business requirements change. If objectives are constantly shifting, teams may struggle to prioritize tasks, measure success, or maintain momentum.

Potential impact:

  • Scope creep.
  • Delayed timelines.
  • Misaligned stakeholder expectations.

Teams Lack Ownership

Successful AI initiatives require clear accountability. When no individual or team is responsible for driving outcomes, decision-making slows and progress becomes inconsistent.

Common signs include:

  • Unclear roles and responsibilities.
  • Delayed approvals.
  • Frequent project bottlenecks.

AI Outputs Are Not Trusted

Even highly accurate AI systems can fail if employees do not trust the results. Low confidence often leads users to ignore recommendations or return to manual processes.


Warning SignBusiness Impact
Employees double-check every outputReduced productivity gains
Teams avoid using AI recommendationsLow adoption rates
Frequent complaints about reliabilityLimited business value


This issue is often linked to poor change management and communication.

Adoption Rates Remain Low

One of the clearest indicators of potential AI project failure is low user engagement after deployment.

If employees are not actively using the solution, investigate whether the problem is related to:

  • Training gaps.
  • Workflow integration issues.
  • Lack of perceived value.
  • User experience challenges.

Costs Rise Without Measurable Results

AI projects require investment, but costs should be accompanied by visible progress and measurable outcomes.

If expenses continue to increase while KPIs remain unchanged, it may indicate:

  • Poor project planning.
  • Misaligned use cases.
  • Technology selection issues.
  • Gaps in the overall AI strategy.

A Practical AI Strategy Framework to Reduce Failure Risk

AI Strategy for Project Success


Avoiding AI implementation mistakes is not just about fixing problems as they arise. It requires a structured approach that aligns business goals, data, people, and technology from the start. Organizations that consistently achieve positive outcomes follow a clear AI strategy rather than pursuing isolated AI initiatives.

The framework below can help reduce the risk of AI project failure and create a stronger foundation for long-term success.

Step 1: Define Business Outcomes First

Before discussing tools, models, or platforms, define the business outcome you want to achieve.

Ask questions such as:

  • What problem are we solving?
  • How will success be measured?
  • What business value do we expect?

Clear objectives help prevent many common AI planning mistakes later in the project.

Step 2: Assess Organizational Readiness

Not every organization is ready to implement AI at scale.

Evaluate:

  • Data quality and availability.
  • Technical infrastructure.
  • Internal expertise.
  • Leadership support.
  • Employee readiness.

Identifying gaps early reduces implementation risks and unexpected delays.

Step 3: Prioritize High-Impact Use Cases

Rather than launching multiple AI initiatives at once, focus on use cases that offer measurable business value.
Prioritization criteria:

  • Business impact.
  • Feasibility.
  • Scalability.
  • Resource requirements.

This approach helps organizations generate quick wins while minimizing risk.

Step 4: Establish Governance and Accountability

Strong governance ensures AI systems remain secure, compliant, and aligned with organizational objectives.

Key focus areas include:

  • Data governance.
  • Compliance requirements.
  • Risk management.
  • Performance monitoring.
  • Stakeholder accountability.

Step 5: Launch a Pilot Before Scaling

Pilot projects provide an opportunity to validate assumptions, test performance, and gather user feedback before broader deployment.

A pilot should answer three critical questions:

  • Does the solution work?
  • Do users adopt it?
  • Does it deliver measurable business value?

Step 6: Measure, Improve, and Scale

AI initiatives should evolve based on data, feedback, and performance insights.

Track metrics such as:

  • ROI.
  • Productivity gains.
  • Cost savings.
  • User adoption.
  • Customer impact.

Once value has been demonstrated consistently, organizations can scale with greater confidence and a lower risk of AI project failure.

By following this framework, businesses can move beyond experimentation and build an AI strategy that supports sustainable growth, operational efficiency, and measurable outcomes.

AI Roadmap and Strategy Guide

Real Examples of AI Project Failure and the Lessons Learned

Many organizations learn valuable lessons from failed AI initiatives, but those lessons often come at a high cost. Examining real-world scenarios helps illustrate how common AI implementation mistakes can affect business outcomes and what organizations can do differently.

Example 1: Poor Data Led to Inaccurate Predictions

A retail company invested in an AI-driven demand forecasting solution to improve inventory planning. However, the model was trained on incomplete and inconsistent historical data.

What went wrong?

  • Data quality issues were identified too late.
  • Historical records contained inaccuracies.
  • No comprehensive data readiness assessment was conducted.

Lesson learned: Even advanced AI models cannot compensate for poor quality data. Data preparation should be a priority before development begins.

Example 2: Strong Technology, Weak Adoption

A financial services organization deployed an AI-powered recommendation system to support internal decision-making. While the technology performed well during testing, employees rarely used it after launch.


ChallengeOutcome
Limited employee trainingLow adoption rates
Lack of trust in AI outputsContinued reliance on manual processes
Poor workflow integrationMinimal business impact


Lesson learned: Technology alone does not drive success. Employee adoption and change management play a critical role in achieving measurable value.

Example 3: Scaling Too Quickly

A company achieved positive results from a small AI pilot and immediately expanded the solution across multiple departments. As usage increased, data inconsistencies, integration issues, and performance challenges began to emerge.

What went wrong?

  • The pilot did not fully validate scalability.
  • Operational challenges were not resolved before expansion.
  • Governance processes were still evolving.

Lesson learned: One of the most common AI planning mistakes is assuming a successful pilot guarantees enterprise-wide success. Scaling should happen only after performance, adoption, and ROI have been validated.

Key Takeaways From These Examples


Across industries, the causes of AI project failure are often surprisingly similar:

  • Poor data quality.
  • Weak stakeholder alignment.
  • Low employee adoption.
  • Inadequate planning.
  • Premature scaling.

Organizations that address these challenges early and build a clear AI strategy are far more likely to achieve sustainable results from their AI investments.

AI Implementation Readiness Checklist

Before investing in AI, organizations should evaluate whether they have the foundation needed for success. Many AI implementation mistakes occur because businesses focus on the technology while overlooking AI readiness factors such as data quality, governance, stakeholder alignment, and success measurement.

Use the checklist below to assess your organization’s preparedness before launching an AI initiative.

Strategic Readiness


QuestionStatus
Have you identified a clear business problem to solve?Yes/No
Are AI objectives aligned with business goals?Yes/No
Have success metrics and KPIs been defined?Yes/No
Is there executive sponsorship for the initiative?Yes/No


Data and Technology Readiness


QuestionStatus
Is the required data available and accessible?Yes/No
Is the data accurate, complete, and up to date?Yes/No
Can your existing infrastructure support AI adoption?Yes/No
Have integration requirements been evaluated?Yes/No


Organizational Readiness


QuestionStatus
Are stakeholders aligned on project goals?Yes/No
Have ownership and responsibilities been defined?Yes/No
Is there a plan for employee training and adoption?Yes/No
Have potential risks and resistance factors been identified?Yes/No


Governance and Risk Readiness


QuestionStatus
Are data governance policies in place?Yes/No
Have compliance requirements been reviewed?Yes/No
Is there a framework for monitoring AI performance?Yes/No
Have accountability and oversight roles been assigned?Yes/No


How To Interpret Your Results


Readiness ScoreAssessment
13-16 Yes AnswersStrong foundation for AI implementation
9-12 Yes AnswersModerate readiness with some gaps to address
5-8 Yes AnswersSignificant preparation required before implementation
0-4 Yes AnswersHigh risk of AI project failure without further planning


Organizations that complete this assessment before starting an initiative are better positioned to avoid common AI planning mistakes, allocate resources effectively, and build an AI strategy that delivers measurable business outcomes.

How AI Consulting Partners Help Prevent Implementation Mistakes

Building and scaling AI initiatives requires more than technical expertise. Organizations must align business objectives, data, processes, governance, and adoption strategies to achieve meaningful results. This is where the right consulting partner can make a significant difference.

Experienced AI consultants help organizations identify and address potential risks before they become costly AI implementation mistakes. They bring proven frameworks, industry knowledge, and practical experience that can accelerate outcomes while reducing uncertainty.

Where AI Consulting Partners Add Value


AreaHow Consultants Help
StrategyDefine goals, use cases, and success metrics
PlanningCreate implementation roadmaps and timelines
Data ReadinessAssess data quality and infrastructure requirements
GovernanceEstablish compliance and risk management frameworks
AdoptionSupport training, communication, and change management
OptimizationMonitor performance and identify improvement opportunities


Common Challenges They Have Solved

Many businesses seek external expertise when they encounter challenges such as:

  • Unclear AI priorities.
  • Limited in-house expertise.
  • Difficulty identifying high-value use cases.
  • Concerns around compliance and governance.
  • Low adoption or uncertain ROI.

Addressing these issues early can significantly reduce the likelihood of AI project failure.

Questions to Ask Before Choosing an AI Partner

Not all consulting firms offer the same level of expertise. Before selecting a partner, consider the following:

  • Do they have experience with similar projects or industries?
  • Can they demonstrate measurable business outcomes?
  • Do they provide strategic guidance in addition to technical support?
  • How do they approach governance, security, and compliance?
  • What support do they offer after deployment?

The Value of Expert Guidance

A strong AI strategy is built on informed decisions, realistic expectations, and a clear roadmap. The right consulting partner can help organizations avoid common AI planning mistakes, accelerate implementation, and maximize the value of their AI investments.

Rather than reacting to problems after they occur, businesses can benefit from expert guidance that helps them plan, execute, and scale AI initiatives with greater confidence.

Conclusion

AI has the potential to transform operations, improve decision-making, and create measurable business value. However, success is rarely determined by technology alone. As we’ve seen throughout this guide, many cases of AI project failure stem from avoidable decisions related to planning, execution, governance, and adoption.
From unclear objectives and poor data quality to weak change management and premature scaling, these AI implementation mistakes can significantly impact outcomes and ROI. The good news is that most of these challenges can be prevented with the right preparation and a structured approach, along with the help of an experienced AI app development company.

Organizations that invest time in avoiding common AI planning mistakes are better equipped to identify high-value use cases, align stakeholders, manage risks, and measure success effectively. More importantly, they are able to build an AI strategy that supports long-term business goals rather than short-term experimentation.

As AI adoption continues to grow, the organizations that succeed will not necessarily be the first to implement AI. They will be the ones that approach it with clear objectives, strong foundations, and a commitment to continuous improvement.

AI Strategy and Implementation

RAG vs Fine-Tuning: Which Approach for Your Enterprise Knowledge Base?

Introduction

RAG vs fine-tuning for enterprise knowledge base development is quickly becoming one of the most critical AI architecture decisions for startups, SMEs, and large enterprises building internal AI chatbots, customer support automation, and knowledge-driven business systems. As organizations invest heavily in AI, the challenge is no longer whether to implement AI-powered knowledge bases. It is choosing the right foundation that balances cost, scalability, accuracy, speed, and long-term maintainability. This is why many organizations now seek specialized AI consulting before committing to a production-ready architecture.

For CXOs, product leaders, and engineering teams, the retrieval augmented generation vs fine tuning decision directly impacts how efficiently enterprise knowledge can be accessed, updated, governed, and scaled across departments. A startup may prioritize faster deployment and lower infrastructure costs, while an enterprise handling compliance-heavy workflows may focus more on auditability, response reliability, and domain-specific reasoning. Choosing the wrong approach can lead to expensive retraining cycles, outdated answers, rising infrastructure costs, and AI systems that struggle to adapt as business knowledge evolves. As a result, businesses increasingly partner with teams specializing in LLM development and enterprise AI deployment to reduce implementation risks and build scalable knowledge architectures.

At a high level, RAG enables AI systems to retrieve information from external company documents before generating responses, making it ideal for dynamic and frequently changing knowledge bases. Fine-tuning, on the other hand, trains models on domain-specific behavior and terminology, helping organizations achieve more specialized reasoning and consistent outputs. The rag vs fine tuning debate ultimately comes down to how businesses manage knowledge freshness, operational complexity, query volume, and enterprise-scale AI performance through the right AI development strategy.

This guide explains how RAG and fine-tuning work, where each approach performs best, how vector databases support modern retrieval pipelines, practical techniques for reducing AI hallucinations, and the realistic cost of building enterprise AI knowledge-base systems in the coming years.

How RAG Works – The Retrieval-First Approach

How RAG Works The Retrieval First Approach

RAG (Retrieval-Augmented Generation) is an AI architecture used in Generative AI development where the language model retrieves relevant company documents before generating a response. Instead of depending entirely on pre-trained knowledge, the system searches through enterprise data sources such as internal documentation, support articles, policies, PDFs, CRM records, or knowledge bases to fetch the most relevant information for a query.

A simple way to understand RAG is to think of it as an open-book exam. Rather than memorizing everything, the AI system “looks up” information before answering. This makes RAG highly effective for startups, SMEs, and enterprises where business knowledge changes frequently and information must stay updated without constant retraining.

One of the biggest advantages of RAG is that enterprise documents remain separate from the model itself. If a company updates a policy, onboarding workflow, pricing document, or compliance guideline, the AI system can immediately access the latest version without retraining the model. This makes RAG systems faster to maintain, easier to scale, and more practical for dynamic business environments.

RAG is also the most cost-effective starting point for most organizations building AI-powered knowledge systems.

Pros of RAG

  • Uses the latest business data without retraining
  • Faster deployment and lower initial development cost
  • Transparent responses with source citations
  • No expensive GUP training infrastructure required
  • Easier to scale across growing document repositories

Many businesses beginning their enterprise AI journey start with RAG-based systems alongside strategic AI consulting to validate architecture decisions and reduce deployment risks.

Cons of RAG

  • Response quality depends heavily on retrieval quality
  • Slightly slower responses due to document retrieval
  • Can struggle with highly complex multi-document reasoning
  • Requires well-structured enterprise documentation
  • Poor chunking or retrieval setup can reduce answer accuracy

How Fine-Tuning Works – The Training Approach

How Fine-Tuning Works The Training Approach

Fine-tuning is an AI approach where a language model is trained on domain-specific data, so it learns specialized terminology, workflows, response patterns, and business logic. Instead of retrieving external documents during every query, the knowledge and behavior become part of the model itself.

A simple way to understand fine-tuning is to compare it to training a new employee. Rather than handing someone a manual every time they need information, you train them deeply on company processes so they can respond instantly and consistently. This makes fine-tuning useful for organizations that require highly structured outputs, industry-specific reasoning, or consistent communication standards.

Unlike RAG systems, where documents remain external, fine-tuning embeds domain knowledge into the model weights. This allows faster responses because there is no retrieval step involved during interference. Fine-tuned systems are often used for specialized enterprise copilots, workflow automation, compliance-heavy tasks, and internal systems requiring standardized language and decision-making.

Pros of Fine-Tuning

  • Faster response generation
  • Better domain-specific reasoning capabilities
  • More consistent tone, terminology, and output structure
  • Lower per-query cost at a very large scale
  • Useful for repetitive enterprise workflows

Fine-tuned systems are particularly valuable for businesses investing in advanced LLM development to create highly customized AI experiences tailored to industry-specific operations.

Cons of Fine-Tuning

  • Expensive training and infrastructure costs
  • Knowledge becomes outdated as business information changes
  • Requires training when documents or workflows evolve
  • Needs large, high-quality training datasets
  • Risk of catastrophic forgetting during retraining

The fine tuning vs rag decision often comes down to whether an organization prioritizes knowledge freshness or highly specialized AI behavior. For many enterprises, fine-tuning becomes more valuable after the foundational retrieval architecture is already in place.

RAG vs Fine-Tuning – Decision Framework

Choosing between RAG and fine-tuning depends on how your organization manages knowledge, handles updates, controls costs, and scales AI operations over time. While both approaches improve enterprise AI performance, they solve very different business problems.

For most startups, SMEs, and enterprises building AI-powered knowledge systems for the first time, RAG is usually the safer and faster starting point. It is easier to deploy, cheaper to maintain, and better suited for environments where documents, policies, and workflows change frequently. Fine-tuning becomes more valuable when businesses need highly specialized reasoning, standardized outputs, or lower query costs at a very large scale.

RAG vs Fine Tuning Decision Table

FactorRAG WinsFine-Tuning Wins
Data changes frequentlyYesNo
Budget under $50KYesNo
Need source citationsYesNo
Complex domain reasoningNoYes
High query volumeNoYes
Small training datasetYesNo
Regulated industry audit trailsYesNo
Custom terminology and toneNoYes

When RAG Makes More Sense

RAG is usually the better option when businesses:

  • Update documents frequently
  • Need transparent AI responses
  • Want faster deployment
  • Have limited AI infrastructure
  • Require a scalable internal search

This is why many organizations begin with RAG during early-stage AI consulting and architecture planning.

When Fine-Tuning Makes More Sense

Fine-tuning becomes valuable when organizations need:

  • Highly specialized domain reasoning
  • Structured outputs
  • Repetitive workflow automation
  • Consistent enterprise terminology
  • Lower query cost at a very large scale

Businesses investing in advanced LLM development often combine fine-tuned models with retrieval systems for better enterprise performance.

Best Enterprise Strategy in 2026

For most enterprises, the strongest long-term approach is now:

  • RAG for real-time knowledge retrieval
  • Fine-tuning for reasoning and behavioral optimization

This hybrid AI development strategy, including Agentic AI with RAG, helps organizations balance:

  • Scalability
  • Knowledge freshness
  • Operational efficiency
  • Response accuracy
  • Enterprise-grade reliability

Get AI Architecture Consultation

RAG Architecture – Embeddings, Vector DB, & Retrieval Pipeline

A RAG implementation architecture with vector database is built around one core idea: retrieve the most relevant information before the AI generates a response. Instead of storing business knowledge directly inside the model, the system pulls information from external enterprise documents in real time.

Step-By-Step RAG Pipeline

Step-By-Step RAG Pipeline


1. Document Ingestion

Enterprise documents are collected from sources such as:

  • PDFs
  • Confluence
  • SharePoint
  • CRM Systems
  • Internal wikis
  • Support documentation

These documents are then split into smaller chunks, usually:

  • 500 tokens -> better precision
  • 1000 tokens -> more context

2. Embedding Generation

Each document chunk is converted into vector embeddings using machine learning development models such as:

  • OpenAI ada-002
  • Cohere Embed
  • Sentence-transformers
  • BGE embeddings

These embeddings help the AI system understand semantic meaning instead of exact keywords.

3. Vector Database Storage

The embeddings are stored inside a vector database for fast similarity search. The vector database becomes the “memory layer” of the RAG system and allows instant retrieval of relevant business knowledge.

4. Query Processing

When a user asks a question:

  • the query is converted into an embedding
  • the vector database searches for the closest matching chunks
  • the most relevant documents are retrieved

This retrieval process usually takes 50 – 200ms latency.

5. Context Injection

The retrieved chunks are added to the LLM prompt as context.

This allows the model to answer using actual enterprise data instead of relying only on pre-trained memory.

6. Response Time

The LLM generates a final answer using:

  • Retrieved documents
  • Business context
  • Prompt instructions
  • Enterprise guardrails

RAG Architecture Flow

User Query -> Embedding Model -> Vector DB Search -> Top-K Results -> LLM + Context -> Response

Important RAG Design Decisions

Chunk Size

  • Smaller Chunks -> more accurate retrieval
  • Larger chunks -> better contextual understanding

Chunk Overlap

Most enterprise systems use a 10-20% overlap. This prevents information loss between chunk boundaries.

Top-K Retrieval

Most production systems retrieve 3-5 chunks per query. Too many chunks increase noise and reduce answer quality.

Re-Ranking

Advanced RAG systems use re-rankers such as:

  • Cohere Re-ranker
  • Cross-encoders
  • BM25 hybrid ranking

This improves retrieval relevance significantly.

For enterprises building production-scale knowledge systems, architecture quality directly impacts scalability, response accuracy, and hallucination control. This is where experienced AI development teams play a critical role in designing retrieval pipelines optimized for enterprise workloads.

Talk to AI Development Experts

Vector Database – Pinecone vs Weaviate vs Chroma vs Qdrant

Vector databases are the foundation of modern RAG systems. They store embeddings and help AI applications retrieve semantically relevant information in milliseconds. Choosing the right vector database depends on factors such as scalability, infrastructure ownership, query performance, and enterprise deployment requirements.

For startups and SMEs, ease of setup may matter most. Enterprises, on the other hand, usually prioritize scalability, hybrid search, compliance, and long-term infrastructure flexibility.

Pinecone

Pinecone is a fully managed vector database designed for fast deployment and minimal infrastructure management.

Best For: teams without dedicated DevOps resources, fast enterprise deployment, and managed cloud environments.

Pros:

  • easiest setup experience
  • highly scalable
  • strong documentation
  • fully managed infrastructure

Cons:

  • expensive on a large scale
  • vendor lock-in concerns
  • no self-hosted option

Weaviate

Weaviate combines open-source flexibility with managed cloud deployment options.

Best For: enterprises wanting hybrid search, organizations needing deployment flexibility, and teams combining keyword + semantic search.

Pros:

  • Hybrid search support
  • GraphQL API
  • Modular architecture
  • Open-source ecosystem

Cons:

  • Steeper learning curve
  • More infrastructure complexity

Chroma

Chroma is a lightweight open-source vector database focused on developer simplicity.

Best for: prototypes, MVPs, and smaller internal AI tools

Pros:

  • simple Python integration
  • developer-friendly
  • lightweight deployment
  • fast experimentation

Cons:

  • limited enterprise-scale maturity
  • fewer production-grade features

Qdrant

Qdrant is a Rust-based vector database optimized for high-performance enterprise retrieval.

Best For: performance-critical enterprise systems, large-scale semantic search, and advanced filtering use cases.

Pros:

  • extremely fast query speed
  • strong filtering capabilities
  • open-source flexibility
  • enterprise scalability

Cons:

  • smaller community compared to Pinecone
  • fewer third-party integrations

Vector Database Comparison Table

FeaturePineconeWeaviateChromaQdrant
HostingManagedBothSelf-hostedBoth
Best ForQuick setupHybrid searchPrototypingPerformance
PricingHigher Cost ($$$)Moderate Pricing ($$)FreeModerate Pricing ($$)
ScaleEnterpriseEnterpriseSmall-MidEnterprise

There is no universal “best” vector database for every business. Startups often prioritize deployment speed, while enterprises focus more on scalability, governance, and infrastructure control. During enterprise AI consulting and architecture planning, vector database selection becomes a critical decision because it directly impacts search quality, latency, operational cost, and long-term scalability.

Knowledge Base Chatbot – Development Cost by Complexity

The cost of building an AI-powered enterprise knowledge base depends on factors such as data complexity, integrations, compliance requirements, retrieval quality, and whether the system uses RAG, fine-tuning, or a hybrid architecture.

For most businesses, RAG-based systems are the more affordable starting point because they avoid expensive model training infrastructure. However, enterprise-scale AI platforms with advanced automation, compliance, and workflow intelligence require significantly larger investments.

Tier 1 – Basic RAG Chatbot

Estimated Cost – $15K – $40K

Timeline: 4-8 weeks

Best suited for: startups, internal knowledge assistants, small support teams, and basic document retrieval systems.

Typical Features:

  • Single data source
  • GPT-4 API integration
  • Basic vector search
  • Simple web interface
  • Internal employee usage
  • Limited analytics

Advantages:

  • Fastest deployment
  • Lower implementation risk
  • Ideal for MVP validation
  • Affordable starting point

Tier 2 – Production RAG Systems

Estimated Cost: $40K – $100K

Timeline: 2-4 months

Best suited for: SMEs, customer-facing AI assistants, multi-department knowledge systems, and scalable enterprise search

Typical Features:

  • Multiple data sources
  • Semantic + hybrid search
  • Re-ranking models
  • User authentication
  • Role-based access
  • Analytics dashboard
  • Feedback loop system

Advantages:

  • Better retrieval quality
  • Improved scalability
  • Enterprise-grade access control
  • Stronger operational visibility

This is usually the stage where companies begin investing more heavily in enterprise AI development to support growing operational and customer support workloads.

Tier 3 – Enterprise AI Knowledge Platform

Estimated Cost: $100K – $250K+

Timeline: 4 – 8 months

Best suited for: large enterprises, regulated industries, healthcare, finance, and legal operations.

Typical Features:

  • Hybrid RAG + fine-tuned models
  • Multi-language support
  • Advanced workflow automation
  • Compliance logging
  • Audit trails
  • CRM/ERP integrations
  • Custom UI/UX
  • Advanced governance controls

Advantages:

  • Enterprise-scale performance
  • Higher reasoning quality
  • Advanced security and compliance
  • Operational automation across departments

Ongoing Operational Costs

Even after deployment, enterprise AI systems require continuous operational investment.

Common Ongoing Costs

  • LLM API usage -> $500 – $5,000/month
  • Vector database hosting -> $100 – $2,000/month
  • Infrastructure monitoring
  • Retrieval optimization
  • Security updates
  • Maintenance -> 15 – 20% of annual build cost

The final investment depends heavily on document volume, user traffic, retrieval complexity, compliance requirements, and integration depth. Businesses planning long-term AI adoption often work with specialized LLM development teams early in the process to estimate infrastructure requirements and avoid unexpected scaling costs later.

Get Project Cost Estimation

Reducing Hallucinations – Grounding, Guardrails, & Verifications

Hallucinations are one of the biggest risks in enterprise AI systems. Inaccurate responses can lead to compliance violations, operational mistakes, customer misinformation, and loss of trust in AI-driven workflows.

For startups, hallucinations may create support inefficiencies. For enterprises operating in finance, healthcare, or legal environments, they can become serious business and regulatory risks. This is why modern RAG systems rely heavily on grounding, verification, and response guardrails.

1. Grounding with Citations

Grounding forces the LLM to generate answers only from retrieved enterprise documents.

Best Practice

  • Attach source references to every response
  • Force the model to cite supporting documents
  • Return “I don’t know” if no reliable source exists

Why it Matters

  • Improves trust
  • Increase transparency
  • Supports compliance requirements
  • Reduces fabricated responses

2. Chunk Relevance Scoring

Not every retrieved chunk should be passed to the LLM.

Modern RAG systems score retrieved documents based on semantic similarity before generating answers.

Common Practice

  • Minimum similarity threshold -> 0.75
  • Low-confidence retrievals are rejected
  • Only top-scoring chunks move forward

Benefit

  • Reduces noisy context
  • Improves answer precision
  • Lowers hallucination probability

3. Output Verification Layer

Advanced enterprise systems often use a second LLM call to verify whether the generated answer is actually supported by retrieved context.

Verification Checks

  • Factual consistency
  • Unsupported claims
  • Missing citations
  • Answer completeness

Trade-Off

  • Adds 200-500ms latency
  • Significantly improves reliability

This is increasingly becoming a standard practice in enterprise AI development for customer-facing systems.

4. Structured Output Constraints

Structured response formats reduce unpredictable LLM behavior.

Common Constraints

  • JSON schema validation
  • Predefined response templates
  • Controlled formatting
  • Limited output scope

Benefit

  • Prevents rambling responses
  • Improves downstream automation
  • Creates predictable AI behavior

5. Temperature Control

Temperature settings directly affect response creativity and hallucination rates.

Recommended Enterprise Settings

  • Factual AI systems -> 0.0 – 0.2
  • Balanced assistants -> 0.3 – 0.5
  • Creative generation -> higher values

Important Insight

Higher temperature increases creativity, but also increases hallucination risk.

6. Human-in-the-Loop Verification

High-risk enterprise workflows still require human oversight.

Common Enterprise Use Cases

  • Legal responses
  • Healthcare recommendations
  • Financial workflows
  • Compliance-sensitive outputs

Typical Workflow

  • Low-confidence answers are flagged
  • Human reviewers validate responses
  • Approved feedback improves future retrieval quality

Enterprise Hallucination Benchmarks

System TypeTarget Hallucination Rate
Basic RAG SystemUnder 5%
Enterprise Production SystemUnder 2%
Regulated IndustriesUnder 1%

Fine-tuned models can sometimes hallucinate less on domain-specific workflows because specialized behavior is embedded into the model itself. However, they still struggle with knowledge freshness and require retraining when enterprise information changes. This is why many organizations combine retrieval systems, guardrails, and verification layers as part of a broader AI consulting and governance strategy.

Build Reliable Enterprise AI

Semantic Search – Beyond Keyword Matching for Internal Docs

Traditional Keyword search often fails inside enterprise knowledge systems because employees rarely search using the exact wording found in documents. A support agent may search for “refund policy,” while the actual document is titled “return and exchange guidelines.” The keywords do not match, but the meaning does.

Semantic search solves this problem by understanding intent and contextual meaning instead of relying only on exact keyword matches.

How Semantic Search Works

Semantic search converts both:

  • Enterprise documents
  • User queries

Into vector embeddings.

The system then compares semantic similarity between the two and retrieves results based on meaning rather than exact phrasing.

Semantic Search Can Handle

  • Synonyms
  • Rephrased questions
  • Intent variations
  • Conversational queries
  • Natural language searches

This creates a significantly better search experience for employees, customers, and support teams.

Semantic Search Implementation Process

1. Document Preparation

Before indexing, enterprise documents are:

  • Cleaned
  • chunked
  • Standardized
  • Deduplicated

Well-structured data improves retrieval quality significantly.

2. Embedding Model Selection

The embedding model converts text into vectors.

Common Options

  • OpenAI ads – 002
  • Cohere Embed
  • Sentence-transformers
  • BGE models

Key Considerations

Businesses must balance:

  • Retrieval accuracy
  • Inference speed
  • Operational cost

During model selection.

3. Index Building

The generated embeddings are stored inside a vector database for fast semantic retrieval.

This creates the searchable knowledge layer powering AI assistant.

4. Search API Layer

When users submit queries:

  • The query becomes an embedding
  • The vector database searches nearest matches
  • Top relevant results are returned instantly

5. Hybrid Search Approach

Most enterprise systems combine:

  • Semantic search
  • Keyword search (BM25)

This hybrid approach improves both relevance and precision.

Business Impact of Semantic Search

Organizations implementing semantic search often report:

  • 40-60% improvement in search success rates
  • 25-35% reduction in support tickets
  • Faster employee onboarding
  • Lower internal knowledge friction
  • Improved productivity across departments

Semantic retrieval becomes especially valuable for enterprises managing thousands of internal documents across multiple teams and systems. As enterprise AI ecosystems grow, semantic search is increasingly becoming a foundational capability in modern LLM development and scalable AI knowledge infrastructure.

Conclusion

For most startups, SMEs, and enterprises, RAG is the best starting point because it offers faster deployment, lower implementation costs, easier knowledge updates, and better transparency through citation-based retrieval. Fine-tuning becomes more valuable when organizations need specialized reasoning, consistent outputs, and high-volume workflow automation.

In reality, the future of enterprise AI is not RAG or fine-tuning alone. The strongest enterprise systems increasingly combine both approaches to balance scalability, knowledge freshness, operational efficiency, and AI performance.

Our team specializes in AI consulting, LLM development services, and enterprise AI architecture for scalable knowledge base systems. Whether you are evaluating RAG, fine-tuning, or hybrid AI deployment, we can help you design the right strategy for long-term business growth.

Need help building an enterprise AI knowledge base? Get a free architecture consultation today.

Schedule a Free Consultation

React Native App Performance Optimization Guide: Checklist, Tools, and Proven Fixes for Faster Apps

Introduction

When Does React Native Performance Become a Business Problem?

At what point does a “slightly slow” app turn into lost users, low conversions, and negative reviews?

For most businesses, it does not happen suddenly. It builds quietly.

Your React Native app launches well. Early users engage. Features expand. But as complexity grows, performance starts slipping; startup time increases, scrolling feels less smooth, and occasional lags begin to appear. Nothing feels broken, but nothing feels fast either.

That is the danger zone.

Because users don’t report performance issues, they respond to them. They abandon sessions faster, interact less, and hesitate to return. And internally, teams often misread this as a feature or UX problem, when in reality, it is a performance bottleneck underneath.

Here is what makes it more challenging: React Native performance issues are rarely obvious and almost never caused by a single factor.

They usually come from a combination of:

  • JavaScript thread overload
  • Excessive communication over the native bridge
  • Inefficient rendering patterns
  • Poor list handling strategies
  • Memory leaks that worsen over time
  • Default configurations that were never optimized for scale

Individually, these don’t seem critical. Together, they create an experience that feels unreliable.

This guide is designed to change that.

Instead of scattered tips, you will get a structured React Native app performance optimization approach for 2026, including:

  • A practical, downloadable optimization checklist
  • Clear fixes for startup time, memory issues, and UI lag
  • Guidance on Hermes engine configuration and bundle optimization
  • Strategies to reduce bridge overhead and improve rendering performance
  • A migration path toward the New Architecture (Fabric & TurboModules)

More importantly, this guide helps you answer a critical business question:

Should you keep optimizing your current app, or is it time to rethink how it is built?

If you’re evaluating performance not just as a technical issue but as a growth factor, this will give you a clear path forward, especially when aligned with a structured react native app development approach.

Get a Free Performance Audit

Why React Native Performance Still Becomes a Bottleneck in 2026

React Native performance issues rarely come from the framework itself. They emerge when apps that were built for speed of launch are expected to perform under scale, with more users, more features, and more complex interactions.

In the early stages, everything feels smooth. But as the app grows, small inefficiencies begin to compound. What once worked efficiently starts creating friction, not instantly, but gradually enough that it is often overlooked until user experience is already affected.

Here are the key areas where performance typically starts breaking down:

1. JavaScript Thread Overload

React Native relies on a single JavaScript thread to handle most of the app logic and UI coordination. As your application grows, this thread starts carrying more responsibility than it was originally designed for.

  • Heavy computations block UI updates
  • Multiple asynchronous tasks compete for execution
  • User interactions get delayed

The result is subtle at first, slight lag, delayed taps, but becomes more noticeable as usage increase.

2. Excessive Native Bridge Communication

Every interaction between JavaScript and native code passes through the bridge. While efficient in controlled scenarios, excessive or poorly structured communications add latency.

  • Frequent small data exchanges instead of batched updates
  • Overuse of bridge-heavy libraries
  • Unnecessary calls between layers

These delays stack up and directly impact responsiveness, especially during complex interactions.

3. Rendering Inefficiencies at Scale

Rendering issues are one of the most common and underestimated performance problems. As components grow and the state becomes more complex, unnecessary re-renders begin to accumulate.

  • Components updating more often than needed
  • Lack of memoization strategies
  • Heavy UI elements rendering repeatedly

This leads to dropped frames, inconsistent UI smoothness, and degraded user experience.

4. Inefficient List Rendering

Lists are central to most apps – feeds, product catalogs, dashboards – but they are often poorly optimized.

  • Using ScrollView for large datasets
  • Misconfigured FlatList or SectionList
  • Missing virtualization

This results in janky scrolling, increased memory usage, and poor performance on mid-range devices.

5. Memory Leaks That Surface Over Time

Memory issues don’t usually appear during development. They show up in real usage scenarios where sessions are longer and navigation is deeper.

  • Event listeners not cleaned up
  • Timers continuing in the background
  • Retained references after component unmount

Over time, this leads to higher memory consumption, slowdowns, and even crashes.

6. Default Configurations That Don’t Scale

Many apps are shipped with default setups that work, but are not optimized.

  • Large JavaScript bundles
  • No lazy loading or code splitting
  • Unoptimized images
  • Hermes engine not fully leveraged

These don’t break functionality, but they limit how efficiently your app performs under load.

7. Lack of Performance Measurement

One of the biggest gaps is not technical; it is operational. Performance is often assumed rather than measured.

  • No consistent use of profiling tools
  • Issues identified based on perception, not data
  • Optimization efforts become reactive instead of strategic

Without visibility, even critical bottlenecks remain hidden.

What This Means for Your Business

React Native performance issues are rarely caused by a single mistake. They are the result of multiple small inefficiencies building up as your product scales.

By the time users start noticing:

  • Engagement has already dropped
  • Interactions feel slower
  • Retention begins to decline

The key takeaway: React Native is not limiting your app; unoptimized implementation is.

This becomes even more critical in scaling SaaS platforms, where performance directly impacts user retention and engagement.

React Native vs Flutter Performance Benchmarks

When performance issues start surfacing, many teams jump to a bigger question:

“Should we stick with React Native or switch to Flutter for better performance?”

It is a fair question, but often the wrong starting point.

Because in most real-world cases, the performance gap is not caused by the framework; it is caused by how the app is built, optimized, and maintained.

Let’s break this down from a decision-making perspective, not just a technical comparison.

1. Startup Time

Startup time is one of the most visible performance indicators; users feel it immediately.

  • React Native: Can have a slower startup if bundles are large or not optimized. Improves significantly with Hermes, RAM bundles, and lazy loading.
  • Flutter: Typically faster startup due to compiled native code

Reality: React Native startup time issues are usually fixable. Poor bundle strategy is the real culprit.

2. UI Performance & Animations

Smooth interactions and animations define perceived performance.

  • React Native: Depends on JS thread + bridge. Can lag if optimized. Near-native performance achievable with Reanimated and proper rendering strategies.
  • Flutter: Uses its own rendering engine (Skia). Consistent performance across devices.

Reality: React Native can match Flutter’s performance if animations are offloaded from the JS thread and rendering is optimized.

3. Memory Usage

Memory efficiency becomes critical as apps scale.

  • React Native: Higher risk of memory leaks if not managed properly. Depends heavily on developer practices.
  • Flutter: More controlled memory handling. Generally more predictable.

Reality: Most memory issues in React Native apps are implementation-driven, not framework limitations.

4. CPU Usage Under Load

When apps handle heavy data or complex interactions, CPU usage becomes a bottleneck.

  • React Native: Performance depends on JS workload and bridge usage. Can degrade if logic is not optimized.
  • Flutter: More stable under heavy UI workloads

Reality: React Native performs well when heavy computations are offloaded, and bridge usage is minimized.

5. Development Flexibility vs Performance Control

This is where the real trade-off exists.

  • React Native: Faster development cycles, strong ecosystem, easier integration with existing web teams.
  • Flutter: More control over rendering and performance. Slightly steeper learning curve for teams unfamiliar with Dart.

Reality: Most businesses choose React Native for speed, but must invest in optimization later.

So, Which One Should You Choose in 2026?

Here is the decision most teams actually need to make:

  • If your app is already built in React Native, Optimization is almost always more cost-effective than rebuilding
  • If you are starting fresh with performance-heavy requirements, Framework choice matters, but architecture matters more.

What Most Comparisons Get Wrong

The biggest misconception is this: “Flutter is faster than React Native.”

A more accurate statement would be: “A well-optimized app performs better than a poorly optimized one, regardless of framework.”

In real-world scenarios:

  • A poorly optimized React Native app will underperform
  • A poorly structured Flutter app will also face performance issues

What This Means for Your Business

Before considering a rewrite or framework switch, ask:

  • Have you optimized your JS thread usage?
  • Have you reduced unnecessary bridge calls?
  • Have you configured Hermes properly?
  • Have you addressed rendering inefficiencies and memory leaks?

If the answer is no, switching frameworks won’t solve the root problem.

React native is not inherently slower; it just requires intentional performance optimization as your app scales.

React Native Performance Optimization Checklist

At this stage, most teams do not need more theory; they need clarity on what exactly to fix, in what order, and what actually impacts performance.

That is where a structured checklist becomes critical. Instead of randomly trying optimizations, this checklist helps you:

  • Identify real bottlenecks (not assumed ones)
  • Prioritize high-impact fixes first
  • Avoid wasting time on low-impact tweaks
  • Create a repeatable optimization process as your app scales

What This Checklist Covers

This is not a generic list; it is structured around the exact areas where performance typically breaks down in production apps.

1. JavaScript Thread Optimization

  • Identify blocking operations on the JS thread
  • Reduce unnecessary re-renders
  • Optimize state updates and component structure
  • Move heavy computations off the main thread

2. Native Bridge Reduction

  • Audit JS <-> Native communication frequency
  • Batch updates instead of multiple small calls
  • Replace bridge-heavy libraries where needed
  • Use native modules strategically

3. Hermes Engine Configuration

  • Ensure Hermes is enabled correctly
  • Optimize bytecode execution
  • Reduce JavaScript bundle size
  • Validate performance improvements through profiling

4. App Startup Time Optimization

  • Implement RAM bundles or inline requires
  • Reduce initial bundle size
  • Lazy load non-critical components
  • Optimize initial screen rendering

5. Image Optimization

  • Use compressed formats like WebP
  • Avoid loading full-resolution assets unnecessarily
  • Implement caching strategies
  • Serve optimized assets via CDN

6. List Rendering Optimization

  • Use FlatList or SectionList instead of ScrollView for large data
  • Enable virtualization and windowing
  • Optimize key extraction and item rendering
  • Avoid inline functions in list items

7. High-Performance Animations

  • Move animations off the JS thread using Reanimated
  • Avoid heavy layout recalculations
  • Optimize gesture handling

8. Memory Leak Detection & Fixes

  • Clean up event listeners and subscriptions
  • Clear timers and background tasks
  • Monitor navigation stack behavior
  • Use profiling tools to detect leaks

9. Performance Profiling & Monitoring

  • Use Flipper and React DevTools
  • Analyze JS thread performance
  • Track frame drops and memory usage
  • Identify real bottlenecks before fixing

10. New Architecture (Fabric + TurboModules) Readiness

  • Evaluate migration feasibility
  • Reduce dependency on the bridge
  • Improve rendering performance with Fabric
  • Plan a phased migration strategy

Before You Start Fixing Anything

One important point most teams miss: Not every issue needs to be fixed at once.

The goal is not “perfect performance,” it is removing the biggest bottlenecks first so your app can scale without friction.

Many businesses choose to outsource app development to ensure performance optimization is handled systematically without slowing internal teams.

Request a Performance Review

JS Thread Optimization: Fix the Root Cause of Lag

If your React Native app feels slow, unresponsive, or inconsistent, the JavaScript thread is usually where the problem begins.

This is because React Native relies on a single JS thread to handle:

  • Business logic
  • State updates
  • API responses
  • UI coordination

As your app grows, this thread starts doing more than it should, and when it gets blocked, everything else slows down with it.

What Actually Blocks the JS Thread?

Most performance issues here don’t come from one major mistake. They come from small decisions that add up over time.

  • Heavy computations running during user interactions
  • Large state updates triggering multiple re-renders
  • Synchronous operations delaying UI updates
  • Complex component trees re-evaluating too frequently

The result is what users experience as:

  • Delayed taps
  • Laggy transitions
  • Dropped features

How to Optimize the JS Thread (Practically)

Instead of trying to “optimize everything,” focus on reducing unnecessary workload on the thread.

1. Eliminate Unnecessary Ren-renders

  • Use React.memo for pure components
  • Apply useMemo for expensive calculations
  • Use useCallback to stabilize function references
  • Avoid passing new inline objects/functions on every render

Impact: Reduces repeated computation and stabilizes UI performance.

2. More Heavy Work Off the JS Thread

Not all logic needs to run on the main thread.

  • Defer non-critical tasks using InteractionManager
  • Offload heavy computations to background processes
  • Avoid running large loops during active user interaction

Impact: Keeps UI responsive even under load.

3. Optimize State Management

Poor state handling increases unnecessary updates.

  • Keep the state as minimal and localized as possible
  • Avoid deeply nested state updates
  • Split large components into smaller, focused ones

Impact: Reduces render cycles and improves responsiveness.

4. Avoid Synchronous Blocking Code

Synchronous operations delay everything else.

  • Avoid long-running sync functions
  • Break tasks into smaller asynchronous chunks
  • Use debouncing or throttling where needed

Impact: Prevents UI freezes and improves perceived speed.

5. Monitor JS Thread Performance

You cannot optimize what you don’t measure.

  • Use React DevTools to track re-renders
  • Use Flipper to monitor JS performance
  • Identify frame drops and execution delays

Impact: Helps you focus only on real bottlenecks.

What Most Teams Get Wrong

Many teams try to fix performance by tweaking UI components or switching libraries, without addressing the JS thread.

That is why improvements feel temporary.

Because unless you reduce the core workload on the JavaScript thread, performance issues will keep coming back as your app scales.

What This Means for You

JS thread optimization is not a “nice-to-have”; it is foundational.

  • If your JS thread is overloaded, your UI will lag
  • If your UI lags, user experience suffers
  • If user experience suffers, engagement drops

If you fix the JS thread, you solve a large percentage of React Native performance issues at their root.

This is where many teams choose to hire React Native app developers to systematically identify and resolve performance bottlenecks.

Analyze My App Performance

Reduce Native Bridge Bottlenecks

Once the JavaScript thread is under control, the next major constraint in React Native apps is how often and how efficiently you communicate between JavaScript and native code.

React Native operates across two worlds:

  • JavaScript (logic, state, UI coordination)
  • Native (platform-specific capabilities)

The bridge connects them, but it’s not free.

Every interaction that crosses this bridge introduces overhead. When used occasionally, it is negligible. But in real-world apps, repeated and unoptimized communication starts creating measurable delays.

Why the Bridge Becomes a Bottleneck

The issue is not the existence of the bridge; it is how frequently it is used and how data is passed through it.

Performance starts degrading when:

  • Multiple small calls are made instead of batching data
  • UI updates depend on frequent back-and-forth communication
  • Third-party libraries rely heavily on bridge interactions
  • Large payloads are passed repeatedly

Individually, these don’t seem critical. But together, they create latency that affects animations, gestures, and real-time interactions.

Where This Shows Up in Real Apps

Bridge-related issues often appear in places where responsiveness matters most:

  • Animations that feel slightly delayed
  • Gestures that don’t feel fluid
  • Real-time updates that lag behind user actions
  • Screens that take longer to respond under load

These are subtle, but they directly affect how “fast” your app feels.

How to Reduce Native Bridge Overhead (Practically)

The goal is not to eliminate bridge usage; it is to use it more efficiently and intentionally.

1. Batch Data Instead of Sending Multiple Calls

Instead of triggering multiple bridge calls for small updates:

  • Combine data into a single payload.
  • Reduce frequency of communication.

Impact: Fewer bridge crossings, lower latency.

2. Avoid Bridge-Heavy Patterns in Critical Flows

Some features naturally rely more on native interactions, but not all should.

  • Minimize bridge usage in animations and gestures
  • Avoid unnecessary native calls during user interactions
  • Keep critical UI flows as lightweight as possible

Impact: Smoother, more responsive user experience.

3. Be Selective with Third-Party Libraries

Not all libraries are optimized equally.

  • Audit libraries that frequently interact with native modules
  • Replace inefficient ones where necessary
  • Prefer libraries designed for performance (e.g., Reanimated for animations)

Impact: Reduces hidden performance overhead.

4. Use Native Modules Strategically

Sometimes, moving logic closer to native can help, but only when justified.

  • Offload performance-critical operations to native code
  • Avoid unnecessary back-and-forth once logic is moved

Impact: Reduces repeated bridge communication.

5. Move Toward TurboModules (New Architecture)

Modern React Native architecture reduces dependency on the traditional bridge.

  • TroubleModules enable more efficient native interactions
  • Less serialization overhead
  • Better performance for complex apps

Impact: Long-term scalability and improved performance.

What Most Teams Miss

Many teams focus on optimizing UI components, but ignore how often their app is crossing the bridge.

That is why:

  • Animations still feel slightly off
  • Interactions don’t feel instant
  • Performance improvements plateau

Because the bottleneck isn’t available, it is happening between layers.

What This Means for You

If your app:

  • Feels slow during interactions
  • Struggles with real-time updates
  • Doesn’t feel “native smooth.”

There is a high chance that the bridge is being overused.

Reducing unnecessary bridge communication is one of the fastest ways to make your app feel more responsive, without rewriting it.

Hermes Engine Optimization Tips

If your React Native app takes too long to load or feels heavy during initial interactions, the issue often comes down to how JavaScript is executed, and that is exactly where the Hermes engine makes a difference.

Hermes is not just a toggle you enable. It is a performance layer that, when configured properly, can significantly improve:

  • App startup time
  • Memory usage
  • Overall execution efficiency

But simply enabling Hermes is not enough. Most apps don’t fully benefit from it because the surrounding setup remains unoptimized.

Why Hermes Matters for Performance

By default, JavaScript needs to be parsed and compiled at runtime, which adds overhead, especially during app launch.

Hermes changes this by:

  • Precompiling JavaScript into bytecode
  • Reducing runtime parsing work
  • Lowering memory consumption

This directly improves time-to-interactive, which is one of the most critical performance metrics for user experience.

Where Hermes Delivers the Most Impact

You will notice the biggest improvements in:

  • Faster app startup and screen load
  • Reduced memory footprint on mid-range devices
  • More consistent performance during initial interactions

However, these benefits only show up when your app’s bundle and execution flow are optimized alongside Hermes.

How to Optimize Hermes for Real Performance Gains

1. Ensure Hermes is Properly Enabled (Production Build)

Many teams enable Hermes but don’t validate its impact.

  • Confirm Hermes is active in release builds (Android & iOS)
  • Compare performance metrics before and after enabling
  • Avoid relying only on development mode behavior

Impact: Establishes a baseline for real-world performance gains.

2. Reduce JavaScript Bundle Size

Hermes performs best when the bundle is lean.

  • Remove unused dependencies
  • Enable tree shaking
  • Split large modules where possible
  • Avoid bundling unnecessary assets

Impact: Smaller bytecode = faster startup and lower memory usage.

3. Use Inline Requires & Lazy Loading

Loading everything upfront slows down startup, even with Hermes.

  • Enable inline requires to defer module loading
  • Lazy load non-critical screens and components
  • Prioritize only what’s needed for the first screen

Impact: Improves initial render time and perceived speed.

4. Optimize Third-Party Dependencies

Some libraries inflate bundle size or slow execution.

  • Audit dependencies regularly
  • Replace heavy or unused libraries
  • Prefer lightweight, performance-focused alternatives

Impact: Reduces overhead that negates Hermes benefits.

5. Profile Hermes Performance

Don’t assume improvements, measure them.

  • Use Flipper with Hermes debugging enabled
  • Analyze startup time and memory usage
  • Identify bottlenecks in execution flow

Impact: Helps you validate and fine-tune optimizations.

What Most Teams Get Wrong

They enable Hermes and expect instant results.

But if:

  • Your bundle is still large
  • Your app loads everything upfront
  • Your dependencies are unoptimized

Then Hermes cannot deliver its full value.
What This Means for Your App

Hermes is one of the highest ROI performance optimizations in React Native, but only when paired with the right strategies.

  • It improves startup time
  • Reduces memory usage
  • Makes execution more efficient

But it does not fix poor architecture on its own.

Hermes is a performance accelerator, not a shortcut. To get real gains, you need to optimize what runs on top of it.

React Native App Startup Time Optimization

Startup time is one of the few performance metrics users notice immediately and judge instantly.

If your app takes too long to become interactive, users don’t wait to understand why. They drop off, retry less often, and form a perception that your app is unreliable or heavy.

The challenge is that startup delays are rarely caused by a single issue. Them come from everything your app tries to load and execute at once.

What Slows Down App Startup?

In most React Native apps, startup time increases due to:

  • Large JavaScript bundles being loaded upfront
  • Too many modules initialized on launch
  • Heavy API calls triggered immediately
  • Complex initial screen rendering
  • Assets (images, fonts) loading synchronously

Even if each of these seems manageable individually, together they delay the moment when your app becomes usable.

How to Optimize Startup Time (Practically)

The goal is simple: load only what’s necessary to get the first screen interactive, nothing more.

1. Reduce Initial Bundle Size

The more code your app loads at startup, the slower it becomes.

  • Remove unused dependencies
  • Split large modules into smaller chunks
  • Avoid building non-critical features upfront

Impact: Faster load time and reduced processing overhead.

2. Use Inline Requires & Lazy Loading

Not everything needs to be loaded on app launch.

  • Enable inline requires to defer module loading
  • Lazy load secondary screens and features
  • Delay non-essential logic until after initial render

Impact: Faster time-to-interactive and smoother first experience.

3. Optimize the Initial Screen

Your first screen defines perceived performance.

  • Keep UI lightweight and minimal
  • Avoid complex layouts or heavy components
  • Defer non-critical rendering

Impact: Users feel the app is fast, even if background tasks continue.

4. Defer API Calls and Background Work

Many apps overload the startup with unnecessary network activity.

  • Prioritize only essential API calls
  • Defer secondary data fetching
  • Use background loading strategies

Impact: Reduces startup blocking and improves responsiveness.

5. Optimize Assets (Images, Fonts, Media)

Assets often delay rendering more than expected.

  • Use compressed formats like WebP
  • Avoid loading high-resolution assets at startup
  • Preload only critical assets

Impact: Faster rendering and lower memory usage.

6. Leverage Hermes + RAM Bundles Together

Startup optimization works best when combined with execution improvements.

  • Use Hermes for faster JS execution
  • Implement RAM bundles or segmented loading
  • Ensure only the required code is initialized

Impact: Significant improvement in startup speed and efficiency.

What Most Teams Miss

They try to make everything load faster, instead of making less load initially.

That is the real shift:

  • It is not just optimization
  • It is prioritization

What This Means for Your Business

Startup time directly impacts first impressions, user retention, and conversion rates.

Even a small delay can reduce engagement, especially on mobile networks and mid-range devices.

The fastest apps are not the ones that load everything quickly; they are the ones that load only what’s necessary first.

Image Optimization in React Native Apps

Images are one of the biggest contributors to performance issues, yet they’re often overlooked because they don’t “break” the app. They quietly slow it down.

If your app includes product catalogs, feeds, banners, or user-generated content, image handling directly affects:

  • Load time
  • Scroll performance
  • Memory usage

And unlike code-level optimizations, image inefficiencies scale aggressively as your content grows.

What Goes Wrong with Images

Most React Native apps don’t have an image problem; they have an image handling problem.

Common issues include:

  • Loading high-resolution images unnecessarily
  • No compression or improper formats
  • Rendering full-size images in smaller containers
  • Re-fetching images without caching
  • Blocking UI while images load

These don’t always show up in testing, but in real usage, they create visible lag and increased memory pressure.

Where Image Issues Impact Performance the Most

You’ll notice performance drops, especially in:

  • Product or content-heavy screens
  • Infinite scroll feeds
  • Image-rich dashboards
  • Slower networks or mid-range devices

This is where users start experiencing:

  • Delayed rendering
  • Janky scrolling
  • Increased load times

How to Optimize Images (Practically)

The goal is simple: load the right image, at the right size, at the right time.

1. Use Modern, Compressed Image Formats

Not all formats are equal.

  • Prefer WebP over PNG/JPEG where supported
  • Compress images before serving
  • Balance quality vs size

Impact: Reduces file size significantly without noticeable quality loss.

2. Serve Appropriately Sized Images

Avoid rendering oversized images.

  • Match image resolution to display size
  • Use multiple variants (small, medium, large)
  • Avoid scaling large images down on the device

Impact: Lower memory usage and faster rendering.

3. Implement Image Caching

Repeated downloads slow down performance.

  • Use caching libraries like react-native-fast-image
  • Cache frequently used images
  • Leverage CDN caching headers

Impact: Faster repeat loads and reduced network usage.

4. Use Lazy Loading for Off-Screen Images

Loading everything at once hurts performance.

  • Load images only when they enter the viewport
  • Defer non-visible assets
  • Combine with list virtualization

Impact: Improves initial load time and scrolling smoothness.

5. Optimize Image Rendering in Lists

Lists amplify image inefficiencies.

  • Avoid re-rendering images unnecessarily
  • Use stable keys and memoization
  • Combine with optimized FlatList settings

Impact: Smooth scrolling and better performance on large datasets.

6. Use a CDN for Image Delivery

Serving images efficiently matters as much as optimizing them.

  • Use a CDN to reduce latency
  • Deliver images based on device and network conditions
  • Enable compression at the delivery level

Impact: Faster load times across geographies and devices.

What Most Teams Get Wrong

They treat image optimization as a design or frontend concern, not a performance strategy.

So:

  • Images are added without compression
  • Formats are not standardized
  • Caching is ignored

And performance gradually degrades as content grows.

What This Means for Your App

If your app relies heavily on visuals, image optimization isn’t optional; it’s foundational.

  • It affects speed
  • It affects memory
  • It affects user experience directly

Optimizing images is one of the quickest ways to improve real-world performance, especially in content-heavy apps.

FlatList vs SectionList vs ScrollView: Choosing the Right Rendering Strategy

If your app involves lists, and most apps do, your rendering strategy directly impacts performance.

This is where many React Native apps unknowingly introduce lag. Not because lists are complex, but because the wrong component is used for the wrong use case.

At a small scale, everything works. At a large scale, the difference becomes obvious, especially in scrolling performance and memory usage.

Why List Rendering Becomes a Bottleneck

Rendering a list is not just about displaying data; it is about how much of that data is loaded and rendered at any given time.

Performance issues typically arise when:

  • Too many items are rendered at once
  • Off-screen items are still consuming memory
  • Re-renders are not controlled

This leads to:

  • Janky scrolling
  • Increased memory usage
  • UI freezes on lower-end devices

ScrollView: Simple, But Not Scalable

ScrollView renders everything at once.

It works well for:

  • Small, static content
  • Limited number of elements

But becomes a problem when:

  • This list grows large
  • Content is dynamic or frequently updated

Impact: High memory usage and poor scroll performance.

FlatList: The Default for Large Lists

FlatList is designed for performance through virtualization.

Instead of rendering everything, it:

  • Renders only visible items
  • Recycles off-screen components
  • Manages memory efficiently

Best used for:

  • Long, uniform lists (feeds, product lists)
  • Infinite scrolling

Impact: Smooth scrolling and better performance at scale.

SectionList: Structured Lists with Performance

SectionList builds on FlatList but adds grouping.

Best used for:

  • Categorized data (eg., grouped products, messages by date)
  • Section headers and structured layouts

Impact: Maintains performance while supporting complex data structures.

How to Optimize List Performance (Practically)

Choosing the right component is step one. Configuring it properly is where real gains come from.

1. Enable and Tune Virtualization

  • Use initialNumToRender wisely
  • Adjust windowSize based on use case
  • Avoid rendering too many items upfront

Impact: Controls memory usage and improves scroll smoothness.

2. Optimize Item Rendering

  • Use React.memo for list items
  • Avoid inline functions inside render
  • Use stable keyExtractor

Impact: Reduces unnecessary re-renders.

3. Use getItemLayout for Predictable Lists

If item sizes are fixed:

  • Implement getItemLayout
  • Avoid runtime layout calculations

Impact: Faster scroll performance and reduced computation.

4. Avoid Heavy Components Inside Lists

  • Keep list items lightweight
  • Defer complex UI elements
  • Lazy load images inside items

Impact: Improves rendering speed and responsiveness.

5. Combine with Image & State Optimization

Lists amplify inefficiencies.

  • Optimize images used in list items
  • Prevent unnecessary state updates
  • Avoid re-rendering the entire list on small changes

Impact: Stable performance even with large datasets.

What Most Teams Miss

They switch from ScrollView or FlatList and expect performance to be solved. But poor configuration, heavy list items, and unoptimized rendering can still cause performance issues.

What This Means for Your App

If your app relies on lists:

  • Your rendering strategy directly affects user experience
  • Small inefficiencies scale quickly
  • Optimization here delivers immediate visible improvements

Choosing the right list components is important, but configuring and optimizing it properly is what actually improves performance.

Using Reanimated for High-Performance Animations

Animations are where users feel performance the most.

Your app might load fast and function correctly, but if animations are laggy, delayed, or inconsistent, the entire experience feels slow. This is especially true for gestures, transitions, and interactive UI elements.

The root issue in most React Native app is: “Default animations often depend on the JavaScript thread.”

And as you have already seen, the JS thread is easily overloaded.

Why Default Animations Start Lagging

When animations rely on the JS thread:

  • They compete with business logic and state updates
  • Frame updates get delayed when the thread is busy
  • Gestures feel unresponsive under load

This leads to:

  • Dropped frames
  • Stuttering transitions
  • Delayed feedback on interactions

Even small delays here significantly impact perceived performance.

How Reanimated Solves This

Reanimated works differently.

Instead of relying on the JS thread, it runs animations directly on the UI thread, which means:

  • Animations continue smoothly even if JS is busy
  • Gestures respond instantly
  • Frame consistency improves significantly

This makes a noticeable difference in real-world usage, especially in complex or highly interactive apps.

Where Reanimated Delivers the Most Value

You will see the biggest improvements in:

  • Gesture-based interactions (swipes, drag-and-drop)
  • Navigation transitions
  • Micro-interactions (buttons, toggles, loaders)
  • Scroll-linked animations

These are areas where even slight lag is immediately noticeable to users.

How to Use Reanimated Effectively

Switching to Reanimated alone is not enough, you need to use it strategically.

1. More Critical Animations Off the JS Thread

  • Use Reanimated for gesture-driven interactions
  • Avoid JS-based animations in high frequency UI updates
  • Keep animation logic close to the UI layer

Impact: Smooth, consistent animations even under load.

2. Optimize Animation Logic

  • Avoid overly complex animation calculations
  • Keep transitions lightweight
  • Use shared values efficiently

Impact: Reduces computation overhead on the UI thread.

3. Integrate with Gesture Handler

Reanimated works best when combined with gesture handling libraries.

  • Use react-native-gesture-handler
  • Handle gestures and animations together
  • Avoid unnecessary re-renders during interactions

Impact: Seamless and responsive user interactions.

4. Avoid Mixing Animation Approaches

Using multiple animation systems creates inconsistency.

  • Standardize on Reanimated for performance-critical flows
  • Avoid mixing with legacy animation APIs unnecessarily

Impact: Predictable and stable animation performance.

What Most Teams Get Wrong

They optimize logic and rendering, but leave animations untouched.

So even after improvements:

  • The app still feels slow
  • Interactions don’t feel fluid
  • Users perceive lag where none technically exists

Because perception is driven by motion.

What This Means for Your App

If your app relies on gestures, has frequent transitions, or includes interactive UI elements, then animation performance is not optional; it is central to user experience.

If you want your app to feel truly fast, your animations need to run independently of the JS thread, and that is exactly what Reanimated enables.

React Native Memory Leak Detection and Fix Guide

Some performance issues are immediate – lag, slow startup, janky scrolling. Memory leaks are different. They build quietly and only show up when users spend more time in your app.

That is why they are dangerous.

An app can feel fine during testing, but in real-world usage:

  • Sessions are longer
  • Navigation is deeper
  • More components mount and unmount

And if memory is not managed properly, it keeps increasing until performance drops or the app crashes.

What Causes Memory Leaks in React Native

Most memory leaks don’t come from complex logic. They come from missed cleanups and retained references.

Common issues include:

  • Event listeners that are not removed after component unmount
  • Timers (setTimeout, setInterval) continuing in the background
  • API subscriptions or sockets not being closed
  • Navigation stacks keeping unused screens in memory
  • Large objects or images not being released

Individually, these seem harmless. Over time, they accumulate.

How Memory Leaks Impact Your App

Unlike visible bugs, memory leaks degrade performance gradually:

  • Increased memory usage over time
  • Slower navigation and screen transitions
  • App freezing on lower-end devices
  • Sudden crashes after prolonged usage

This directly affects retention, especially for users who stay longer or return frequently.

How to Detect Memory Leaks (Practically)

You can’t fix what you can’t see. Detection is the first step.

1. Use Flipper for Memory Monitoring

  • Track memory usage over time
  • Identify components that don’t release memory
  • Monitor leaks during navigation

Impact: Helps pinpoint where memory is accumulating.

2. Use Xcode Instruments (iOS) / Android Profiler

  • Analyze heap allocations
  • Detect retained objects
  • Identify abnormal memory growth patterns

Impact: Deep visibility into memory behavior at runtime.

3. Test Real Usage Scenarios

  • Navigate across multiple screens repeatedly
  • Keep the app running for extended sessions
  • Simulate real user flows

Impact: Reveals leaks that don’t appear in short test cycles.

How to Fix Memory Leaks

Once identified, fixes are usually straightforward, but require discipline.

1. Clean Up Event Listeners

  • Remove listeners in cleanup functions (useEffect return)
  • Avoid multiple subscriptions without cleanup

Impact: Prevents unnecessary memory retention.

2. Clear Timers and Background Tasks

  • Always clear setTimeout and setInterval
  • Stop background processes when not needed

Impact: Frees up memory and reduces CPU usage.

3. Manage Subscriptions and API Calls

  • Cancel ongoing requests when components unmount
  • Close WebSocket or real-time connections properly

Impact: Prevents orphan processes consuming memory.

4. Optimize Navigation Behavior

  • Avoid keeping unnecessary screens mounted
  • Use proper navigation stack management

Impact: Reduces memory buildup across screens.

5. Avoid Retaining Large Objects

  • Release references to unused data
  • Optimize image handling and caching

Impact: Keeps memory footprint stable.

What Most Teams Miss

They optimize visible performance issues, but ignore what happens over time.

So:

  • The app performs well initially
  • But degrades during longer sessions
  • And eventually crashes under real usage

Because memory leaks don’t show up immediately, they accumulate silently.

What This Means for Your App

If your app:

  • Slows down after prolonged use
  • Crashes without clear errors
  • Performs inconsistently across sessions

There’s a strong chance memory leaks are involved.

Fixing memory leaks isn’t just about stability; it’s about maintaining consistent performance as users engage more deeply with your app.

Profiling & Debugging Tools You Should Be Using

At this point, you have seen where performance issues come from and how to fix them.

But here is where most teams still go wrong:

They optimize based on assumptions.

They “feel” the app is slow, try a few fixes, see minor improvements and stop there. The problem is, without proper profiling, you are not solving the root issue. You are just reaching to symptoms.

Performance optimization only becomes effective when it is measured, not guessed.

Why Profiling Changes Everything

Without profiling:

  • You don’t know what is actually slow
  • You may fix low-impact issues first
  • Critical bottlenecks remain uptouched.

With profiling:

  • You identify exactly where time and memory are being consumed
  • You prioritize fixes based on impact
  • You avoid unnecessary rework

That is what separated random optimization from systematic performance improvement.

Key Tools You Should Be Using

You do not need dozens of tools, just the right ones used consistently.

1. Flipper (All-in-One Debugging Tool)

Flipper is one of the most practical tools for React Native performance analysis.

  • Monitor JS thread performance
  • Track network requests
  • Analyze memory usage
  • Inspect logs and app behavior

Best For: Getting a consolidated view of app performance in real time.

2. React DevTools (Render Analysis)

  • Identify unnecessary re-renders
  • Analyze component updates
  • Track state and prop changes

Best for: Fixing rendering-related performance issues.

3. Performance Monitor (Built-in RN Tool)

A quick way to check real-time performance inside your app.

  • Monitor FPS (frames per second)
  • Track JS thread activity
  • Identify frame drops

Best for: Spotting immediate performance issues during interaction.

4. Xcode Instruments (iOS) / Android Profiler)

For deeper, system-level analysis:

  • Track CPU usage
  • Analyze memory allocation
  • Detect leaks and spikes

Best for: Diagnosing complex performance and memory issues.

5. Systrace (Advanced Performance Tracking)

Useful for understanding low-level performance behavior.

  • Analyze thread activity
  • Identify bottlenecks in execution flow
  • Track system-level delays

Best for: Advanced debugging in high-performance or complex apps.

How to Use Profiling Effectively

Using tools is one thing, using them correctly is what matters.

Start with a Clear Scenario

  • Test specific user flows (eg., app launch, scrolling, navigation)
  • Avoid random exploration

Identify the Bottleneck First

  • Is it JS thread overhead?
  • Rendering inefficiency?
  • Memory growth?
  • Network delay?

Prioritize High-Impact Fixes

  • Focus on issues affecting user experience directly
  • Ignore micro-optimizations initially

Measure Before and After

  • Validate improvement after every change
  • Avoid stacking multiple fixes without tracking impact

What Most Teams Get Wrong

They treat profiling as optional. So:

  • Performance issues are misdiagnosed
  • Fixes are inconsistent
  • Time is wasted on low-impact improvements

What This Means for Your App

If you are not profiling:

  • You are guessing
  • You are likely fixing the wrong problems first
  • You are leaving performance gains on the table

Profiling turns performance optimization from trial-and-error into a repeatable, data-driven process.

Combining profiling with consistent software testing ensures performance issues are identified early and resolved before impacting users.

React Native New Architecture (Fabric + TurboModules) Migration Guide

If you have already optimized your app and still see performance limits, the next step is not another tweak; it is architecture.

React Native’s New Architecture (Fabric + TurboModules) is designed to solve some of the core limitations of the traditional setup, especially around the bridge and rendering pipeline.

But here is the important part: This is not a mandatory upgrade for every app. It is a strategic decision.

What is Changing in the New Architecture?

The traditional React Native model relies heavily on the bridge for communication between JavaScript and native layers.

The New Architecture reduces that dependency and introduces a more efficient system:

  • Fabric improves how UI is rendered
  • TurboModules optimize how native modules are accessed
  • JSI (JavaScript Interface) enables more direct communication without heavy serialization

Together, these changes aim to make React Native faster, more predictable, and more scalable.

Where You Will See the Biggest Performance Gains

The new architecture does not magically fix everything, but it significantly improves performance in areas like:

  • Faster and more consistent rendering
  • Reduced latency in JS <-> Native Communication
  • Better handling of complex UI updates
  • Improved performance in animation-heavy or interactive apps.

This is especially useful for apps that:

  • Have high user interaction
  • Rely heavily on animations and gestures
  • Experience performance limits even after optimization

When Should You Consider Migrating?

Migration makes sense when:

  • You have already optimized JS thread, rendering, and memory usage
  • Bridge communication is still a bottleneck
  • You app is scaling in complexity
  • You need long-term performance stability

It may not be necessary if:

  • Your current performance is already stable
  • Your app is relatively simple
  • You haven’t yet optimized existing architecture

What Makes Migration Challenging

This is where most teams hesitate, and rightly so.

  • Not all third-party libraries are fully compatible
  • Migration requires testing across the entire app
  • Partial adoption can create inconsistencies
  • Development effort can be significant

That is why this is not just a technical upgrade; it is a planning exercise.

How to Approach Migration Strategically

1. Start with an Audit

  • Identify current performance bottlenecks
  • Confirm if they are architecture-related
  • Avoid migrating without a clear reason

2. Check Library Compatibility

  • Audit all dependencies
  • Replace unsupported libraries if needed
  • Avoid surprises during migration

3. Plan a Phased Rollout

  • Start with non-critical modules
  • Gradually migrate features
  • Monitor performance improvements at each step

4. Combine with Existing Optimizations

Migration works best when paired with:

  • JS thread optimization
  • Reduced bridge usage
  • Efficient rendering patterns

What Most Teams Get Wrong

They see the New Architecture as a quick fix.

So they:

  • Attempt migration too early
  • Skip optimization fundamentals
  • Underestimate implementation complexity

And end up with:

  • Increased development effort
  • Minimal performance gains

What This Means for Your Business

Migrating to Fabric and TurboModules is not about chasing trends; it’s about removing structural limitations when your app outgrows its current setup.

The New Architecture is a powerful upgrade, but only when your app is ready for it and your decision is based on real performance needs.

Talk to a Performance Expert

When to Optimize vs When to Rebuild

At some point, every team working on a growing React Native app faces this question:

“Should we keep optimizing, or is it time to rebuild?”

It is not just a technical decision. It is a business decision involving cost, timelines, risk, and long-term scalability.

The mistake most teams make is choosing too early or too late.

Why This Decision Gets Misjudged

Performance issues create urgency. Lag, crashes, or poor user experience push teams toward drastic decisions like rewriting the app or switching frameworks. But in reality:

  • Many apps are rebuilt when optimization was enough
  • Others are over-optimized when architectural limits already exist

The key is knowing where your app actually stands.

When Optimization is the Right Move

In most cases, optimization should be your first approach, especially if the foundation is still solid.

You should continue optimizing if:

  • Performance issues are linked to JS thread overload, rendering, or memory leaks
  • Startup time is high due to bundle size or asset loading
  • Lists, images, or animations are not optimized
  • Profiling shows clear, fixable bottlenecks

In these scenarios, applying the checklist you have seen can lead to significant improvements without major redevelopment costs.

When Rebuilding (or Major Refactoring) Makes Sense

Optimization has limits, especially when the core architecture becomes a constraint.

You should consider rebuilding or restructuring if:

  • Performance issues persist even after thorough optimization
  • Bridge communication remains a major bottleneck
  • The app architecture is not aligned with scaling needs
  • Technical debt is slowing down development and releases
  • You’re planning major feature expansions that current setup can’t support efficiently

In such cases, continuing to optimize can become more expensive than restructuring.

Cost vs Impact: The Real Trade-Off

This decision isn’t about “what’s better”, it’s about what delivers the best return.

  • Optimization → Lower cost, faster results, minimal disruption
  • Rebuild → Higher cost, longer timelines, but cleaner long-term foundation

The right choice depends on:

  • Current performance state
  • Business priorities
  • Growth plans

A Practical Decision Framework

Before deciding, ask:

  • Have we identified real bottlenecks using profiling tools?
  • Have we optimized JS thread, rendering, and memory usage?
  • Are performance issues still limiting user experience after fixes?
  • Is our current architecture blocking future scalability?

If most answers point to fixable issues → optimize. If they point to structural limitations → consider rebuilding.

What Most Teams Get Wrong

They treat rebuilding as a performance solution.

But:

  • A new app with poor practices will face the same issues again
  • Rebuilding doesn’t eliminate the need for optimization, it resets it

What This Means for Your Business

Choosing correctly here impacts:

  • Development cost
  • Time to market
  • Product stability
  • Future scalability

Optimize when the foundation is strong. Rebuild when the foundation is limiting growth.

Conclusion: Should You Optimize Now or Wait Until It Gets Worse?

If your app is already showing signs of lag, slow startup, or inconsistent performance, waiting will only make the problem harder, and more expensive, to fix.

The right approach isn’t to overhaul everything overnight. It’s to identify bottlenecks, fix what matters most, and build a system that keeps performance stable as you scale.

Because performance isn’t just about speed, it’s about:

  • Retaining users
  • Improving engagement
  • Supporting growth without friction

And in most cases, the difference between a struggling app and a scalable one comes down to how early and how systematically you address performance.

Optimize My App Performance

How to Write a Software Development RFP That Gets Serious Attentions

Introduction

Most companies do not lose a good vendor because of budget. They lost them because the RFP wasn’t clear enough to take seriously.

Writing a request for proposal for software development sounds straightforward. You list what you need, set a deadline, and wait for a proposal to come in. But if you have done this before, you know it rarely works that way.

The software product development service is the one with a strong track record and is picky about which RFPs they respond to. A vague document, rushed, or missing basic details like a budget range? They will skip it. The ones who respond to anything are usually not the ones you want.

This guide walks you through how to write an RFP that earns real responses from vendors who actually want to work with you.

What Is an RFP in Software Development?

A request for proposal for software development is a document you send to vendors when you want them to pitch for your project. It tells them what you are building, what you need, your timeline, and how you will decide who wins the work.

Think of it as a structured RFP software development template that gives vendors everything they need. A good one gives vendors everything they need to come back with a relevant and realistic proposal. A poor one leaves them guessing, and experienced vendors don’t guess. They will just move on.

RFP vs RFI vs RFQ: Which One Do You Need?

People mix these up all the time. Here is a simple breakdown:

Most Common

RFP

You know the problem. You want vendors to propose how they’d solve it and at what cost.

Early Research

RFI

You are still figuring things out. You want to understand what’s possible before committing.

Price Comparison

RFQ

Scope is fully defined. You just need price quotes. Rare for custom software.

For most software projects, an RFP is the right tool. If you are still figuring out what you need, start with an RFI or a scoping conversation first.

Do You Actually Need a Formal RFP?

Not always. An RFP takes time to write and time for vendors to respond. If your project scope is small and your requirements are still forming, then a direct conversation with one or two agencies is often faster and just as effective.

Here is a quick way to decide:

Use an RFP whenSkip the RFP when
Budget is above $65kBudget is under $35K
You are comparing 3 or more vendorsYou already have a trusted vendor in mind
Multiple stakeholders need sign-offRequirements are still being defined
There are compliance or audit requirementsSpeed is the main priority
The project involves complex integrationsYou just need a quick scoping call

Talk to us about project scoping

What Vendors Actually Want to See in Your RFP?

Most guides about how to write a software development RFP are written from the buyer’s side. But it should actually cover what vendors actually look for when they are deciding whether to respond or not.

Before you read a single requirement, here are the three things that you must need to check:

  • Is there a budget range? Even a rough one?
  • Is there a real deadline and a named decision-maker?
  • Does the document show the client knows what they want?

If any of those are missing, many good agencies will either skip it or send a vague response just to keep their options open. Neither outcome is useful for you.

What Makes a Vendor Take Your RFP Seriously?

Here is the table so that you can have more clarity:

What to includeWhy it matters to vendors
A budget rangeTells vendors if the project is financially viable before they invest time in a proposal.
The business problem you’re solvingHelps them propose the right solution, not just tick a feature list.
Your existing tech stackFlags integration challenges or constraints upfront.
What’s out of scopePrevents misunderstandings that escalate during delivery.
How and when you’ll decideShows a real decision process and that responding is worth their effort.
A named decision-makerSignals internal alignment and clear ownership.

Things That Make Good Vendors Walk Away

  • No budget range at all, it gives the signal of internal misalignment, not a negotiation strategy.
  • Asking for the free architecture design as part of the proposal.
  • A 40-page spec with no business context behind the requirements.
  • 10 stakeholders listed as “decision-maker” with no one named as the owner.
  • Timelines that are clearly too tight to be realistic.
Worth Remembering

Your document tells vendors what working with you will be like. A clear, honest, well-structured RFP signals that you are an organized client. That alone can put you ahead of other projects competing for the same team’s time.

Before You Write: 4 Things to Sort Out Internally First

The number one reason RFPs fail is not just the document; it is the teams that start writing before they are actually ready. Sort these out first, and everything else becomes much easier.

Get everyone aligned internally

Your CTO, Head of Product, and whoever controls the budget all need to agree on what this project is before vendors hear about it. If they don’t, your RFP will be inconsistent, and the vendor will notice.

Focus on the problem, not just the solution

Instead of writing, “we need a customer portal with these 12 features,” write “customers are dropping off at onboarding because there’s no self-serve option.” Vendors can suggest better solutions when they understand the real problem.

Get a budget range approved before you write anything

You do not need an exact number. A range like $50k-$150K is enough. Without it, you will spend weeks reviewing proposals you can’t actually move forward on.

Assign one person to own the process

Someone needs to manage vendor questions, coordinate internal feedback, and drive the decision forward. Without a named owner, RFPs sometimes stall for months.

The 10 Sections Every Software Development RFP Must Include

A good request for proposal for software development does not have to be long. But it does need to cover these 10 areas: use this in your RFP template software development team follow before going to market.

Skipping the one, you will either get widely different proposals that are impossible to compare or end up with disputes after the contract is signed.

The 10 sections are:

1. Company and Project Overview

Who you are, what you do, and why this project is happening now. Keep it short; vendors want context, not company history.

2. Scope of Work and Functional Requirements

What the product needs to do along with software consulting and project scoping. Separate must-haves from nice-to-haves. Describe what you want to achieve, not just what you want built.

3. Technical Requirements and Preferred Stack

Existing systems, preferred tech, APIs, and security requirements. Be upfront about legacy system surprises; mid-project costs money.

4. UI/UX Expectations and Design Standards

Brand guidelines, design system, accessibility needs, and examples you like. Most RFPs skip this. Then spend months arguing about design after the contract is signed.

5. Budget Range and Engagement Model

A realistic range and whether you prefer a fixed price, time, and materials of a dedicated team. This is the most important section. Most buyers leave it blank. “Don’t.”

6. Timeline and Key Milestones

When you want to start, key delivery dates, and any hard deadlines. Flag which dates are fixed and which are flexible.

7. Vendor Qualification Criteria

What vendors need to qualify: experience level, team size, industry background, and location. This filters out unsuitable responses before they reach you.

8. Proposal Format and Submission Deadline

How vendors should structure their response, what to include, and the hard deadline. The clearer this is, the easier your evaluation will be.

9. Evaluation Criteria and How You’ll Decide

What you have scoring on, such as technical approach, experience, price, and team. Being transparent here usually improves proposal quality significantly.

10. Post-Launch Support and Maintenance

What happens after go-live? Bugs, documentation, handover, and SLAs and handover terms belong in your RFS software development template, not in a contract negotiation 6 months later. Leaving this out is the most common cause of the post-launch dispute.

Most Skipped Section

UI/UX and Post-Launch Support are missing from most of the RFPs you see. Both are common causes of expensive disagreements later. Adding them takes 30 minutes and saves weeks of back-and-forth work.

Need help with the technical side? See how we approach software product development

Should You Share Your Budget Upfront?

Yes. Almost every time.

We know the hesitation, it feels like you are giving your negotiation positions before talks even start. But in practice, hiding your budget causes more problems than it solves.

What Actually Happens When There’s No Budget in the RFP

  • Some vendors over-engineer to impress and come back way over budget.
  • Others are underscoped to look cheap and leave out half of what you need.
  • You spend weeks reviewing proposals that were never realistic.
  • You end up starting the whole process again once reality sets in.

How to Share Your Budget Without Losing Your Edge

Use a range, not a fixed number. Something like “we have a budget in the range $100k–$160k for the initial build” is honest, useful, and still leaves room for discussion. Pair it with your preferred engagement model, and vendors can structure their proposal properly.

Engagement ModelsBest Suited ForMain Trade-Off
Fixed PriceWell-defined scope with clear deliverablesLess flexibility if the scope changes
Time & MaterialsEvolving requirements or agile projectsRequires active oversight on your side
Dedicated TeamLong-term builds or ongoing product developmentHigher upfront cost, but deep alignment

On Timelines

Don’t fake urgency you do not have. “Targeting go-live before Q4, but start date is flexible” is far more useful to the vendor than “ASAP,” which just reads as “we have not aligned internally yet.”

Mistakes That Cost You Good Vendor Responses

These are not edge cases. These are patterns that appear in most of the RFPs that come back with poor responses, no response, or proposals that do not hold up once the project actually starts.

  • Writing a solution instead of a problem

When you prescribe every feature and every screen upfront, vendors cannot suggest a better approach. The best team wants to understand your goals first, then figure out the smartest way to get there. Give them that room.

  • Sending the RFP before internal alignment is done

If the management disagrees on what you are building, that confusion will be reflected in the documents. Vendors will either price in the uncertainty as risk or quietly move on to a client who’s clearer on what they want.

  • Setting a timeline that is not realistic

An aggressive deadline does not signal urgency to experienced vendors. It signals that something has already gone wrong internally, or that the client has not fully thought through what the build actually requires. Both situations lead to inflated quotes.

  • Not explaining how you will make the final decision

Vendors invest real-time in proposals. If they do not know who makes the call, how proposals are scored, or when they will hear back, the best agencies will question whether the effort is worth it. Transparency here builds trust and improves response quality.

  • Leaving post-launch as “something we’ll discuss later”

Support, documentation, handover, and SLAs belong in the RFP software development template and not in a contract negotiation six months down the line. Leaving this section empty does not delay the conversation. It just makes it harder when it eventually comes up.

Each of these mistakes is avoidable with a solid RFP software development template in place before you start writing.

How to Evaluate a Proposal and Pick the Right Vendor

Once the proposals are in, the risk shifts. Now the danger is picking the wrong vendor for the wrong reason, because usually the most polished document wins over the most capable team.

Score Proposal Before You Read Them

Decide your evaluation criteria and their weightings before opening a single response. If you read them first and then build a headline, you will carelessly design it around your favourite.

A simple scoring table helps you avoid that bias entirely.

CriteriaSuggested WeightWhat to Look For
Technical Approach30%Did they understand the real problem or just repeat your requirements?
Relevant Experience25%Similar projects with verifiable references, not just client logos.
Commercial Fit20%Is the pricing clearly explained and realistic for the scope?
Team Composition15%Named individuals with relevant experience, not generic roles.
Communication Quality10%How they handled questions during the RFP process itself.

Questions Worth Asking Every Shortlisted Vendor

  • Walk us through how you would handle a significant scope change three months in; this reveals more than any proposal.
  • Who specifically will work on this day-to-day, not just who presents it to us today?
  • Can you share a reference from a project that ran into problems, and how you resolved it?
  • What does your handover process look like at the end of the project?

Considering a dedicated team model? See how WEDOWEBAPPS structures a dedicated development team

Before You Send Your RFP: A Quick Checklist

Use this check list for your RFP template software development. If you cannot check every box, fix it first; the ones you skip are usually the ones that come back to cause problems.

Internal Alignment

  • One named person owns the RFP process and the final decision.
  • The budget range is approved internally and included in the document.
  • All key stakeholders have reviewed and agreed on the scope.
  • You know whether you need a fixed price, time and materials, or a dedicated team.

The Document Itself

  • The company background and project context are clear and concise.
  • You have described the business problem, not just the feature list.
  • Must-haves and nice-to-haves are clearly separated.
  • Existing tech stack and integrations are documented.
  • UI/UX expectations and any brand guidelines are included.
  • Budget range is stated, even though it is approximate.
  • Timeline included which dates are fixed and which are flexible.
  • Post-launch support expectations are clearly defined.

Vendor Process

  • The submission deadline is clearly stated.
  • Proposal format is specified so responses are easy to compare.
  • Evaluation criteria and weightings are included.
  • You have a named point of contact for vendor questions.

If you are missing more than 3 of these, the RFP is not ready to go out yet. A week spent fixing the document now will save weeks of back-and-forth once proposals start coming in.

Get a Free RFP Review Before It Goes Out

Most ERP mistakes are invisible to the people who wrote them. You are too close to the project to spot what is missing or unclear, but an experienced vendor will notice within minutes.

Before you send your RFP to market, we will review it for free.

Our team at WEDOWEBAPPS will look at your document and tell you:

  • Whether your scope is clear enough to get consistent, comparable proposals.
  • If your budget range is realistic for what you are describing.
  • What is missing that vendors will either assume or price as risk?
  • Whether your timeline is achievable based on similar projects we have delivered.

There is no pitch, no obligation, and no sales unless you want one. Just an honest review from a team that reads RFPs regularly and knows what makes them work.

Send us your RFP for a free review

WEDOWEBAPPS works with startups and product teams on software product development across web, mobile, and backend systems. If you have read this far, you are serious about getting the vendor selection right, and that is the kind of client we work with.

Web Application Penetration Testing Explained: Protect Your App Before It’s Too Late

Web Application Penetration Testing

How secure are your web applications, really? In a world where businesses run on web apps, from online banking to food delivery platforms, your digital presence is as secure as your weakest line of code. Cyberattacks on web applications are rising, with vulnerabilities being exploited every minute. The question is not if your web application will be targeted; it is when it will be targeted.

This is where web application penetration testing comes in. It is the process of simulating real-world attacks to identify loopholes before cyber attackers do. Whether you are a tech enthusiast, a cybersecurity professional, or a business owner handling sensitive customer data, understanding and investing in penetration testing is crucial for maintaining security.

Partner with a professional web application development company that offers security services to ensure your application stays secure, compliant, and trustworthy.

In this blog, we will talk about:

  • What web app pen testing really means,
  • Why penetration testing is important for all web apps of all sizes, 
  • The steps involved in the penetration testing process, 
  • Tools that professionals use for pen testing, and 
  • Best practices for pen testing that you can implement the right way. 

Let us dive into the technicalities of web app pen testing and how to secure your application before attackers find their way in.

Unsure If Your Web Application Is Truly Secure?

What is Web Application Penetration Testing?

Web application penetration testing, also known as web app pen testing, is a systematic process of evaluating the security of your web application by simulating real-world attacks. The goal is to identify vulnerabilities, weaknesses, and misconfigurations that malicious attackers could exploit to compromise the application or its infrastructure.

Key Aspects of Web App Penetration Testing

  1. Scoping: Define the scope of the test, which includes target applications, functionalities, and potential entry points. Scoping, these days, has become more dynamic, often incorporating AI-driven tools to identify high-risk areas. 
  2. Reconnaissance: Gather information about the target, like technologies used, architecture, and potential attack vectors. Advanced reconnaissance includes analyzing AI/ML-driven components and API ecosystems. 
  3. Vulnerability Assessment: Identify security weaknesses like SQL injection, cross-site scripting (XSS), insecure APIs, and misconfigurations. Nowadays, vulnerabilities in AI/ML models and serverless architectures are also prioritized.
  4. Exploitation: Safely exploit vulnerabilities to assess their impact and validate their existence. Modern exploitation techniques now account for zero-day vulnerabilities and advanced persistent threats (APTs). 
  5. Reporting: Document findings, risks, and remediation steps in a comprehensive report. Reports in 2025 often include interactive dashboards and AI-generated remediation recommendations. 

Pen Testing ≠ Vulnerability Scanning

While vulnerability scanners provide automated reports, pen testing includes manual analysis, creative thinking, and real-world simulation, making it more accurate and impactful.

Who Should Perform It?

  • Startups and B2B platforms looking to build trust with customers
  • B2C Companies dealing with financial or personal user data
  • Developers and DevOps teams integrating security into CI/CD pipelines
  • Cybersecurity students and professionals sharpening their offensive security skills

Pen testing is not just for enterprise companies. Whether you are growing a SaaS business or a developer experimenting with side projects, web application penetration testing is a protective way to build secure digital experiences.

Why is Web App Pen Testing Important for B2B and B2C Businesses?

Whether you are managing an online store, a SaaS dashboard, or a customer support platform, your web application is the gateway to your business. But it is also a prime target for cybercriminals.

From data theft to complete system compromise, a very simple overlooked vulnerability can trigger financial losses, legal issues, and irreparable damage to your brand reputation.

Real-World Risks for Businesses:

  • Data Breaches: Customer data, passwords, payment details, and internal documents are all at risk.
  • Compliance Violations: Non-compliance with GDPR, HIPAA, PCI-DSS, etc., can lead to heavy fines.
  • Service Downtime: A hacked or defaced website can cause business interruptions and lost sales.
  • Loss of Customer Trust: Today’s customers expect secure digital experiences, and they remember brands that fail them.

Security Stats That Matter:

  • 43% of cyberattacks target small to mid-sized businesses.
  • Over 50% of data breaches stem from web application vulnerabilities.
  • The average cost of a data breach in 2024 exceeded $4.5 million (IBM Report).

B2B Implications:

  • Secure web portals and APIs that handle B2B integrations.
  • Protect confidential contracts, invoicing systems, and third-party access. 
  • Maintain industry credibility and pass security audits for vendor qualification. 

B2C Implications:

  • Prevent misuse of personal data and payment credentials. 
  • Secure authentication flows like login, signup, and password resets. 
  • Avoid public backlash from social media exposure or negative press. 

For both B2B and B2C brands, web app pen testing is not a luxury; it is rather a necessity. It not only improves your technical defenses but also serves as a badge of trust and due diligence.

Penetration Testing Methodologies 

Not all penetration tests are created equal. The web app pen testing approach can change depending on what needs to be tested, how much access the tester has, and the specific goals of the test. To make sense of this all, cybersecurity experts follow proven methodologies that help simulate real-world attack scenarios in a structured way.

Pen Testing methods can be categorized based on level of information provided to the tester and the scope of the test. Let’s breakdown penetration testing methodologies in detail:

1. By Level of Information

a.) Black Box Testing

In this type of testing, the tester has no prior knowledge about the target system. The simulate a real-world attack scene, starting from initial access and working their way through to exploitation. This is the most realistic methods of pen testing but it is time-consuming and expensive at the same time.

b.) White Box Testing

The tester in this type of testing is given the full access to the target system’s information, which includes network maps, system configurations, and potentially even credentials. This allows for a more focused and efficient assessment of vulnerabilities.

c.) Gray Box Testing

In this approach, the tester has limited information about the target system, often including login credentials or a basic understanding of the network structure. This approach simulates an attack where the attacker has gained some initial access or information.

2. By Target

d.) Network Penetration Testing

This method focuses on identifying vulnerabilities within the organization’s network infrastructure, including servers, routers, and firewalls.

e.) Web Application Penetration Testing

This method assesses the security of web applications by identifying vulnerabilities like SQL injection, cross-site scripting, and other common web application web flaws.

f.) Physical Penetration Testing

This method involves physical attempts to breach the organization’s security, such as gaining access to buildings, bypassing security systems, or social engineering.

g.) Social Engineering Penetration Testing

This method involves exploiting human psychology to gain access to sensitive information or systems.

h.) Internal Penetration Testing

Simulates attacks from within the organization, potentially involving compromised credentials or insider threats.

i.) External Penetration Testing

Simulates attacks from outside the organization, targeting internet-facing assets.

h.) IoT Penetration Testing

Focuses on identifying vulnerabilities in internet-connected devices.

3. Other Methods

j.) Blind Penetration Testing

The tester operates with minimal information, mimicking a real-world attacker’s perspective.

k.) Double-Blind Penetration Testing

Neither the security team nor the testers know about the test, allowing for a realistic assessment of incident response capabilities.

l.) Targeted Penetration Testing

Involves close collaboration between the testers and the organization’s IT team, with clear communication about the scope and objective of the test.

Key Steps Involved in Our Web Application Penetration Test

The most common process of penetration testing for web applications includes a vulnerability scanner, which investigates and detects loopholes in your security, such as misconfiguration, unpatched software, SQLi, cross-site scripting, etc.

1. Planning Phase

Pen testing web applications begins by defining the scope, timeline, and people involved in the pentest. Our client and our team of experts, pen testers, decide on the scope together. In this phase, we decide oh which application has to be tested and what pentest to perform, internal, external, or both. We decide on the timeline for the whole process, which is an important step.

2. Reconnaissance Phase

During this phase, our pentesters gather information about the target web application and its environment. This helps customize the testing process and identify the potential weaknesses. In the second phase of pen testing, we also perform port scanning, service identification, vulnerability assessment, and other tasks.

  • Passive Reconnaissance: We start by passively collecting passively available information about the target with methods like DNS enumeration to find hidden functions and web scraping to extract the application’s information.
  • Active Reconnaissance: Then comes the next step, i.e., Active Reconnaissance phase in which our experts interact with the application to identify the weak entry points using port scanning and crawl through it to understand its functionality in detail.

Key Tools Used During Reconnaissance:

  • Astra Pentest 
  • Nmap
  • DNS Enumeration Tools like GoBuster, Aquatone, or Subfinder
  • Web Scraping Tools like Scrapy, theHarvester.

3. Vulnerability Scanning Phase

Since we now have the reconnaissance data, the next step in the stages of pentesting involves using automated tools to scan for known vulnerabilities. These tools compare the application against Common Vulnerabilities and Exposures (CVEs) databases and identify potential weaknesses in code, configuration, or dependencies.

Key Tools Used During Vulnerability Scanning

  • Open source scanners like Kali or Nikto to identify vulnerabilities such as SQL injection and cross-site scripting. 
  • Commercial scanners offering detailed reporting, integration with security tools, remediation guidance, and zero false positives for vetted scans. 

4. Exploitation

While vulnerability scanners offer a great starting point for penetration testing, manual exploitation is important for identifying more complex vulnerabilities and misconfigurations.

This plays an important role in the penetration testing process, where our pentesters manually exploit the target system to find business logic vulnerabilities, look for unique attack possibilities that could be harmful when combined, and identify each vulnerability’s critical rating.

Exploitation aims to understand the possible consequences of a successful real-world attack. This allows the business to prioritize remediation efforts accordingly.

Exploitation involves using various tools and techniques to gain unauthorized access to the system, steal data, or disrupt operations.

Key Tools Used During Exploitation:

  • Exploit frameworks like Metasploit, which is used to exploit specific vulnerabilities. 
  • Custom Scripts for zero-day vulnerabilities or those not covered by existing tools. 
  • Password cracking tools like JohnTheRipper can be used to crack hashed passwords occurring during the tests, if password spraying or other techniques fail to gain access. 

5. Reporting and Remediation

Once the exploitation phase has been completed, our team will provide you with a detailed report which will state all the findings. This report should include:

  • A description of each vulnerability identified. 
  • The severity of a vulnerability (based on CVSS scoring or other metrics).
  • The potential impact of exploiting the vulnerability. 
  • Step-by-step instructions on reproducing the vulnerability (for internal remediation teams).
  • Recommendations for remediation. 

Common Vulnerabilities Tested in Web App Testing

The main aim of web application penetration testing is to identify and exploit the real-world security flaws that the attackers could use to compromise your system. Many of these vulnerabilities are surprisingly common, and destructing if left unpatched.

Here is a breakdown of the most frequently targeted vulnerabilities in the penetration testing for web applications:

1. Injection Flaws

This category includes vulnerabilities like SQL Injection, Command Injection, and LDAP Injection, where untrusted data is sent to an interpreter as part of a command or query, leading to unintended execution.

2. Broken Authentication

This covers weaknesses in authentication mechanisms, like weak password policies, insecure session management, or vulnerable credential recovery processes, allowing attackers to compromise user accounts.

3. Broken Access Control

This involves flaws in how access to resources is restricted, potentially allowing unauthorized users to access or modify sensitive data or functionality.

4. Cross-Site Scripting

This vulnerability allows attackers to inject malicious scripts into web pages viewed by other users, potentially leading to session hijacking, data theft, or defacement.

5. Security Misconfiguration

This refers to improperly configured security settings in servers, frameworks, libraries, or applications, creating exploitable weaknesses.

6. Sensitive Data Exposure

This occurs when sensitive data, such as financial information or personal data, is not adequately protected both in transit and at rest, making it vulnerable to compromise.

7. Using Components With Known Vulnerabilities

This involves the use of outdated or vulnerable components, libraries, and development frameworks, which can introduce known security flaws into the application.

8. Cross-Site Request Forgery (CSRF)

This vulnerability tricks a victim into performing actions on a web application where they are authenticated, without their explicit consent.

9. Insecure Direct Object References (IDOR)

This happens when an application exposes a direct reference to an internal implementation object, allowing attackers to manipulate or access unauthorized resources.

10. Insufficient Logging and Monitoring 

A lack of proper logging and monitoring can hinder the detection and investigation of security incidents, allowing attacks to go unnoticed.

OWASP Top 10 References

Make sure your testing includes vulnerabilities listed in the latest OWASP Top 10, a globally recognized standard for web app security risks.

Why This Matters

These are not just theoretical risks; they are the exact methods used in thousands of real-world data breaches. Identifying them through a penetration test allows you to fix the flaws before attackers find them.

Struggling to Identify Hidden Vulnerabilities in Your Web App?

Popular Web Application Penetration Testing Tools

The right tools can make or break a web application pen test. Whether you are a beginner exploring ethical hacking or a cybersecurity team assessing enterprise-level risks, having the right arsenal is essential.

Here is a curated list of the most widely used tools and trusted web app penetration testing tools, categorized by purpose:

1.  Burp Suite

Type: Integrated platform for testing web app security.

Use Cases: Intercept requests, modify headers, perform scans, and brute-force testing.

Why is it Popular: User-friendly, powerful, and extensible with plugins.

Versions: Community (Free), Professional (Paid)

2. OWASP ZAP (Zed Attack Proxy)

Type: Open-source security testing tool by OWASP.

Use Cases: Scanning for vulnerabilities, spidering websites, and automated testing.

Why is it Popular: Beginner-friendly, actively maintained, great for automation.

3. Nikto

Type: Web server scanner

Use Cases: Detected outdated server software

Strength: Fast and simple CLI-based tool

Limitation: Limited GUI or modern visual feedback

4. Nmap

Type: Network mapping and port scanning

Use Cases: Discover live hosts, open ports, services, and OS fingerprinting

Bonus Use: Great for initial reconnaissance before web app testing

5. Metasploit Framework

Type: Exploitation framework

Use Cases: Launch known exploits, simulate attacks, build payloads

Ideal For: Advanced testers looking to go beyond scanning

6. W3AF (Web Application Attack and Audit Framework)

Type: Open-source pen testing tool

Use Cases: Audit for more than 200 types of vulnerabilities

Strength: Great automation with scripting support

7. Other Noteworthy Mentions

Acunetix: Commercial scanner with robust reporting and integrations

Nessus: Vulnerability scanner used for broader network security, including web apps

SQLMap: Focused specifically on finding and exploiting SQL injection flaws

Dirb/Dirbuster: For brute-forcing directories and hidden files in web servers

Comparison Table: Free vs Paid Pen Testing Tools

ToolFree VersionPaid VersionBest For
Burp SuiteYesYes (Pro)Professional and enterprise users
OWASP ZAPYesNoBeginners and automation
NiktoYesNoLightweight server scanning
AcunetixNo (Trial Only)YesComprehensive commercial testing
MetasploitYesYes (Pro)Advanced exploitation

Best Practice:

Use multiple tools in combination, for example:

  • Start with Nmap for mapping, 
  • Use ZAP/Burp for application scanning,
  • Confirm issues or exploit with Metasploit/SQLMap.

How Often Should You Perform Web Application Pen Testing?

Web application penetration testing is not just a one-time task; it is an ongoing process that should be part of your long-term security strategy. As your codebase evolves, new features are added, and user data increases, so does your risk surface.

So, how often should you test? The answer depends on your business type, compliance needs, and development lifecycle.

Recommended Frequency of Pen Testing

ScenarioRecommended Frequency
After major updates or releasesImmediately after deployment
For compliance requirements (eg, PCI-DSS)Annually or semi-annually
For high-risk apps (finance, healthcare)Every 3-6 months
For smaller businesses or static appsAnnually (at minimum)
During rapid development (Agile/CI-CD)Integrated into release cycles

Key Triggers for Re-Testing

  • Launch of a new feature or module 
  • Migration to a new platform or framework 
  • Discovery of a new exploit or 0-day vulnerability 
  • Change in compliance standards 
  • Post-remediation of previously found vulnerabilities

Align With Compliance Standards

Depending on your industry and geography, regulatory frameworks may require you to conduct regular penetration tests:

  • PCI-DSS: Annual testing for all merchants handling cardholder data
  • HIPAA: Security rule requires ongoing risk analysis (including testing)
  • GDPR: Encourages proactive security assessments to ensure “privacy by design”
  • ISO/IEC 27001: Recommends regular security audits and testing

Bonus Tip: Shift Left with DevSecOps

Integrate security early in the development cycle – not just at the end.

  • Use automated scans in CI/CD pipelines 
  • Combine static analysis (SAST) + dynamic testing (DAST) 
  • Schedule full-scale pen tests quarterly or biannually 

Bottom Line: Regular pen testing helps you stay ahead of attackers, meet compliance, and maintain customer trust. The more dynamic and data-heavy your app is, the more frequently you should test.

DIY vs Hiring a Professional Pen Testing Company

Once you have decided to invest in web application penetration testing, the next big question is: Should you do it in-house or hire experts?

Both approaches come with their own advantages, challenges, and ideal use cases. Let’s explore them:

DIY Pen Testing (In-House Team)

Pros:

  • Cost-effective for long-term internal testing 
  • Deep knowledge of your application’s architecture 
  • Useful for routine checks, quick validations, and dev-stage security 

Cons:

  • Requires skilled, trained cybersecurity personnel 
  • May lack access to advanced commercial tools 
  • Risk of bias or missed vulnerabilities 
  • Time-consuming for development teams 

Best For:

  • Startups and small companies with budget constraints 
  • Security-conscious dev teams with trained ethical hackers 
  • Continuous Integration (CI/CD) environments require quick, repeated tests. 

Hiring a Professional Pen Testing Company

Pros:

  • Unbiased third-party perspective 
  • Access to advanced tools, methodologies, and certified experts 
  • Comprehensive reports with risk scores, PoCs, and remediation guidance 
  • Meets compliance requirements more easily (eg, for audits) 

Cons:

  • Costly, especially for large applications 
  • Requires time for scoping and onboarding 
  • Might not be available for on-demand testing 

Best For:

  • Enterprises with mission-critical apps 
  • Businesses handling financial, healthcare, or personal data 
  • Companies preparing for compliance audits or vendor certifications 
  • Any organization lacking an internal security team

What to Look for in a Pen Testing Partner

  • Certifications: CEH, OSCP, CREST, CISSP 
  • Methodology: OWASP, NIST, custom frameworks 
  • Reporting: Should include PoCs, screenshots, CVSS scores, and remediation steps 
  • Post-testing support: Includes re-testing and consulting for fixes.

Best for Both Worlds?

Many organizations use a hybrid model:

  • Internal teams run frequent scans and patch testing 
  • External vendors perform annual or compliance-grade pen tests

If you are a growing business with complex apps, partnering with professional testers can uncover vulnerabilities your internal team might miss. But maintaining basic in-house testing skills helps you stay agile between major assessments.

Best Practices for Web Application Penetration Testing

Web application penetration testing is most effective when it is part of a proactive, ongoing security strategy, not a one-off event. Here are some of the best practices to help you get the most value out of your pen testing efforts.

1. Test Regularly and After Every Major Change

  • Schedule periodic pen tests (quarterly or annually)
  • Re-test after updates, feature rollouts, or third-party integrations 
  • Set up alerts for newly discovered vulnerabilities in your tech stack. 

2. Integrate Security Into Your SLDC (DevSecOps)

  • Shift security left, embed it into development from day one. 
  • Use Static (SAST) and dynamic (DAST) tools during coding and testing phases. 
  • Automate basic scans in the CI/CD pipelines for faster issue resolution.

3. Use a Mix of Manual and Automated Testing 

  • Automated scanners are great for speed and coverage. 
  • Manual testing catches logic flaws, business rule violations, and complex exploits. 
  • Do not rely on tools alone; human creativity matters in ethical hacking. 

4. Train Your Development and QA Teams

  • Conduct workshops on secure coding practices (example, input validation, auth management).
  • Encourage knowledge of the OWASP Top 10 vulnerabilities. 
  • Foster a security-first culture in product and engineering teams. 

5. Maintain Detailed Documentation

  • Keep logs of previous pen test results, fixes, and reports.
  • Track vulnerability trends over time to identify recurring risks.
  • Use reports to inform compliance audits and customer trust initiatives. 

6. Always Follow Up with Retesting

  • After fixes are applied, retest to confirm vulnerabilities are resolved. 
  • Include regression testing to ensure new changes have not broken old fixes. 
  • This reinforces accountability and long-term effectiveness. 

Bonus Tip:

  • Encrypt data at rest and in transit.
  • Implement role-based access controls (RBAC).
  • Use bug bounty programs to engage ethical hackers beyond your team.

Security is not a destination; it is a discipline. By following these best practices, businesses can turn penetration testing into a core pillar of trust, resilience, and digital growth.

Final Thoughts: Stay One Step Ahead of the Hackers

In today’s threat-filled digital landscape, web application penetration testing is no longer optional; it’s essential. From protecting sensitive user data to passing compliance audits, pen testing helps you uncover the vulnerabilities that matter before malicious actors do.

Whether you’re a tech-driven startup, a scaling B2B SaaS company, or a curious cybersecurity student, understanding the tools, methodologies, and best practices of pen testing empowers you to build safer, more resilient web applications.

The best part? You don’t need to be a large enterprise to get started. Regular testing, paired with a security-conscious development approach, can go a long way in reducing risks and improving customer trust.

Looking to develop a secure, high-performance web application? Partner with a company offering web app development services, prioritizing security from day one.

Don’t Wait for a Breach to Expose Your Web App’s Weaknesses

Supply Chain Software Solutions: Types, Requirements, and Features Explained

Supply Chain Software Solutions and Businesses Need

You can have great products, reliable vendor support, and a growing customer base, but if your chain is not proper, then everything does not give the impact.

Orders get delayed. Inventory goes missing. Costs increase quietly. And soon, your operations team is spending more hours fixing the issues than focusing on growth.

That is why more businesses are rethinking how they manage their supply chain and turning to supply chain management software to maintain the proper arrangement of all supply-related data.

This software does not provide that you can have any automation or dashboard support. It provides you and your team with access to a reliable system for tracking inventory, managing orders, coordinating with suppliers, and responding more quickly to any issues.

It does not matter if you are running a warehouse, shipping across various regions, or handling last-mile delivery. The right software for supply chain management will help you manage the issues before they become a huge problem. And if you need software as per preference and custom options, then you can connect with the software development company for development needs.

In this guide, we will break down the purpose and importance of support chain management software, its most useful features, available solutions, and more.

What Is Supply Chain Management Software and Why Is It Important?

Supply chain management software is an advanced solution that will help you in managing every part of the supply chain, from sourcing raw materials to delivering finished products.

It managed the operation like procurement, inventory, warehousing, and logistics with access to only one system. Makes it easier for you to track what is happening in your service and what things need your quick responses.

The importance of supply chain management software is:

  • Improving visibility
  • Reducing the manual work pressure
  • Supporting the faster operations
  • Accurate decision-making

Instead of relying on complex spreadsheets or an outdated system, you can access the supply chain software solution to access real-time data, automate routine work, and keep operations smooth.

As supply chain management becomes more complex when it comes to manual handling, the only solution is to have a centralized system. The right software provider will help you avoid delays, control costs, and improve overall services to maintain the growth of your business.

Now, let’s just figure out the best supply chain management software features.

supply chain delays and errors

Key Supply Chain Management Software Features for Business Efficiency

Key Supply Chain Management Software Features for Business Efficiency

The strength of every application lies in the added features. All the added features in any solution are specifically designed to maintain control, visibility, and speed in handling business operations.

Every supply chain management software features helps in improving day-to-day efficiency, so let’s just look at them to have more clarity.

1. Inventory and Warehouse Management

Allow you to monitor the inventory level with real-time access to different locations. Helps in avoiding overuse of stocks, preventing stockouts, and ensuring proper reordering.

2. Order Processing and Fulfillment

From receiving an order to managing returns to the customer, this order management feature streamlines the entire process. Automates the workflow while ensuring timely updates on orders and reducing the chances of manual errors. In addition, streamlined customer interaction management helps keep clients informed at each stage of the order journey, boosting transparency and satisfaction.

3. Supplier and Vendor Management

SCM solution maintains the centralized approach to manage supplier information, track performance, and manage contracts. Simplify the communication, support compliance, and help in making informed decisions.

4. Demand Forecasting and Planning

Accurate forecasting manages the data and allows for including the trend as per the market demand. Give support to better inventory planning, reduce waste, and ensure timely planning of procurement.

5. Logistic and Shipment Tracking

Allow to have the end-to-end visibility towards the status of the order, monitor shipment, identify the issues in delays, and maintain coordination to schedule the delivery more accurately.

6. Real-time Data and Reporting

SCM tools include dashboard and reporting features that allow users to gain more actionable insights. With this, your team can easily track KPIs and make operational adjustments as needed.

If you are looking for Software for supply chain management, then make sure that all these things are included to maintain the efficiency of your work.

Now, the key feature discussed, and let’s just review the SCM software benefits.

SCM Software Benefits Across Various Industries

Understanding the importance of supply chain management software goes beyond having the process of automation.

Businesses across the retail, manufacturing, and distribution sectors rely on it to eliminate inefficiencies, reduce delays, and improve coordination.

Here are the key SCM software benefits that show its practical value in everyday operations.

1. Cost Optimization in Operations

One of the important SCM software benefits is cost control in managing procurement, warehousing, and transportation. By using software for supply chain management, you can:

  • Avoid overstocking
  • Reduce manual errors
  • Eliminate duplicate processes

For example, a retail chain can lower excess inventory costs by using automated reorder handling, while a manufacturing unit can better handle raw materials and reduce production waste.

2. Faster Decision Cycles

Increases the ability to access real-time data from the central dashboard to speed up operational decisions. With supply chain management software features, you can:

  • Have real-time alerts
  • Reporting tools
  • Avoid delays caused by outdated information

For example, a distributor business can monitor delivery schedules and manage shipments with the improvement in service levels and response time.

3. Strong Supplier Relationships

Software for supply chain management makes vendor management more transparent. With this, the business can:

  • Monitor supplier lead times
  • Track delays
  • Maintain accurate records

Manufacturing industry can use this to reduce downtime by ensuring simple management of the vendors, improving product delivery time, and maintaining quality.

4. Improved Accuracy for Forecast

Built-in analytics and forecasting tools enable businesses to easily manage demand more accurately. This is helpful for:

  • Managing demand fluctuations
  • Include promotions
  • External factors

With this, retailers can plan stock usage with better confidence and manage storage and transport capacity for future needs.

These are just basic benefits associated with the supply chain management software, and having this in your business can help you maintain better efficiency.

Supply Chain Inefficiency Slowing Down Business

Technical and Business Requirements for SCM Software Integration

Identifying the right supply chain management software requirements helps you to have a smooth implementation or system upgrade.

These requirements can cover both technical integration needs and business workflow automation. Addressing them early ensures that you have access to better system adoption and long-term usability.

Let’s discuss each technical requirement in a better form:

1. ERP and CRM Integration Compatibility

Modern businesses run on multiple systems. To maintain the effectiveness of supply chain management software, it is important for businesses to connect with ERP and CRM platforms.

This compatibility is also essential for systems like account management software, where synchronized order, customer, and financial data help prevent mismatches and ensure consistent user experiences across departments.

This is required for:

  • Easy synchronization of order, inventory, and customer data.
  • Reducing manual errors in entry and the chances of duplication.
  • Support real-time decision-making.
  • Increase visibility across the procurement cycle.
  • Facilitate automated data exchanges with third-party tools.

At WEDOWEBAPPS, we are more specialized in building SCM software that meets your existing digital needs.

2. Workflow Customization Needs

Every company has its unique way of maintaining the workflow, and supply chain software solutions can easily manage that workflow configuration while handling supply chain management software requirements for operational continuity.

Your business requires this when you need:

  • Easy mapping of specific approval claims.
  • Support for a tailored dashboard.
  • Adaptation of complex processes.
  • Reduce friction from system mismatches.
  • Faster adoption in internal teams.

Being a custom software product development company, we are best at making solutions that quickly adapt to your processes.

3. User Role Management and Access Control

To ensure that your system’s security and process accuracy are maintained, role-based access can be the best part of software capabilities.

This is required when:

  • Assign permission for the different levels of users.
  • Having controlled access to sensitive data.
  • Help in maintaining data integrity.
  • Simplified compliance with industry regulations.
  • Tracking of audit-friendly activities.

Our development approach includes making a solution that follows all standard regulations.

4. Scalability and Data Security Considerations

A scalable and secure platform is one of the most important supply chain management software requirements for a growing business.

This is required for:

  • Management of the increased volume of data without performance issues.
  • Flexible architecture or global operations.
  • Better encryption, firewall protection, and secure logins.
  • Secure vendor and supplier communication
  • Meeting regulatory standards.

We build scalable and secure supply chain platforms ready to support long-term growth.

Types of Supply Chain Software Solutions and Their Use Cases

Types of Supply Chain Software Solutions and Use Cases

Businesses today rely more on the different supply chain software solutions based on the needs of their offered services. Whether it is handling demand forecasting, efficient order fulfillment, or cross-department coordination, all these are merged with the use of supply chain management software features.

For your reference, this is the detailed breakdown of core solution types, key functionalities, and their application.

Supply Chain Planning Software

These supply chain software solutions are more focused on handling future demands and help to avoid excess inventory or missed sales.

Key features:

  • Demand forecasting
  • Production planning
  • Inventory optimization
  • Scenario analysis

Use Case Example:

A fashion retailer uses this planning software to adjust their seasonal inventory based on trends and avoid a last-minute rush.

Supply Chain Execution Software

Supply chain execution software is used for handling real-time access to different product management and managing the fulfillment of operations more efficiently.

Key Features:

  • Order processing
  • Warehouse operations
  • Transportation management
  • Real-time shipment tracking

Use Case Examples:

A simple delivery service business can use execution software to reduce delays and ensure last-time delivery with better accuracy in route optimization.

End-to-End Cloud SCM Platform

This comes under the cloud-based platform, which offers an integrated solution to combine planning, execution, and accessible analytics.

Key Features:

  • Centralized dashboards
  • Real-time data sync across departments
  • Scalable infrastructure
  • Automated alerts and workflow

Use Case Example:

A grocery chain uses a cloud-based SCM platform to connect procurement, warehousing, and for faster delivery.

On-Premise SCM Systems

Can be installed directly on the company’s internal servers and are suitable for maintaining use of strict compliance or data control needs.

Key Features:

  • Custom workflow integration
  • Internal data hosting
  • Enhanced system control
  • Offline operational continuity

Use Case Example:

An industrial manufacturer chooses on-premise software to manage production planning and regulatory constraints.

For your efficient planning, here is a quick comparison table:

Feature/FactorPlanning SoftwareExecution Software
Primary FocusForecasting and schedulingReal-time operations and logistics
Core FunctionsDemand planning, inventory controlOrder fulfillment, shipping
Data RequirementPredictive models and historical dataReal-time operational data
Ideal forRetail, manufacturing (forecast-heavy)Logistics, eCommerce, warehousing
Integration NeedOften connects with ERP/BI toolsRequires WMS, TMS, and tracking tools
Deployment OptionsCloud, on-premiseCloud, on-premise

These discussed Supply chain execution software and supply chain software solutions are suitable for different needs, so make the plan accordingly, which one is needed by you. Now, you might be thinking about these software suppliers, so let’s just discuss that.

Top SCM Software Suppliers and Platforms

SCM Software Suppliers and Platforms

If your business is aiming to achieve better operational efficiency and more control over decision-making, then you can rely on the trusted supply chain management software suppliers.

For your reference, here are some of the widely used platforms, known for their advanced features and industry-specific capabilities.

PlatformKey CapabilitiesDeployment TypeBest Suited For
SAP SCM
  • Real-time supply-demand alignment
  • Integrated with SAP S/4HANA
  • Advanced analytics
  • Vertical-specific modules
On-premise & CloudEnterprises in manufacturing, pharma, and automotive
Oracle SCM Cloud
  • End-to-end visibility
  • Cloud-native logistics
  • AI-driven planning
  • Scalable for global operations
Cloud-onlyLarge-scale global supply operations
Microsoft Dynamics 365 SCM
  • Predictive insights via Azure
  • IoT-enabled tracking
  • ERP integration
  • Workflow automation
Cloud-first, hybrid availableMid to large businesses with an existing MS stack
Blue Yonder
  • Demand sensing
  • Real-time execution
  • Scenario-based planning
  • Native cloud tools
Cloud-firstRetail, logistics, and distribution-focused firms
Infor SCM
  • End-to-end planning
  • Industry-focused solutions
  • Workflow automation
  • CloudSuite options
Cloud & On-premiseManufacturing, distribution-heavy sectors

These are the common supply chain software solutions that you use in our business, and if you are not satisfied with these, you can connect with WEDOWEDAPPS for software development as per your business needs.

How WeDoWebApps Supports SCM Platform Integration

Our company has a strong and skilled team of software developers who will help in every way possible to integrate and customize leading supply chain management software suppliers like SAP, Oracle, and Microsoft Dynamics, and also build a custom solution for you.

It does not matter if you need a custom module, API integration, or any third-party connectivity; our development team will make sure that your SCM software aligns with the needs of your business goal or tech stack.

From setup to automation scripting, we are here to offer you a solution for seamless adoption and long-term scalability.

How Much Does Supply Chain Management Software Cost?

Understanding how much does supply chain management software costs is essential. It depends on the pricing models, your business size, operational needs, and the need for custom-built solutions.

There are several factors that affect the pricing model, and here is a discussion of the same to have a clearer expectation for business.

Licensing and Subscription-Based Models

  • Subscription (SaaS): Charges are typically monthly or annually, depending on the user or module expectations.
  • Licensing: This is a one-time cost, but it includes fees for updates and other support.
  • Modular Pricing: Cost varies by the number of needed different functional modules.

Cost by Business Size and Scope

  • Small Businesses: Cloud-based tools may start around $1000-$500 per month.
  • Midsize Companies: Pricing range may vary from $1000-$5000 per month, depending on solution complexity.
  • Enterprises: Full implementation of custom updates can cost around $100,000 annually or could be more.

Implementation and Support Pricing

  • Setup and Configuration: Initial setup can range from $5000 to $50,000 or more.
  • Training and Change Management: Optional services are priced by hourly or by project.
  • Ongoing Support: May include subscription or additional rates.

Custom Software Development Cost Range

  • Basic Custom SCM tools: $10,000 to $25,000 for specific modules and dashboards.
  • Advanced System: $30,000 to $100,000 or more based on scope, integration needs, and compliance requirements.
  • Factors Affecting Custom Cost: Number of users, features like AI or IoT integration, mobile access, and security.

clear breakdown for integration, development

Why Choose WeDoWebApps for Custom Supply Chain Software Development?

If you connect with our organization, then we bring you years of experience in building modern software custom to the unique needs of the client. Our team has delivered a scalable digital solution to businesses across multiple sectors.

With your proven domain expertise in logistics, warehousing, and retail, we help clients handle inventory flow, supplier coordination, and delivery operations with precision. No matter if it is integration with a legacy system or creating cloud-native, everything is efficiently handled.

Every solution that we build follows a business specification. We ensure that the software scales better and meets the performance benchmark in the different functions. Post-deployment, we do offer support to maintain reliability and performance.

Conclusion

Making use of the right supply chain software solution will help you to manage various aspects, which include streamlining operations, reducing delays, and improving inventory accuracy.

These technologies, whether they are supply chain execution software or planning tools, enable greater coordination and data-driven decision-making.

With a clear understanding of the importance of supply chain management software requirements and by comparing features, you will be able to select a platform that fits your goals.

The cost of supply chain management software may vary, but the long-term benefits in efficiency and control often outweigh the investment, especially when partnering with the right software solutions companyIt ensures you get expert guidance from platform selection to long-term optimization.

develop a business-specific SCM solution

mCommerce Development Explained: Features, Benefits, and Impact

mCommerce Development – The Smarter Way to Reach Customers

Scroll. Tap. Checkout. This is how customers shop today.

From ordering products online to booking appointments, everything has now been done with the use of mobile devices, and having one for your business can help gain the trust of customers.

If your business is still relying on a desktop experience or a generic mobile view, then you are leaving revenue on the table.

This shift has made mobile commerce (mCommerce) a priority for businesses that want to stay competitive. But you need to stay clear that building an application is not just about maintaining a clear presence, it is about creating a seamless, secure, and purpose-built solution that supports how users are behaving towards your mobile application.

For your business, if you want to invest in mCommerce development when you can partner with a company that offers custom eCommerce website development services to maintain the strong presence of your brand by including better services, features, software, and security practices.

If you want to know more about mCommerce development, then keep reading. This guide will give information on what is mCommerce development, why it is important, offered services, features, and software security practices to maintain an effective appearance.

want to launch mobile-first app or update outdated app

What is mCommerce and How Does It Work?

mCommerce stands for mobile commerce, but for you to include this in your business requires you to learn more about how it actually works for your business.

The mobile commerce definition includes the reference to buying and selling services with the use of smart mobile devices.

mCommerce functions by including the unique capability of mobile devices to maintain a smooth and immediate buying experience.

You can think of this way:

  • Mobile App: A dedicated app that will allow you to offer customers a highly optimized, fast, and personalized experience.
  • Mobile Website: Prepare the website, which is specifically designed to ensure a smooth browsing and purchasing journey.
  • Digital Wallets: Smooth integration of services like Google Pay or Apple Pay to have a simplified checkout.
  • Location-based services: Your business is supposed to send relevant offers or information based on the location of customers.
  • Push Notification: Allows you to inform customers directly about their purchases.

So here are basic details which allow you to have an understanding of how mCommerce works by making shopping incredibly convenient, fast, and personal, turning every mobile interaction into a potential sale.

Now you know, after knowing about this, you might have doubts about how it differs from eCommerce. So here is the difference between mCommerce and eCommerce

Difference Between mCommerce and eCommerce (and Why It Matters)

Here is the quick comparison table for you to know the actual difference between these two, and you should know which is the best eCommerce platform for your business:

FeatureeCommerce (Desktop/Web)mCommerce (Mobile/App)
Access MethodWebsite accessed via desktop or laptopMobile app or mobile-friendly website
Device UsedDesktop, laptopSmartphone, tablet
User BehaviorLonger sessions, planned purchasesQuick browsing, impulse buying
Speed of TransactionsSlower, involves more stepsFaster with one-tap payments and auto-fill
Typical FeaturesProduct search, filters, cart, checkoutVoice search, GPS, push notifications
Payment OptionsCredit/debit cards, internet bankingMobile wallets (GPay, Apple Pay), UPI, QR scan
PersonalizationLimited to browser activityApp-based tracking enables real-time targeting
Security FeaturesSSL certificates, basic loginFingerprint/Face ID, secure in-app transactions
Usage ContextMostly used at home or officeUsed anytime, anywhere while commuting, shopping, etc.

Why mCommerce development matters

  • mCommerce is not just like eCommerce on a smaller screen; it is a service that includes higher UX and different gestures to attract customers.
  • Include the various mobile capabilities to maintain a better shopping experience.
  • Allow reaching towards the expectations of customers and allow for knowing about the distinct behavior.
  • Offer with the benefit of prioritizing the needs of various features that maintain stronger loyalty, and drive higher conversions.

In short, eCommerce covers all the online selling options, and mCommerce specializes in maintaining a higher-performance appearance in attracting more customers.

Why mCommerce Development Is a Growth Opportunity

The shift towards the use of mobile devices is not the primary activity; it is a better strategy for businesses to prioritize a mobile-first strategy. If your company is maintaining, staying competitive, investing in mCommerce development could be a better option.

It gives a direct response on how the customer is behaving with their browser, shopping online, and engaging with brands.

Whether you are retail, services, food delivery, or B2B commerce, having a proper functioning mobile presence to maintain better accessibility towards how your website responds towards business growth. And that’s exactly what mobile commerce, or mCommerce stands for.

Below are the key reasons why businesses are rapidly adopting custom mCommerce development and how it is helping them grow.

Mobile Usage and Shopping Behavior Trends

Various statistics show that mobile devices are now dominating how people purchase and use the internet. And also, there has been a shift in consumer behavior.

According to multiple market reports, over 70% of online transactions are now initiated or completed with the use of mobile devices. More consumers are spending the maximum amount of time on their mobile devices, which appears to play an important role in shopping.

mCommerce app development allows businesses to design experiences around customer behavior. It allows you to maintain the attraction of customers to shop in fewer steps, receive instant updates, and complete transactions with a saved card or digital wallet within seconds.

By aligning with how your customers actually shop today, you can reduce friction and improve conversion rates.

Business Benefits: Conversion Rates, Customer Retention, and Sales Uplift

When you invest in a well-planned mobile commerce solution, the result often goes beyond just offering simple mobile access. Here is how:

  • Higher conversion rates due to simplified navigation and simpler checkout.
  • Better customer retention with app-exclusive offers, a loyalty program, or quick updates.
  • Increased average order value with personalized recommendations for the users.
  • Improved operational efficiency with the smooth integration of CRM or payment systems.

With the right mobile commerce software, you can also gain access to real-time analytics to track user activity and optimize the app experience.

business need a mobile-friendly app

Example of Businesses Using Mobile Commerce Successfully

Many brands across industries have seen measurable success after adopting mobile commerce development services:

  • Retail Chains: Global fashion brand to offer customers push alerts and sync user activity.
  • Grocery Delivery app: For offering ease towards quick recorders, tracking delivery time, and offering geo-targeted deals.
  • B2B Wholesale: Handling the placement of bulk orders, managing invoices, and accessing pricing tiers with ease.

Each of these examples shows how customer mCommerce development can help you with shaping the specific goals to improve sales, streamline operations, or strengthen customer trust.

Core Features Businesses Need in an mCommerce App

Features Businesses Need in an mCommerce App

When you are planning to have an mCommerce app for your business, you should maintain a clear focus on speed, ease of use, and customer engagement.

Here are the essential features every business should consider when developing a mobile commerce solution:

  • Mobile Optimized Product Catalog

    • Clean layout for small screens and easy visibility of the product.
    • Smart filter options and category options to maintain a smooth search.
    • Higher UI/UX with better and simpler options for zooming products.
  • Fast and Simplified Checkout

    • Simpler option for handling the checkout, along with a smooth run.
    • Automatic filling of address and payment forms for maintaining accuracy.
    • Integration of the smooth payment option as per customer preferences.
  • Push Notification and Personalized Messaging

    • Real-time alerts on adding offers, new arrivals of products, and restocks.
    • Adding a quick reminder for the incomplete purchase or cart abandonment.
    • Access to targeting promotion ads based on user behaviour. 
  • Real-time Tracking and Inventory Management

    • Live status on the updates of the product availability.
    • An in-app order tracking option to give estimated delivery updates.
    • Notification for order status with the changes in place.
  • Secure Payment Integration

    • Support for the various possible payment systems that are supported by customers.
    • End-to-end encryption of the payment while maintaining security.
    • Follow PCI-DSS compliance and tokenization support.
  • User Account Management

    • Profile creation and login via email or phone.
    • Automatically saved addresses, wish lists, and payment methods.
    • View and reorder from past purchases or a direct option for purchase.
  • Flexible Admin Dashboard

    • Order and inventory management with simple methods.
    • Simpler analytics to know about generated sales and user behavior.
    • Smooth integration with CRM, ERP, or POS systems.

By adding these features, you will be able to maintain the higher performance of your mobile commerce app. This only improves the buying experience but also offers your team access to tools to manage various operations smoothly.

Custom mCommerce Development That Fits Your Business Goals

Having the generic mobile apps may seem like a quick fix, but these applications often fall short when it comes to meeting the real business needs. From limitations in features to integrating challenges and other limitations can restrict how effectively you operate and scale.

That is where the custom mCommerce development proves its greater value. It allows you to build a mobile commerce solution that is designed to manage processes, customer behavior, and long-term goals.

Whether you want to launch an app that handles D2C storefront, manages complex B2B operations, or offers subscription-based services, having custom eCommerce web development practices can align your mobile experience with a built purpose.

To be more clear about what is mCommerce development, know why the standard mobile app service fails to deliver what customers are expecting.

Why Standard Mobile Apps Often Fail to Deliver

Most of the pre-built platforms offer a fixed template or limited customization. They may offer support for managing the basic mCommerce app development, but this may rarely offer the flexibility required for including features like personalized checkout flows, live inventory syncing, or a custom loyalty program.

To meet the specific needs, you need to include the multi-location inventory, role-based pricing, or third-party logistics to maintain the efficiency of the platform.

Custom mobile commerce development services provide full control over the need to build a solution that matches your structure and customer expectations.

If your business is also in need of that one platform, you can connect with the mobile development company to prepare the app for your needs.

Building Industry-Specific Mobile Commerce Solution

No two industries use mobile commerce in the same way. This is why there is no common app for all businesses.

Custom mobile commerce software allows you to build features feature-rich app that is relevant to your sector:

  • For retail businesses: Build an app with advanced filters, product quick views, and seamless payment options.
  • For B2B operations: Implement account-specific pricing, order approval workflows, and integration of the existing system or CRM.
  • For grocery and delivery apps: Add features like scheduling deliveries, repeat orders, address validation, and stock visibility.
  • For subscription-based services: Enable options like auto-renewal, subscription plan management, and flexible billing cycles.

A well-planned mCommerce development strategy allows you to meet customer expectations while supporting internal efficiency.

build an app including all the features

Custom Dashboards, User Flows, and System Integrations

Your business does not need a front-facing app; it also needs an effective backend to support day-to-day operations. With custom mCommerce development, the admin dashboard is designed to manage how the team is working.

  • You can manage how the team is handling product listing.
  • Track user activity.
  • Generate sales reports.
  • Manage single-location inventory.
  • Sync with the available system, like ERP.

With the mobile commerce solution, you will be able to improve customer journey, onboarding checkout, and interaction related to business logic.

Our Mobile Commerce Development Services

We help businesses turn the mobile experience into a scalable digital solution. Our mobile commerce development services are more aligned to help you meeting operational needs, customer expectations, and needed growth.

Here is what we follow:

1. Strategy, Consulting, and Architecture Planning

  • Define your business goals or needs as per the market.
  • Recommend with best platform (iOS, Android, or both) and tech support.
  • Align your mCommerce architecture with maintaining flow and scalability.

2. UI/UX Design and Prototypes

  • Design a mobile-first interface to support faster browsing.
  • Create prototypes to manage the user journey.
  • Ensure consistency to maintain your brand appearance.

3. Full-Cycle App Development (iOS, Android, PWA)

  • Build a secure and high-performing mCommerce app.
  • Include features like order tracking and push notifications.
  • Use a framework like Flutter, Kotlin, or React Native.

3. Integration with POS, ERP, and Payment Systems

  • Connect your app with an existing POS, CRM, and ERP system.
  • Integrate secure payment gateways.
  • Maintain data accuracy across all systems.

4. Post-Launch Support and Continuous Improvements

  • Monitor app performance and fix bugs.
  • Handle feature enhancements and security updates.
  • Offer long-term support to help you scale your mobile commerce solution.

have a scalable app

Choosing the Right mCommerce Solution for Your Business

You must choose the right mCommerce solution partner that allows you to maintain the effectiveness of business operations. Allow you to plan the application to meet customer service and plan for your growth.

From technology choices to business models, the discussion options will help you to evaluate what fits best.

Native App, Web App, or Hybrid – Which One Works for You?

  • Native Apps – Offer faster performance and include advanced features. Ideal for businesses that want full control or a premium user experience.
  • Web Apps – Include with the different browser-based services, easy to maintain, and suitable for businesses testing mCommerce with limited investment.
  • Hybrid Apps – Combine both, offer faster development, and cross-platform support. Great for businesses that have limited time and budget for apps.

Choosing the right from for application gives a better impact for maintaining the long-term visibility of apps and increases the ability to deliver a better user experience.

Building for Scalability: Single Store, Multi-Vendor, or Franchise

  • Single Store Setup – Suited for managing the local businesses or niche brand, allows for fulfilling customer needs with a mobile presence.
  • Multi-vendor Platforms – Works effectively for selling products in multiple marketplaces, managing multiple payments, and eCommerce logistics.
  • Franchise-based Models – Allow for meeting the needs of features that are specific to the brand and simplify management.

Your custom mCommerce development plan should be effectively aligned with your business structure and plan for maintaining the scalability of your business.

Monetization Options and Subscription Models

  • In your app support option, of in-app purchases, tiered product pricing, or membership plan options.
  • For content-based business or services that include recurring payment or auto-renewal options.
  • Have a well-planned mobile commerce software that allows for easy setup of offers, bundles, and discount options to add value.

Choosing the right monetization approach to ensure your mCommerce development is more profitable from the start.

Mobile Commerce Security Features Essentials for Businesses

If you want to develop an application for your business, then it is essential to include a stronger security system to build trust and ensure privacy.

Keep investing in the mobile commerce solution or the company that prioritizes the inclusion of core security features.

Here are a few things that you can check whether it is followed when processing mCommerce app development:

Protecting user data and transactions

  • Use of SSL encryption to maintain the safety of data and payments.
  • Option for adding a minimum of customer information 
  • Applying restrictions across user roles.

PCI-DSS Compliance and Data Encryption

  • mCommerce development services should follow PCI-DSS standards.
  • All transactions and information should be encrypted.
  • Reduced vulnerability with the up-to-date development methods.

Multi-Factor Authentication and Secure APIs

  • Addition of an extra layer of security.
  • Use of more distinct factors to verify customer identity.
  • More secure APIs to maintain access to unauthorized practices.

Secure Backend and Infrastructure Management

  • Regularly update the server and close known vulnerabilities.
  • Use of a firewall and threat detection system to monitor backend activity.
  • Ensure cloud services follow strict security.

Including these measures during custom mCommerce development ensures that your mobile commerce app is both functional and trustworthy, providing peace of mind for your business and your users.

Mobile Commerce Software and Technology Stack

Mobile Commerce Software Technology Stack

Mobile commerce software cannot be designed effectively with a simpler development; it requires the use of proper technology, and the need for a skilled eCommerce developer who can prepare the app, which is scalable and effective.

A strong technology stack supports secure, responsive, and fully customized mCommerce development from the frontend experience to backend operations.

Here are the key components of mCommerce software and tech stack:

  • Frontend Frameworks – Include various frameworks like React Native, Flutter, Swift, or Kotlin. These are responsive to all iOS, Android, or cross-platform use.
  • Backend Technologies – Manage the server, data processing, and use APIs that are essential for mCommerce app development.
  • Cloud and Hosting Services – Choose a reliable cloud infrastructure, like AWS, Google, and ensure that the app is handling real-time data easily.
  • Additional Tools – these tech stacks are required in the inclusion of various options like payment gateways, CRM, and more, which are:
    • Payment system for secure online payments.
    • CRM for managing customer data and interactions.
    • Inventory management for optimizing the stock.
    • Marketing automation tools.
    •  Analytic and reporting tools for managing tasks.
    • Customer support to give real-time support.

A well-chosen tech stack doesn’t just support your app today; it ensures your custom mCommerce solution can evolve as your business grows.

How We Deliver mCommerce Projects

At WEDOWEBAPPS, we make sure that we follow all the processes which is needed to builḍ a stronger presence of your brand.

Our approach towards mCommerce development is structured, scalable, and specific to the business.  With each step, we ensure that the mobile commerce solution is secure, user-friendly, and aligned with your goal.

Here are the steps that we follow:

Step 1: Business Understanding

We understand your business needs and define the operation to have a custom mCommerce development plan.

Step 2: Planning and Tech Stack

Make the right choice for mobile commerce software, platform, and integrations to fit your needs.

Step 3: UI/UX Design

We design a clear, user-friendly interface that gives support to have smooth navigation and fast checkout.

Step 4: Development and Integration

We build and connect your mCommerce app to systems like CRM, ERP, and payment gateways.

Step 5: Testing and Launch

We test across devices for performance and security before publishing the app.

Step 6: Ongoing Support

Post-launch, we manage updates, monitor performance, and scale as your business grows.

If you find these steps to be reliable for your app, then you can consider WEDOWEBAPPS.

Ready to Build a Business-Centric Mobile Commerce App?

Mobile commerce development is the practical approach to maintaining the accuracy of businesses that want to reach more customers and simplify transactions.

Whether you’re managing a retail store, B2B platform, or subscription service, the right mCommerce solution can help you operate more efficiently and deliver a better buying experience.

With custom mCommerce development, you gain full control over design, functionality, and scalability. So, plan the needs of your app accordingly.

planning to take your business mobile-first